
2 posts tagged with "kubernetes"

View All Tags

Cache-Aware Routing for Self-Hosted Models
Yassin Kortam
Senior SWE @ LiteLLM

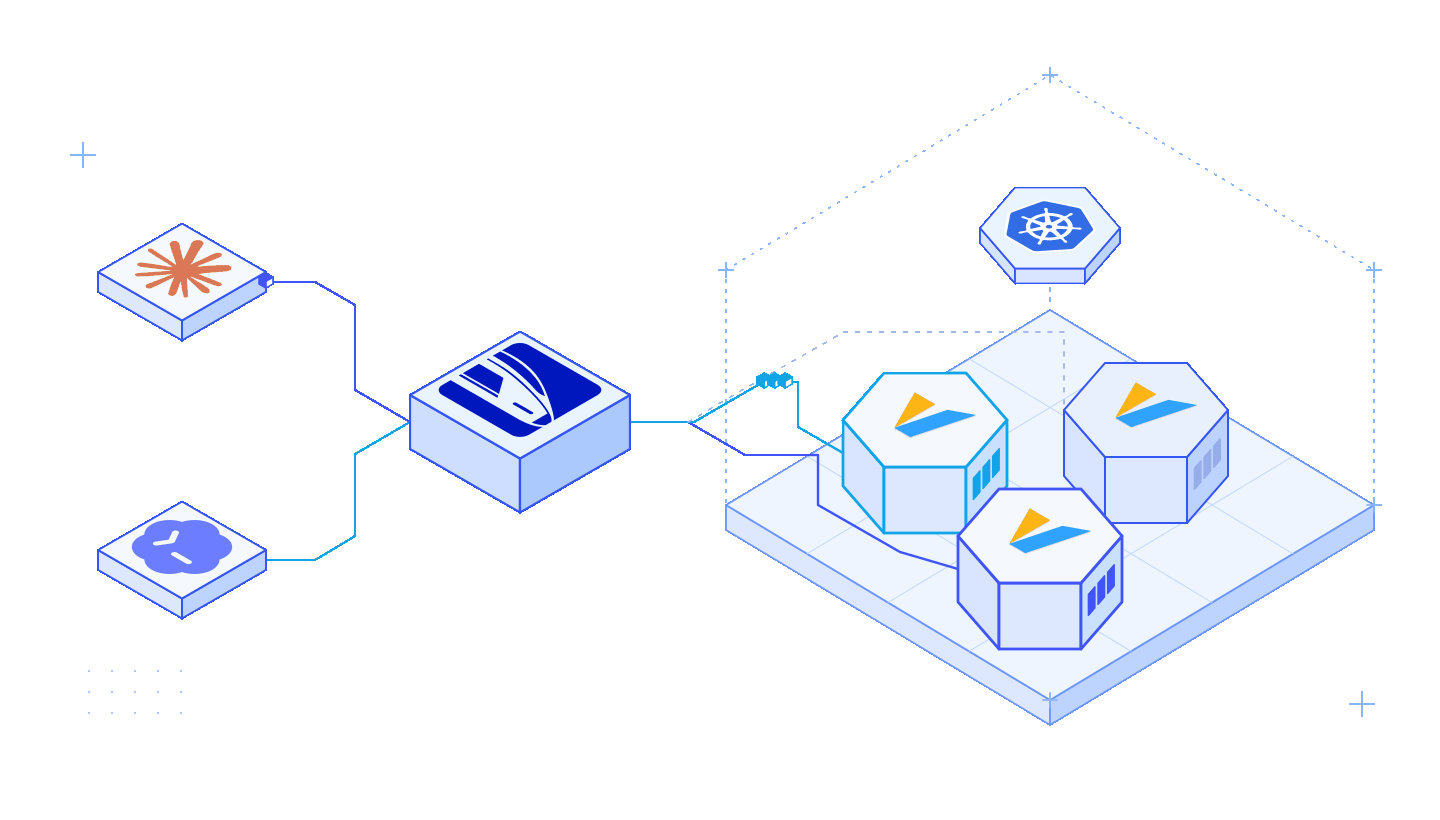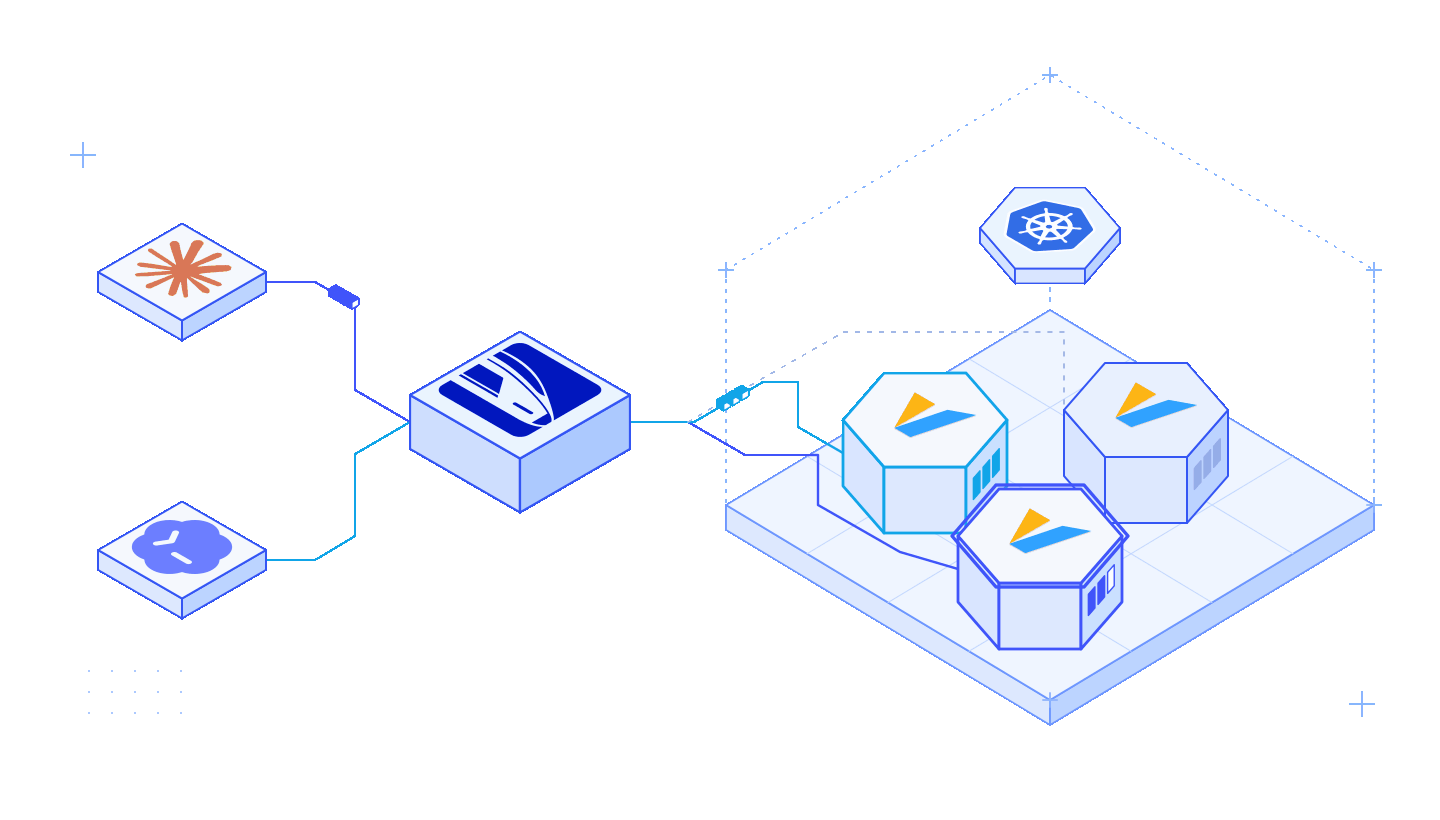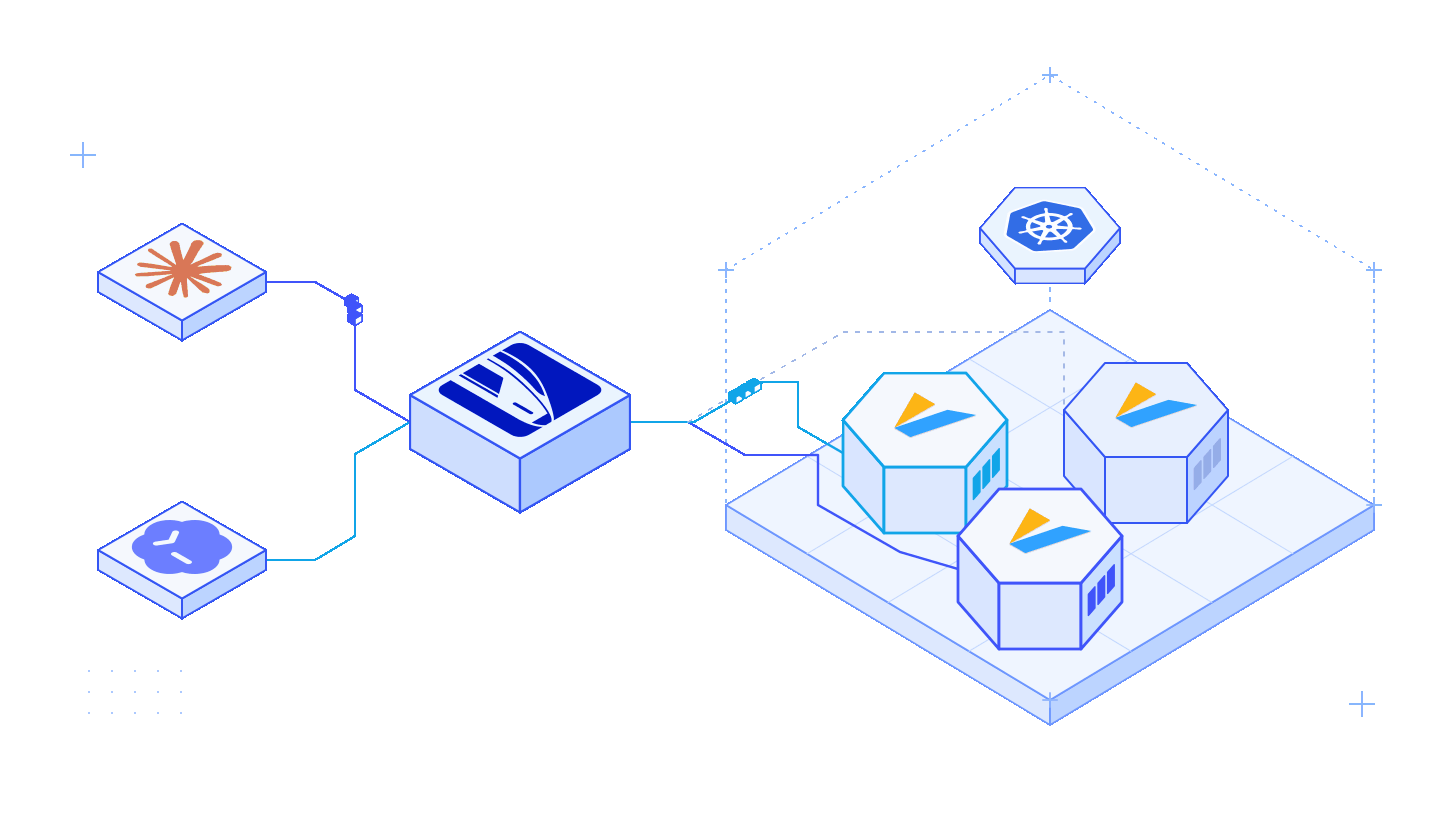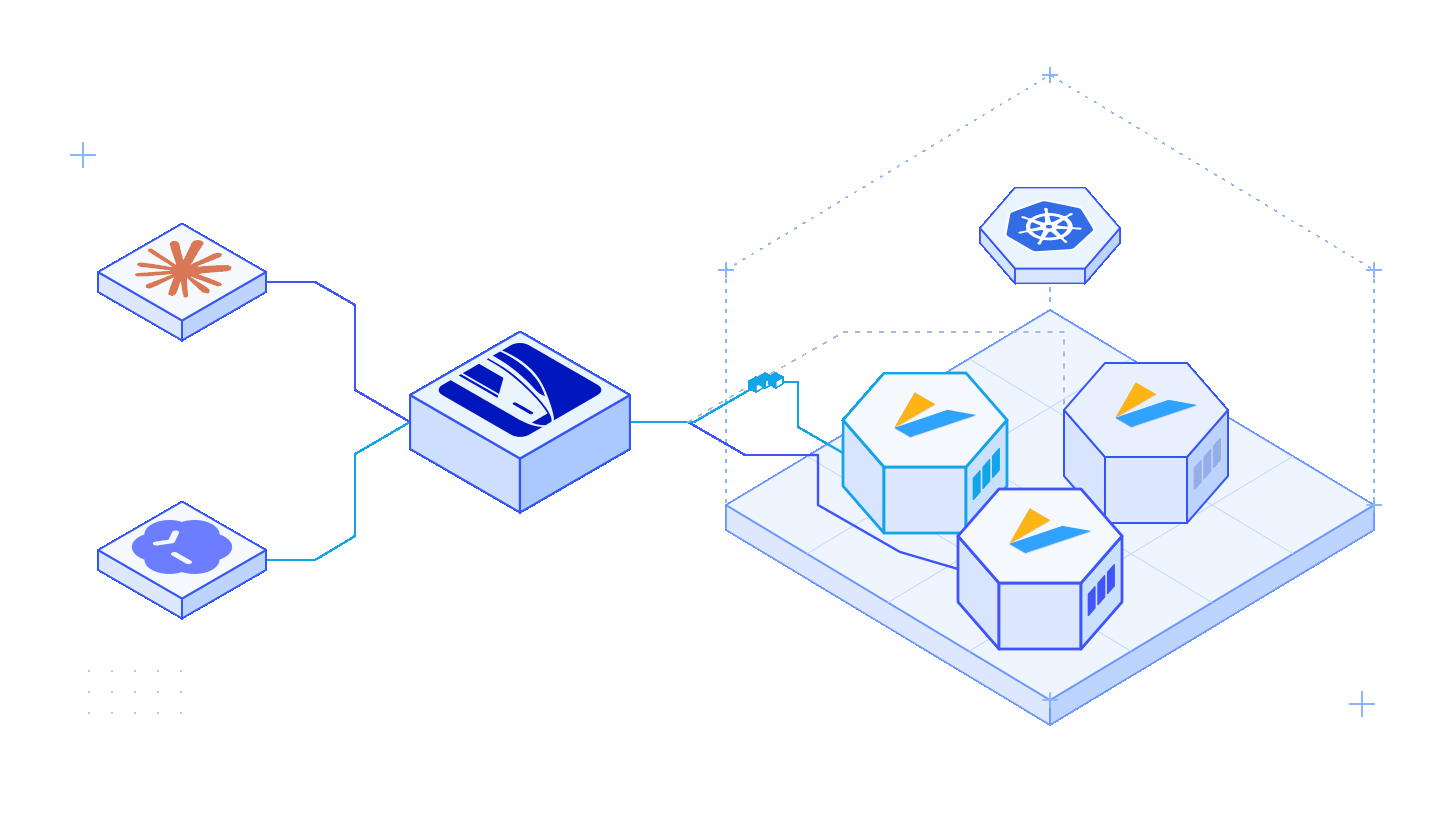
Claude Code and Codex requests pass through the LiteLLM gateway and return to the same vLLM pod for each session, allowing cached prompt prefixes to be reused.

LiteLLM now supports cache-aware routing for self-hosted inference on Kubernetes. Within a deployment, requests from the same session go to the same GPU pod. This lets vLLM reuse cached prompt prefixes across turns.

Agent requests often share system instructions, tool definitions, and conversation history. When requests reach different pods, each pod may process the same prefix again. Session affinity helps reuse that work.

Announcing Componentized Deployments

Yassin Kortam
Senior SWE @ LiteLLM

Last Updated: May 2026

The LiteLLM proxy container does 2 very different things. It's an LLM data plane, /chat/completions, /v1/messages, embeddings, passthroughs, where latency is measured in single-digit milliseconds of overhead and traffic is high-volume and bursty. It's also a management control plane for keys, teams, SSO, audit logs, and the spend/usage analytics that power the dashboard, where a single request can scan millions of rows.

Run both on the same event loop, and the slowest thing the control plane does sets the reliability floor for the fastest thing the data plane does. This post is about how we've improved LiteLLM's reliability at scale by offering a componentized deployment model.