10 posts tagged with "reliability"

View All Tags

OCR uses Rust by default starting with v1.102.0-rc.1

Yujong Lee
Senior SWE, LiteLLM

Starting with LiteLLM v1.102.0-rc.1, OCR runs on Rust by default.

No action required​

Continue using the existing OCR API:

import litellm

response = litellm.ocr(
model="mistral/mistral-ocr-latest",
document={
"type": "document_url",
"document_url": "https://arxiv.org/pdf/2201.04234",
},
)

The same default applies to asynchronous OCR calls. Gateway users get the Rust path automatically on upgrade too.

Opt out when needed​

Set LITELLM_RUST=0 to disable the Rust path for a process:

export LITELLM_RUST=0

You can also opt out for the current Python process before making OCR calls:

import litellm

litellm.rust(False)

What is the performance impact?​

TL;DR: When proxy CPU is the bottleneck, Rust sustains more OCR requests per second.

How we tested​

We measured proxy overhead, not end-to-end OCR latency. Each path ran in a fresh container with v1.102.0-rc.1, one proxy worker, one CPU, 2 GiB of memory, and a local mock provider. Python and Rust used the same image and limits; only LITELLM_RUST changed, and the order alternated across six paired rounds for each upload size.

Rust raises the CPU-limited proxy ceiling​

On one CPU, median throughput moved from 143.6 to 211.7 RPS at 1 MiB (1.48x) and from 21.6 to 36.2 RPS at 8 MiB (1.69x). Each gain is the median of the six within-round Rust/Python ratios.

Six paired rounds on one CPU. Hover a point for its exact value. Source: the published primary-trial CSV.

Both paths used 97% to 99% of their one-CPU allowance. This supports a higher OCR proxy throughput ceiling when proxy CPU is the bottleneck. It does not mean that a real OCR request finishes 1.69x faster; provider latency usually dominates end-to-end latency.

Absolute RPS varied as load on the shared development host changed. The paired rounds preserve the more useful signal: which implementation was faster under nearby conditions.

The advantage depends on the bottleneck​

We ran a few extra checks to see where the main result holds and where it stops. The charts show one run each and the exact numbers moved between reruns, so read them as rough boundaries rather than precise numbers. The direction of each result held.

The gain appears only when proxy CPU saturates​

Single run. Hover a point for its exact value.

We added a 100 ms delay to the mock provider so that waiting on the provider, not the proxy, could become the bottleneck. At concurrency 8 it did: the proxy sat mostly idle and there was no measured Rust gain. At concurrency 64, enough requests were in flight that proxy CPU saturated again and the gain returned.

Above Python's ceiling, requests queue​

Single run.

The primary benchmark fixed concurrency and measured each path's ceiling. This check instead offered a fixed thirty 8 MiB requests per second, which is above Python's measured ceiling at that size and below Rust's. Rust completed every arrival with CPU to spare, so latency stayed in the tens of milliseconds. Python's CPU saturated, requests queued, p95 latency climbed into seconds, and it used roughly twice the memory.

June Townhall Updates: 94 Bug Fixes, OCR + Realtime are in Rust, and a Zero-Regression Commitment

Krrish Dholakia
CEO, LiteLLM
Ishaan Jaffer
CTO, LiteLLM

Thank you to everyone who joined our June town hall.

Three numbers capture the month: 24 security fixes, 94 bug fixes, and 78 feature commits. The sections below break each one down, alongside our public commitment to zero reported regressions and the gradual migration of the LiteLLM gateway to Rust.

Migrating LiteLLM to Rust - Building the Fastest and Litest AI Gateway

Ishaan Jaffer
CTO, LiteLLM

Last Updated: June 2026

Over the past year, we have heard the same thing from our users and our community: they want the fastest, most lightweight AI gateway they can run. We have heard you. We are addressing it by moving LiteLLM to Rust, and committing to sub-1ms overhead with a sub-100MB memory binary you can deploy. By the end of this migration, you will get a pure Rust server that can serve 100% of your AI traffic, with every hot path operation, including auth and rate limiting, running in Rust.

Want to help us build it?

We are opening an early beta and want to work directly with teams who care about a fast, lightweight gateway. If that is you, sign up here and we will get you testing the Rust gateway in your own stack, with a direct line to our team.

The reason it matters: under real load, CPU and memory climb with concurrency, and pods get OOM-killed at the worst time. Today the LiteLLM Python proxy peaks around 359MB of memory under load, and that cost multiplies across every pod, region, and retry you run.

We are already seeing the payoff in benchmarks. The Rust gateway serves about 15x the throughput (453 to 6,782 requests per second) on about 11x less memory (359MB to 32MB), and cuts per-request overhead from about 7.5ms on the Python path to about 0.05ms, well under the 1ms we commit to.

What you get​

You deploy a single Rust binary. It uses about 65MB of memory, gateway overhead stays under 1ms, and nothing in your setup changes: same config.yaml, same database, same client API, same providers. You keep LiteLLM's coverage of 100+ LLM providers behind one OpenAI-compatible API, with /chat/completions, /messages, /responses, and every other LLM endpoint LiteLLM supports today, now as the fastest and most lightweight LLM gateway you can self-host.

This is not a v2 and not a rewrite. There is no new major version to migrate to and nothing for you to change. The runtime under the hot path gets faster and lighter while your config stays exactly where it is.

We ship this the careful way. Each route moves to Rust only after it passes our full parity and end-to-end test suite, and it runs in production before the next route starts. Stability is the priority, and we target zero regressions on every release.

Announcing Componentized Deployments

Yassin Kortam
Senior SWE @ LiteLLM

Last Updated: May 2026

The LiteLLM proxy container does 2 very different things. It's an LLM data plane, /chat/completions, /v1/messages, embeddings, passthroughs, where latency is measured in single-digit milliseconds of overhead and traffic is high-volume and bursty. It's also a management control plane for keys, teams, SSO, audit logs, and the spend/usage analytics that power the dashboard, where a single request can scan millions of rows.

Run both on the same event loop, and the slowest thing the control plane does sets the reliability floor for the fastest thing the data plane does. This post is about how we've improved LiteLLM's reliability at scale by offering a componentized deployment model.

Incident Report: Prisma DB Reconnect Blocks the Event Loop and Kills Liveliness

Yuneng Jiang
Senior SWE @ LiteLLM

Date: April 2026 Duration: Multiple incidents across customer deployments before fix landed Severity: High; surfaced as full proxy outages in Kubernetes Status: Resolved

Note: This fix is available starting from the release that contains PR #26225 (merged April 29, 2026).

Summary​

When the upstream Postgres database became unreachable, the LiteLLM proxy's Prisma reconnect path called await self.db.disconnect(). Under prisma-client-py that call invokes a synchronous subprocess.Popen.wait() on the Rust query-engine subprocess. Because wait() does not yield, the asyncio event loop froze for as long as the engine took to shut down, typically 30–120 seconds in production when the engine was stuck on TCP close operations against the unresponsive database.

While the loop was frozen, no coroutines ran, including /health/liveliness. Kubernetes liveness probes timed out and the kubelet SIGKILLed the pod. From the operator's point of view the proxy looked dead even though the underlying issue was a transient DB outage that the reconnect logic was supposed to ride through.

Impact: Any customer whose Postgres briefly became unresponsive saw proxy pods get killed and restarted instead of degrading gracefully and reconnecting once the DB came back. Reported externally by FLock and reproduced internally.

Making the AI Gateway Resilient to Redis Failures

Ishaan Jaffer
CTO, LiteLLM

Last Updated: April 2026

Enterprise AI Gateway deployments put Redis in the hot path for nearly every request: rate limiting, cache lookups, spend tracking. When Redis is healthy, the latency contribution is single-digit milliseconds, invisible to end users. When it degrades, a production AI Gateway needs to stay up regardless.

Running LiteLLM at scale across 100+ pods means designing for failure modes before they appear. The easy case is Redis going fully down: fail fast, fall through to the database, continue serving requests. The hard case, the one that takes down gateways, is a slow Redis: still accepting connections, still responding, but timing out after 20-30 seconds per operation.

Improve release stability with 24 hour load tests

Alexsander Hamir
Performance Engineer, LiteLLM
Krrish Dholakia
CEO, LiteLLM
Ishaan Jaffer
CTO, LiteLLM

LiteLLM Observatory

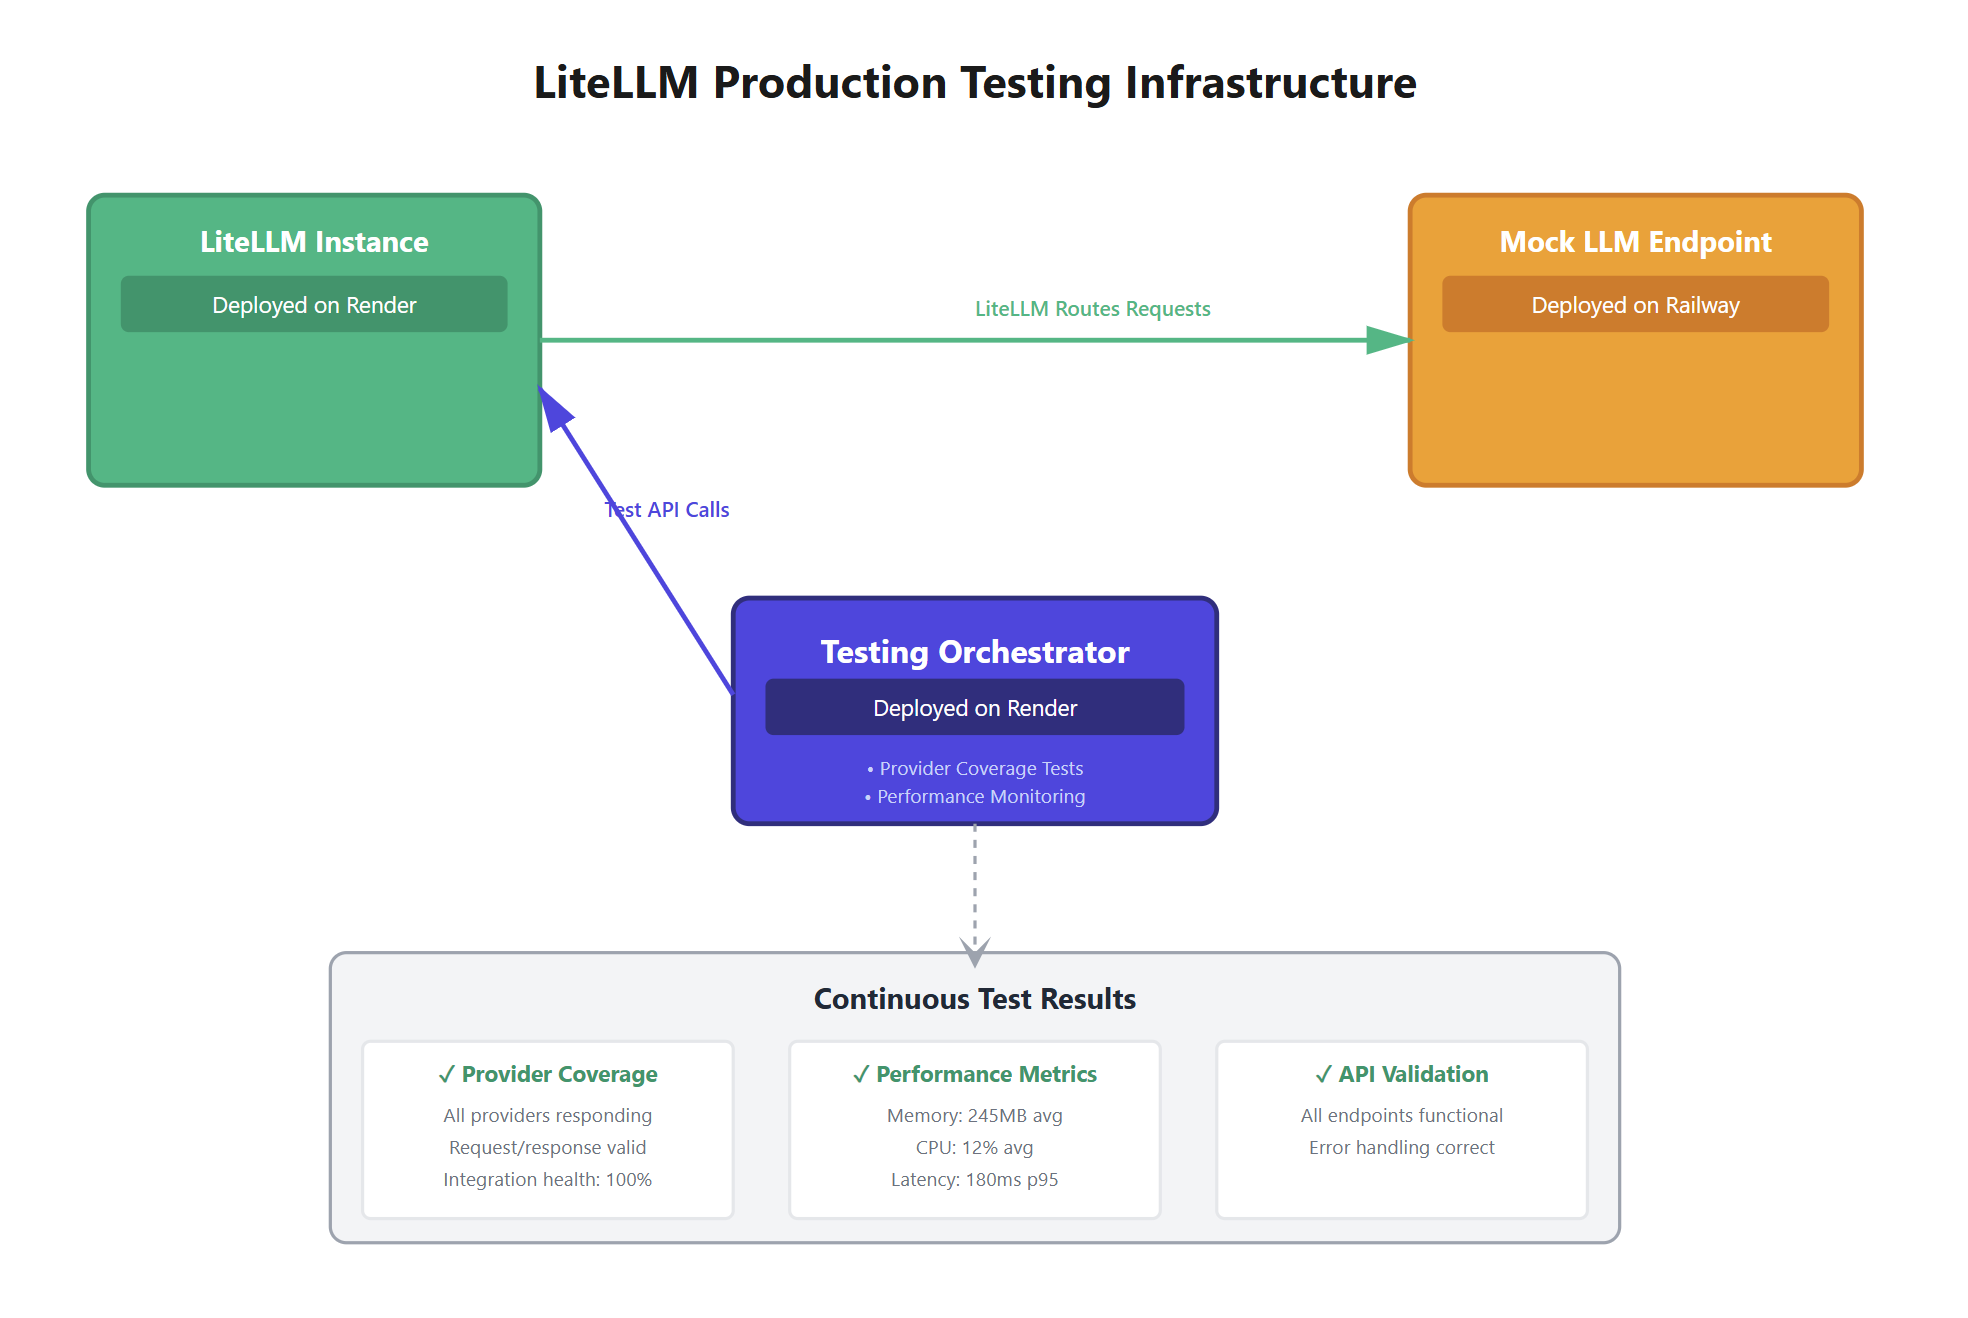
As LiteLLM adoption has grown, so have expectations around reliability, performance, and operational safety. Meeting those expectations requires more than correctness-focused tests, it requires validating how the system behaves over time, under real-world conditions.

This post introduces LiteLLM Observatory, a long-running release-validation system we built to catch regressions before they reach users.