Quickstart
Run LiteLLM and PostgreSQL locally, then use the Admin UI to add models, create keys, and send your first request.
Up and running in a minute
curl -fsSL https://raw.githubusercontent.com/BerriAI/litellm/main/litellm/scripts/quickstart.sh | sh1. Start LiteLLM
curl -sSLO https://github.com/BerriAI/litellm/raw/main/litellm/deploy/docker/docker-compose.quickstart.yml
printf 'LITELLM_MASTER_KEY=sk-%s\nLITELLM_SALT_KEY=sk-%s\n' "$(openssl rand -hex 32)" "$(openssl rand -hex 32)" > .env
docker compose -f docker-compose.quickstart.yml up -d
The compose file starts the full LiteLLM proxy on port 4000 and PostgreSQL. Pin a tested release tag or digest before production.
For Kubernetes, see the Helm guide.
Cloud deployment options
Railway and Render host the same gateway and Postgres for you. For AWS and GCP, use the Terraform deployment guide. Use your deployment's URL wherever this guide says http://localhost:4000.
On Render, set Blueprint Path to litellm/deploy/render/render.yaml after signing in, before you deploy.


The local setup generates both keys in .env. The compose file requires both keys. On a 1-click deploy, set them in the provider's environment.
LITELLM_MASTER_KEY authorizes every management API call and serves as the default Admin UI password. The generated sk- prefix is optional.
LITELLM_SALT_KEY encrypts the provider API keys you add in the UI. It has no in-place rotation, so keep the generated value: changing it later makes every stored credential unreadable until you re-enter it. See key rotations for how the two keys relate.
2. Log in to the Admin UI
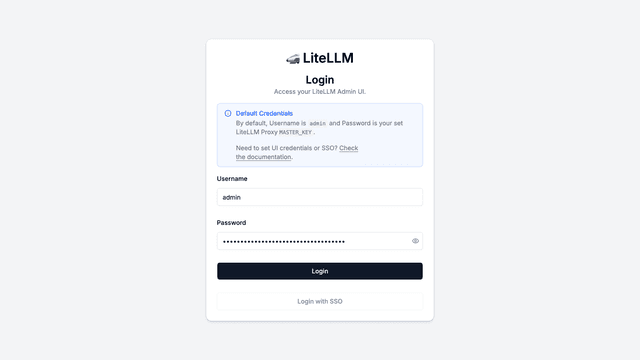
Open http://localhost:4000/ui. The username is admin and the password is the LITELLM_MASTER_KEY value in .env.
3. Add your first model
Go to Models + Endpoints, open the Add Model tab, pick your provider and models, and paste your provider API key.
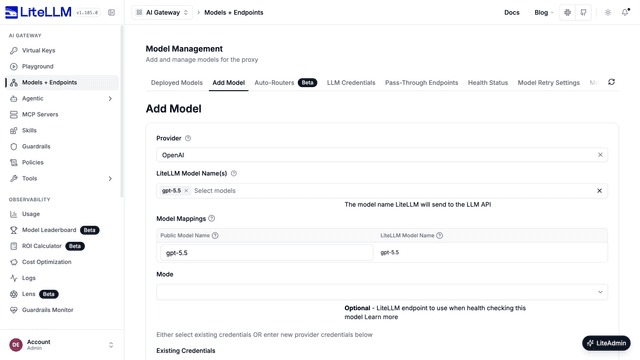
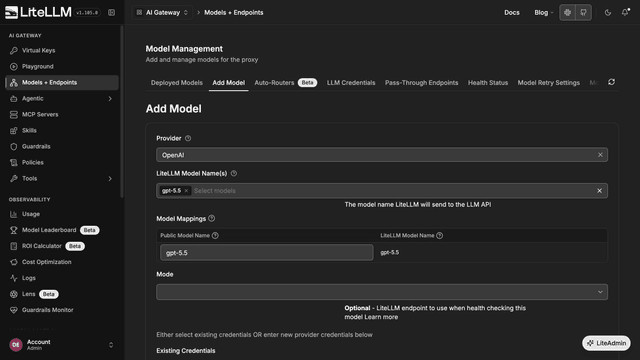
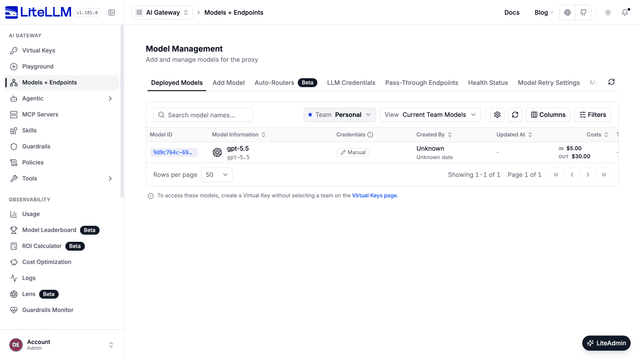
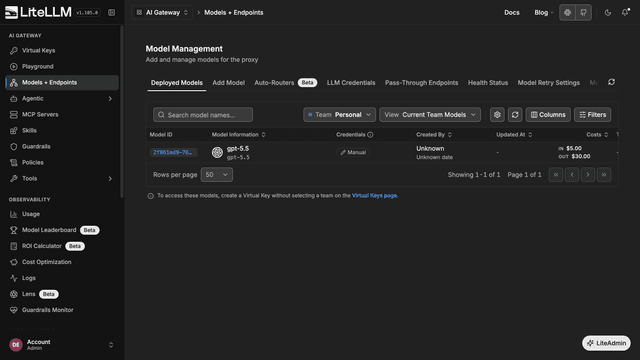
Click Test Connect to verify the key against the provider, then Add Model. It appears under Deployed Models with its pricing already mapped:
If you prefer to manage provider keys as environment variables, download the compose file, add them to the litellm service (for example OPENAI_API_KEY: ${OPENAI_API_KEY}), and enter os.environ/OPENAI_API_KEY in the API key field instead of the raw key.
4. Send a test message
Go to Playground, select your model, and send a message. The response includes latency and token counts:
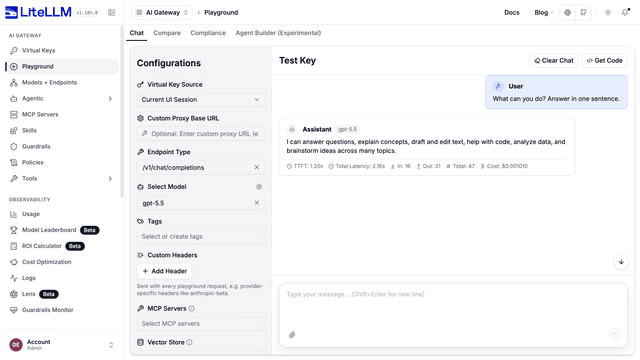
The Get Code button generates the equivalent API call for your language.
5. Create a virtual key
Virtual keys are what you hand to applications and teammates instead of raw provider keys. Each key can carry its own budget, rate limits, and model access, and all its spend is tracked automatically.
Go to Virtual Keys, click + Create New Key, give it a name, and click Create Key:
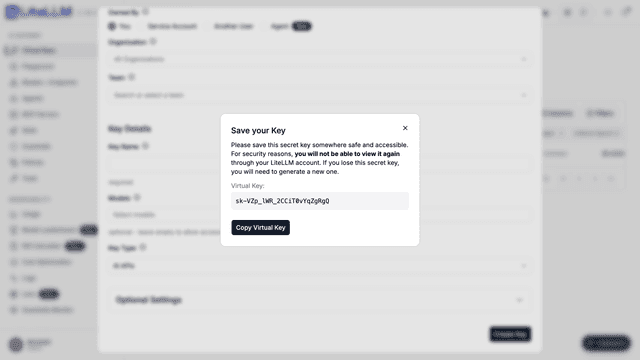
Copy the key now. It is shown only once.
6. Call the gateway from your app
The gateway is OpenAI-compatible, so any OpenAI SDK works by pointing it at http://localhost:4000 with your virtual key.
- curl
- OpenAI Python SDK
- OpenAI JS SDK
curl http://localhost:4000/v1/chat/completions \
  -H 'Authorization: Bearer sk-<your-virtual-key>' \
  -H 'Content-Type: application/json' \
  -d '{
    "model": "gpt-6.1-sol",
    "messages": [{"role": "user", "content": "Say hello in five words."}]
  }'
Expected response:
{
  "id": "chatcmpl-DzGKiNRbQ4fe9Mgt8HSHFQ6ApfRJi",
  "model": "gpt-6.1-sol",
  "object": "chat.completion",
  "choices": [
    {
      "finish_reason": "stop",
      "index": 0,
      "message": {
        "content": "Hello, nice to meet you.",
        "role": "assistant"
      }
    }
  ],
  "usage": {
    "completion_tokens": 70,
    "prompt_tokens": 12,
    "total_tokens": 82
  }
}
from openai import OpenAI

client = OpenAI(
    base_url="http://localhost:4000",
    api_key="sk-<your-virtual-key>",
)

response = client.chat.completions.create(
    model="gpt-6.1-sol",
    messages=[{"role": "user", "content": "Say hello in five words."}],
)
print(response.choices[0].message.content)
import OpenAI from "openai";

const client = new OpenAI({
  baseURL: "http://localhost:4000",
  apiKey: "sk-<your-virtual-key>",
});

const response = await client.chat.completions.create({
  model: "gpt-6.1-sol",
  messages: [{ role: "user", content: "Say hello in five words." }],
});
console.log(response.choices[0].message.content);
The whole flow, end to end
Running without a database
For API access without database-backed model management, virtual keys, or spend tracking, run the same image with a config file:
# litellm_config.yaml
model_list:
  - model_name: gpt-6.1-sol
    litellm_params:
      model: openai/gpt-6.1-sol
      api_key: os.environ/OPENAI_API_KEY
export OPENAI_API_KEY="<your-openai-key>"
export LITELLM_MASTER_KEY="sk-<paste-a-long-random-key>"

docker run \
  -v "$PWD/litellm_config.yaml:/app/config.yaml:ro" \
  -e OPENAI_API_KEY \
  -e LITELLM_MASTER_KEY \
  -p 127.0.0.1:4000:4000 \
  docker.litellm.ai/berriai/litellm:latest \
  --config /app/config.yaml
Requests authenticate with the master key. See the full config reference for everything the file supports.
litellm_settings.max_budget requires a database to load spend and enforce the global budget. Without one, max_budget: 100 keeps serving requests past $100 with no request error or budget alert. The proxy logs a one-time warning at startup.
Virtual keys also require a database. Requests that carry one fail with No connected db.. The master key has no budget of its own.
To enforce LiteLLM budgets, run with a database. Otherwise, configure spending limits at your provider.
Next steps
Use the deployment guides for Helm and Terraform, and the production checklist for hardening and tuning. The repository's docker-compose.yml includes database, Redis, and Prometheus options.

