Published:
Yassin KortamSenior SWE @ LiteLLM
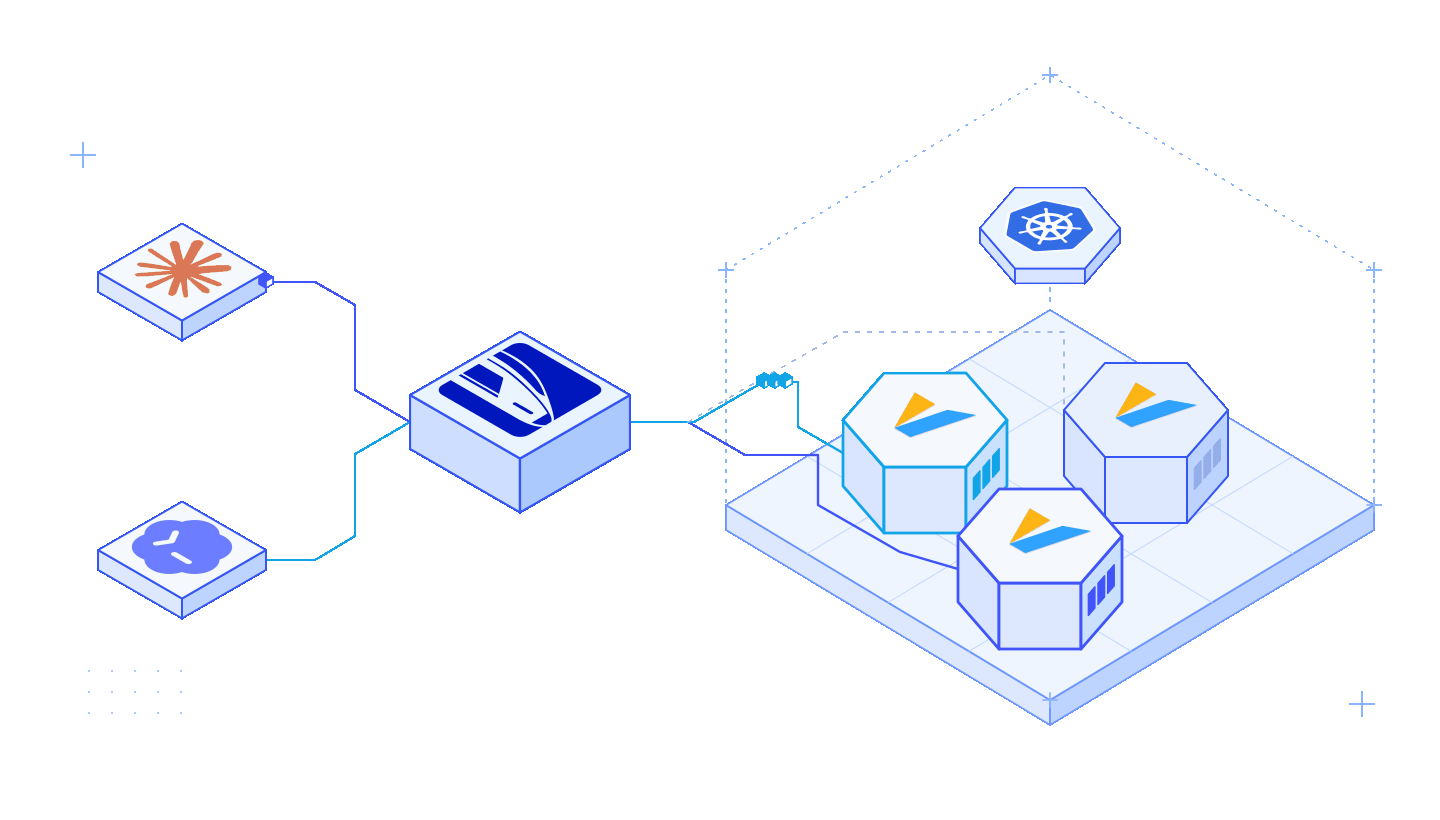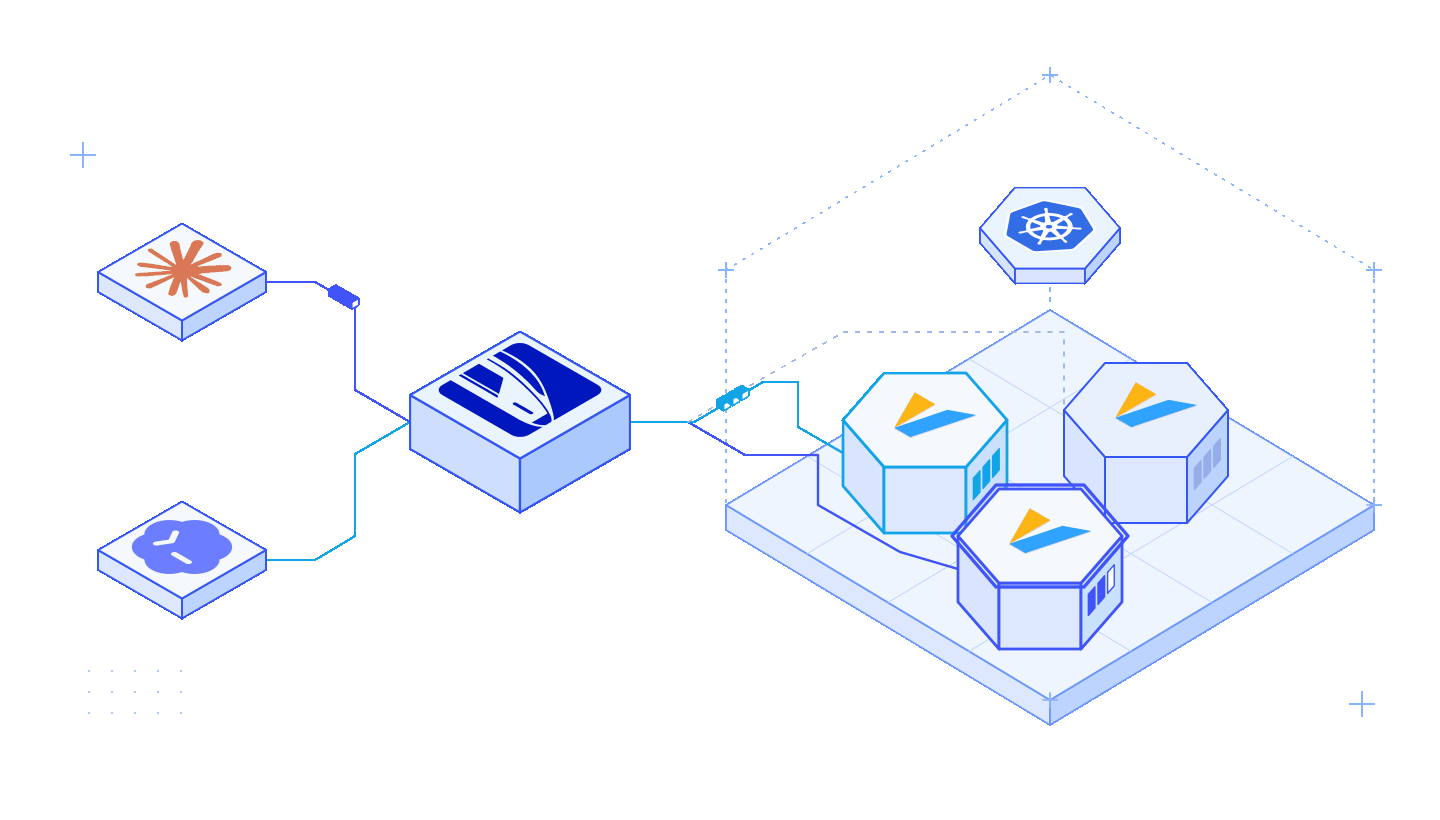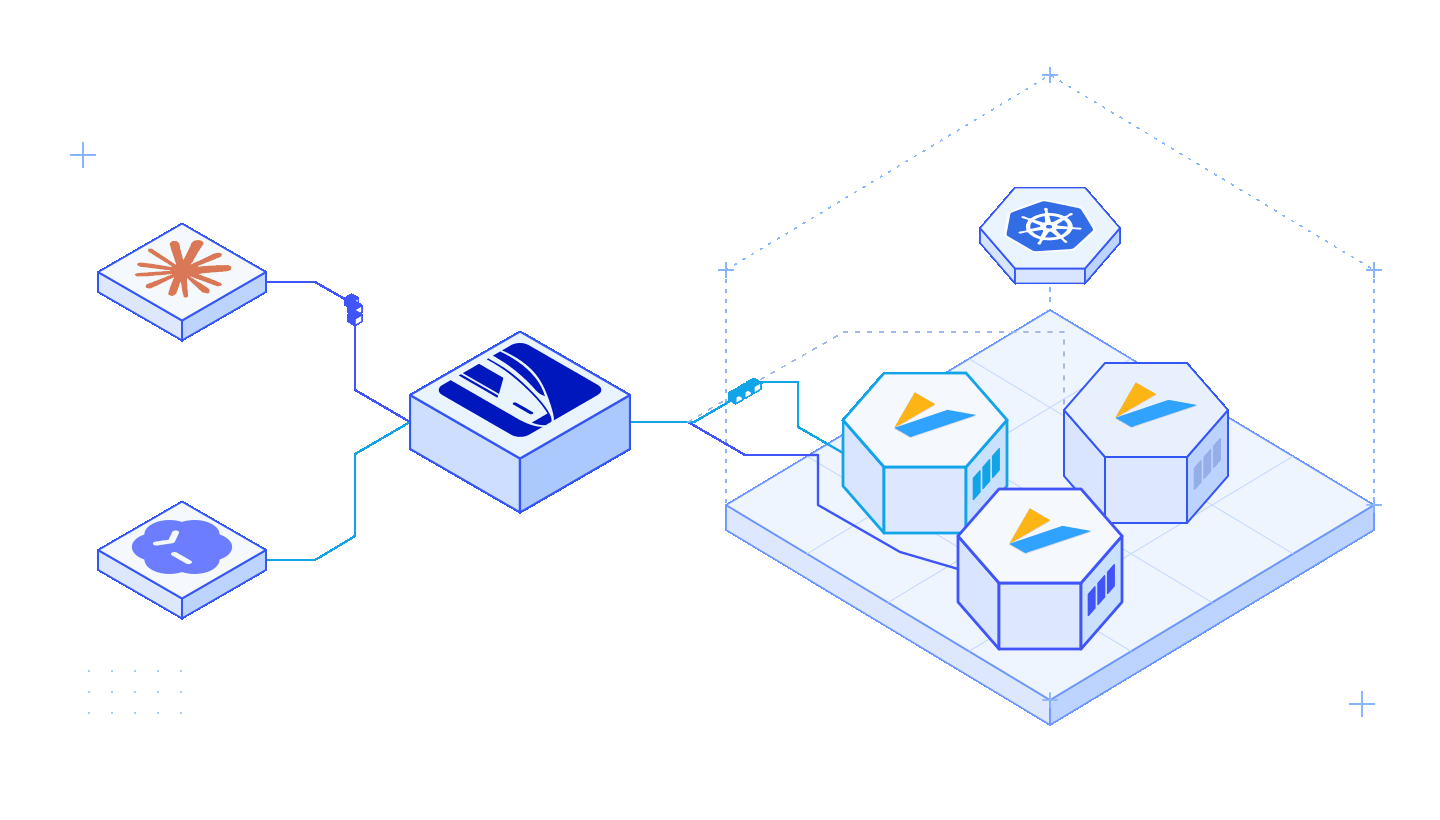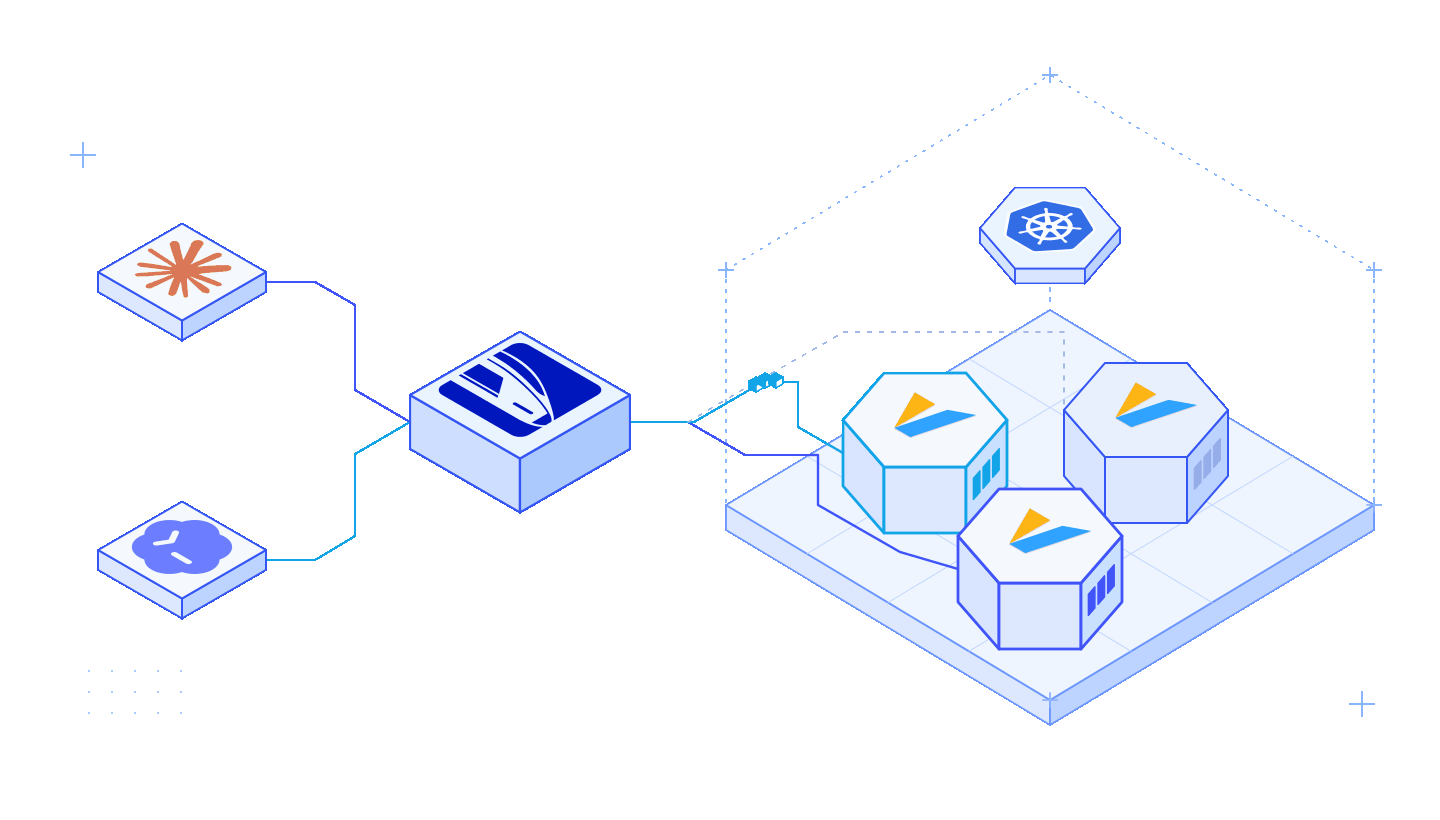
LiteLLM now supports cache-aware routing for self-hosted inference on Kubernetes. Within a deployment, requests from the same session go to the same GPU pod. This lets vLLM reuse cached prompt prefixes across turns.
Agent requests often share system instructions, tool definitions, and conversation history. When requests reach different pods, each pod may process the same prefix again. Session affinity helps reuse that work.
Keep a session on one GPU pod
LiteLLM discovers pod IPs through a Kubernetes headless Service. It uses the session ID to choose a pod using rendezvous hashing, then sends the request directly to that pod.