Decision models on LiteLLM: /v1/decisions and /v1/systemone
Decision models return probabilities instead of text, which makes routing, triage and guardrail checks cheap and deterministic. LiteLLM serves nine providers of them behind one request shape.
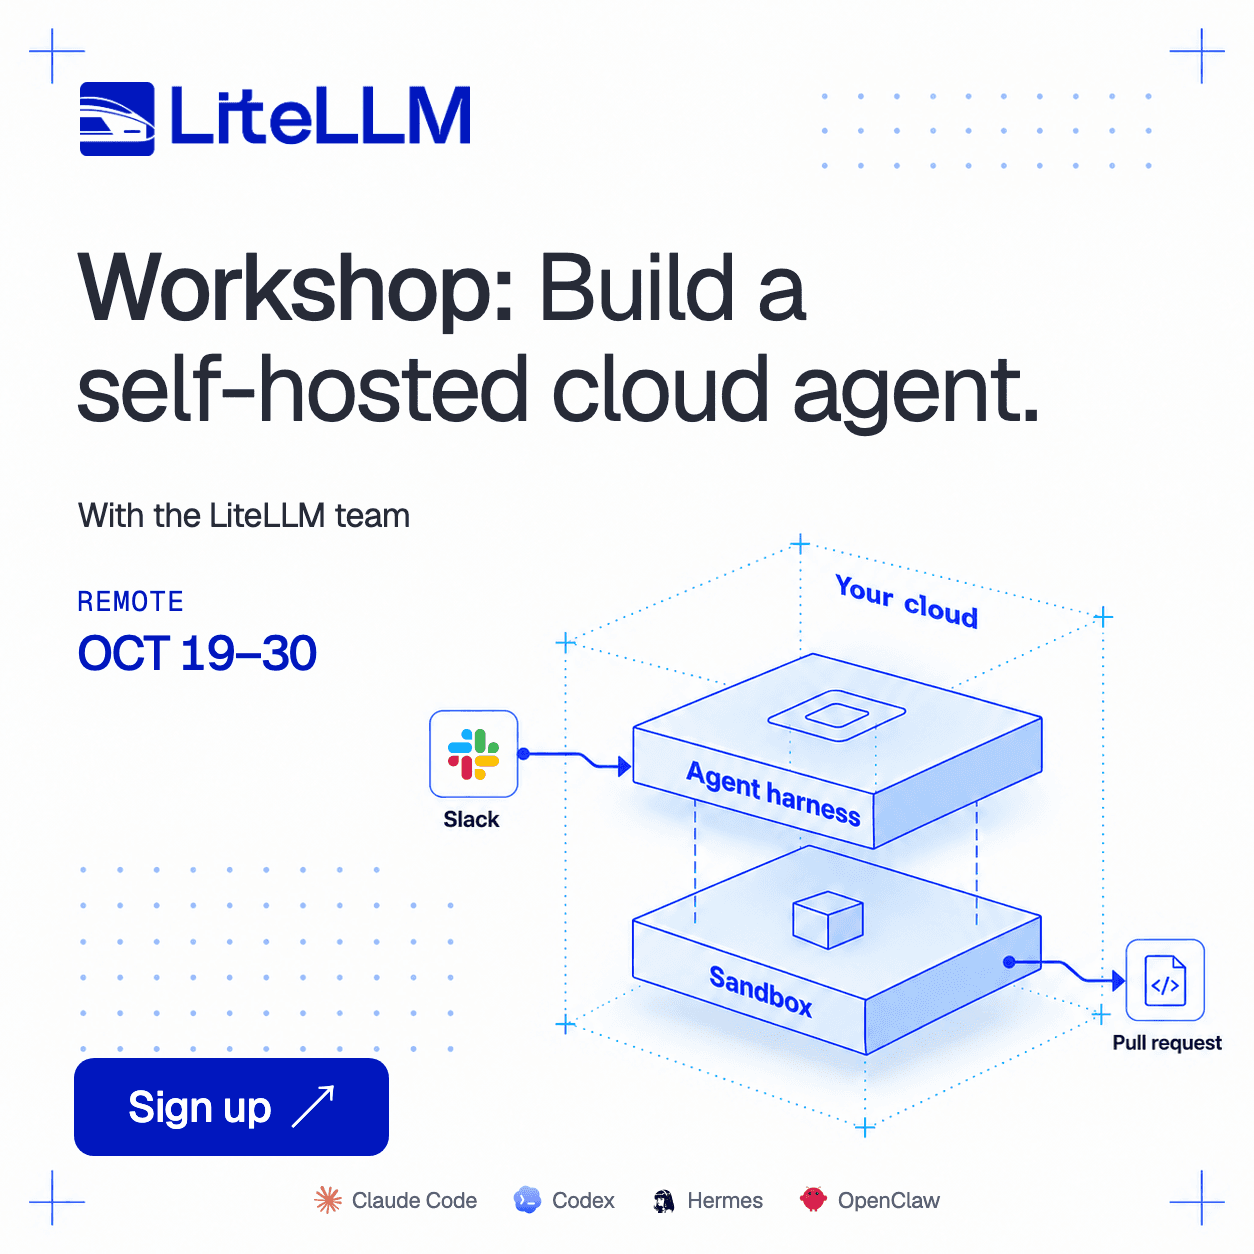
Workshop: Build a self-hosted cloud agent.
Build a self-hosted cloud agent with the LiteLLM team. A two-week remote workshop, October 19–30, to build a working v0 and deploy an internal beta on your infrastructure.
Gemini 4 Argon API Pricing and Day 0 Support on LiteLLM
Gemini 4 Argon costs $2.00 per 1M input tokens and $10.00 per 1M output tokens until Nov 30. LiteLLM supports it on day 0 on AI Studio and Google Cloud.
October Townhall: Product + Roadmap Updates
Join the LiteLLM October townhall on Thursday, 22 October at 7:30 AM PT to learn about LiteLLM's product updates and roadmap.
Introducing Microsoft 365 Copilot in LiteLLM
Use Microsoft 365 Copilot from your applications through LiteLLM, with access to your Microsoft 365 work data.
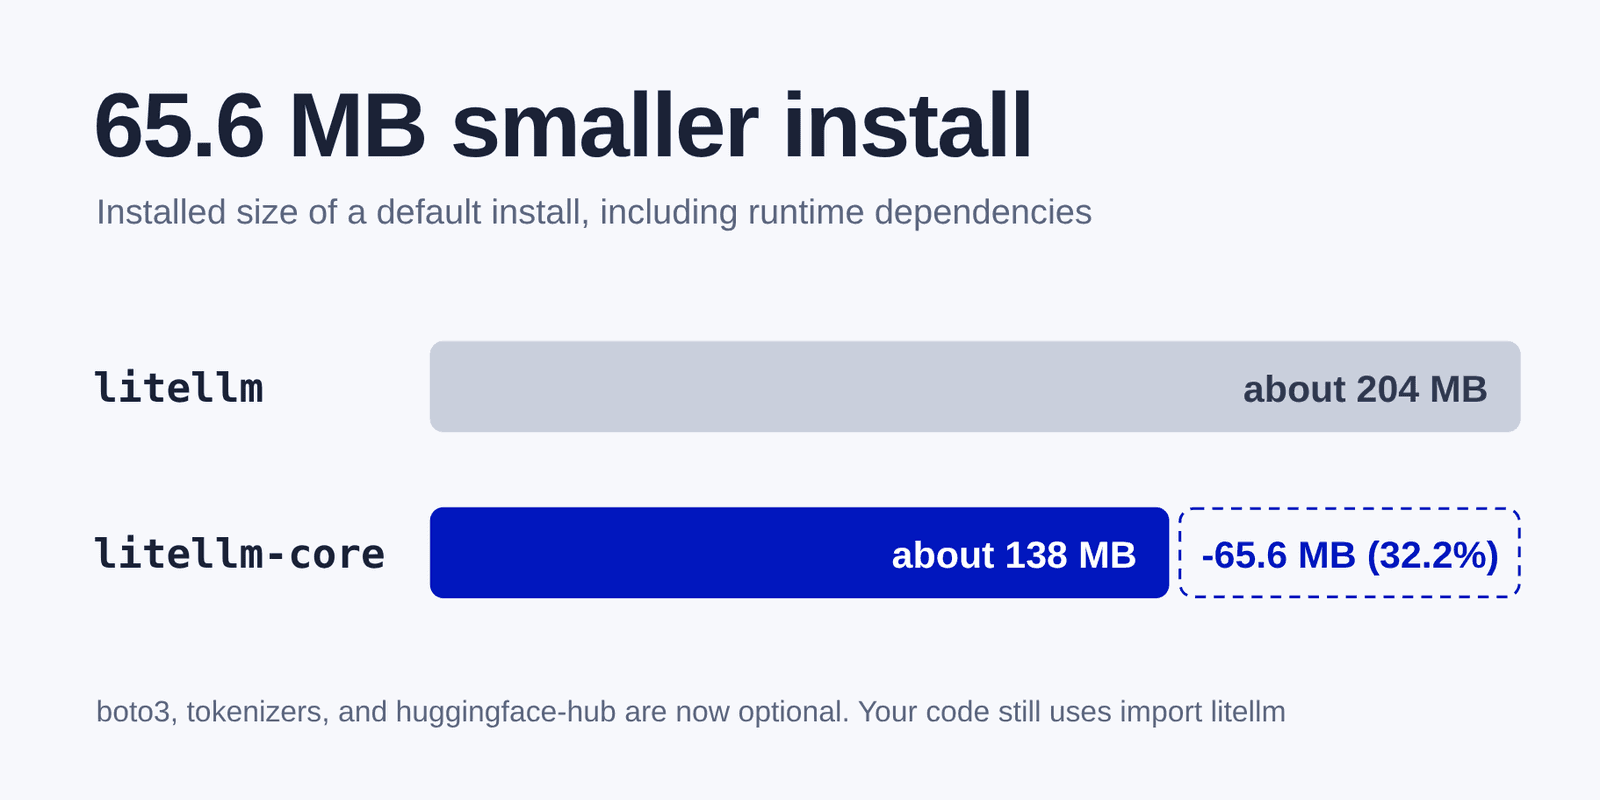
Introducing litellm-core: the first step toward a leaner SDK
Ongoing work to reduce LiteLLM's dependencies and installation footprint, improve runtime loading, and make imports faster
Claude Haiku 5.5 API Pricing and Day 0 Support on LiteLLM
Claude Haiku 5.5 costs $0.10 per 1M input tokens and $0.50 per 1M output tokens. LiteLLM supports it on day 0 on Anthropic, AWS, Google Cloud and Azure.
Open Sourcing Moyai: Self-Hosted Cloud Coding Agent
Run cloud coding agents on your own infrastructure with Moyai. Choose your agent and models through LiteLLM, track costs, and follow the setup guide.
Day 0 Support: Nano Banana 2.1
Day 0 support for Gemini Nano Banana 2.1 on LiteLLM, on Google AI Studio and Gemini Enterprise Agent Platform, with image output at half Nano Banana 2's price.
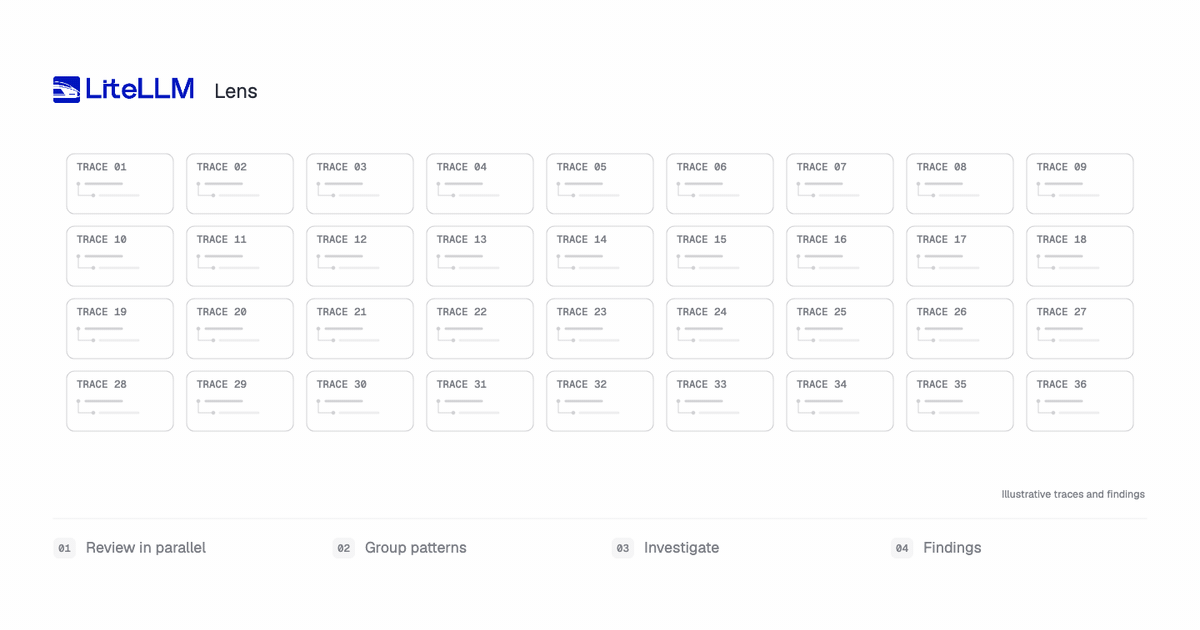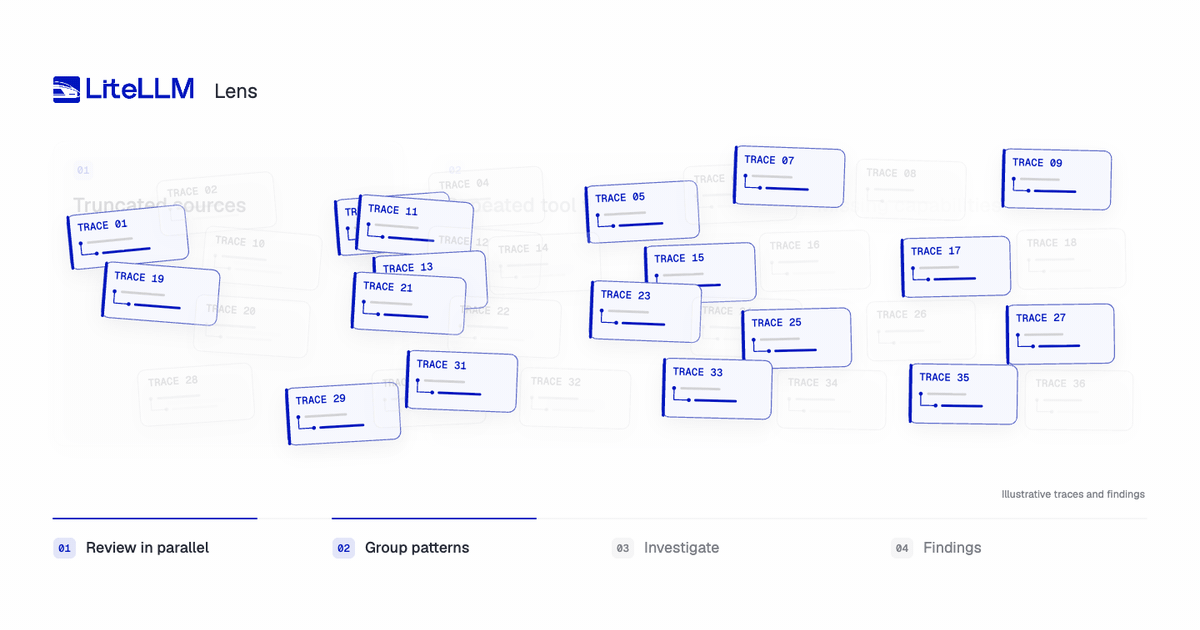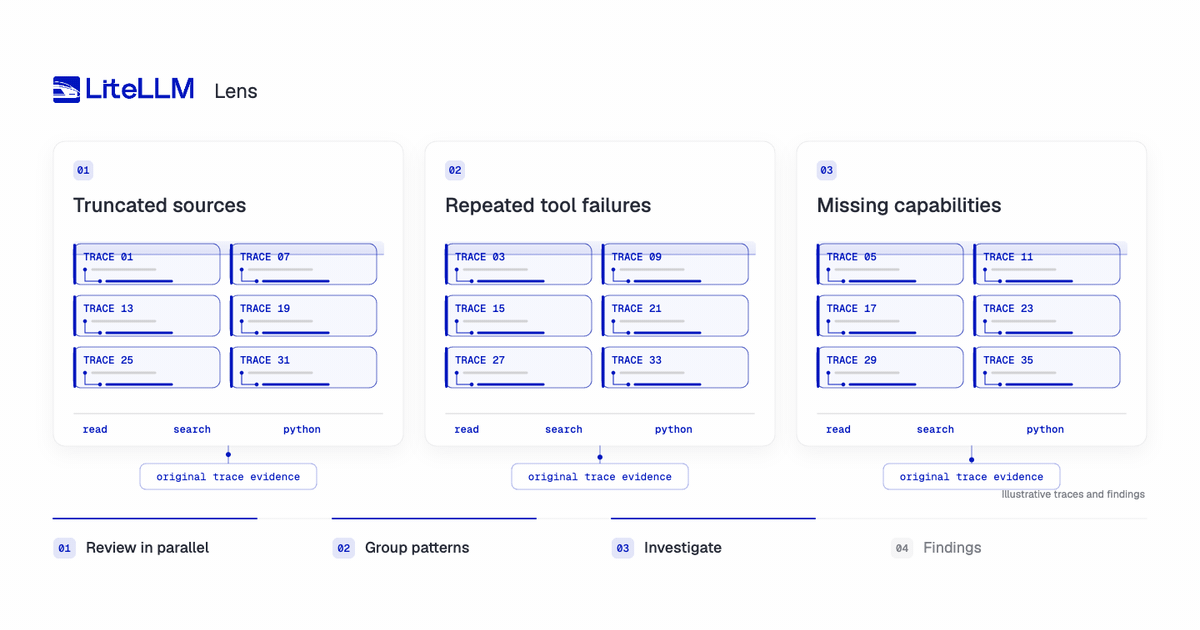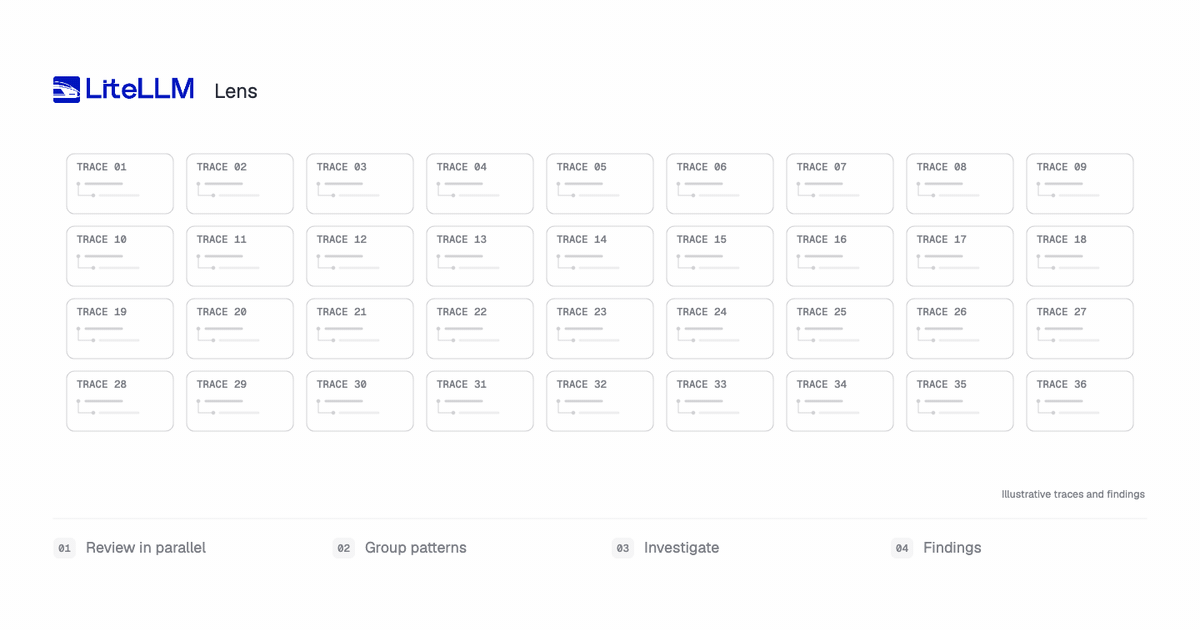
How LiteLLM Lens finds repeated failures across 1,000s of agent traces
Inside Lens: parallel trace review, Python tools for large traces, and investigations that connect repeated failures to source evidence.
How we cut time to first byte by 94% for long prompts
A 440k-token benchmark went from 553 ms to 35 ms median time to first byte. We removed unnecessary prompt-cache routing work before the model call.
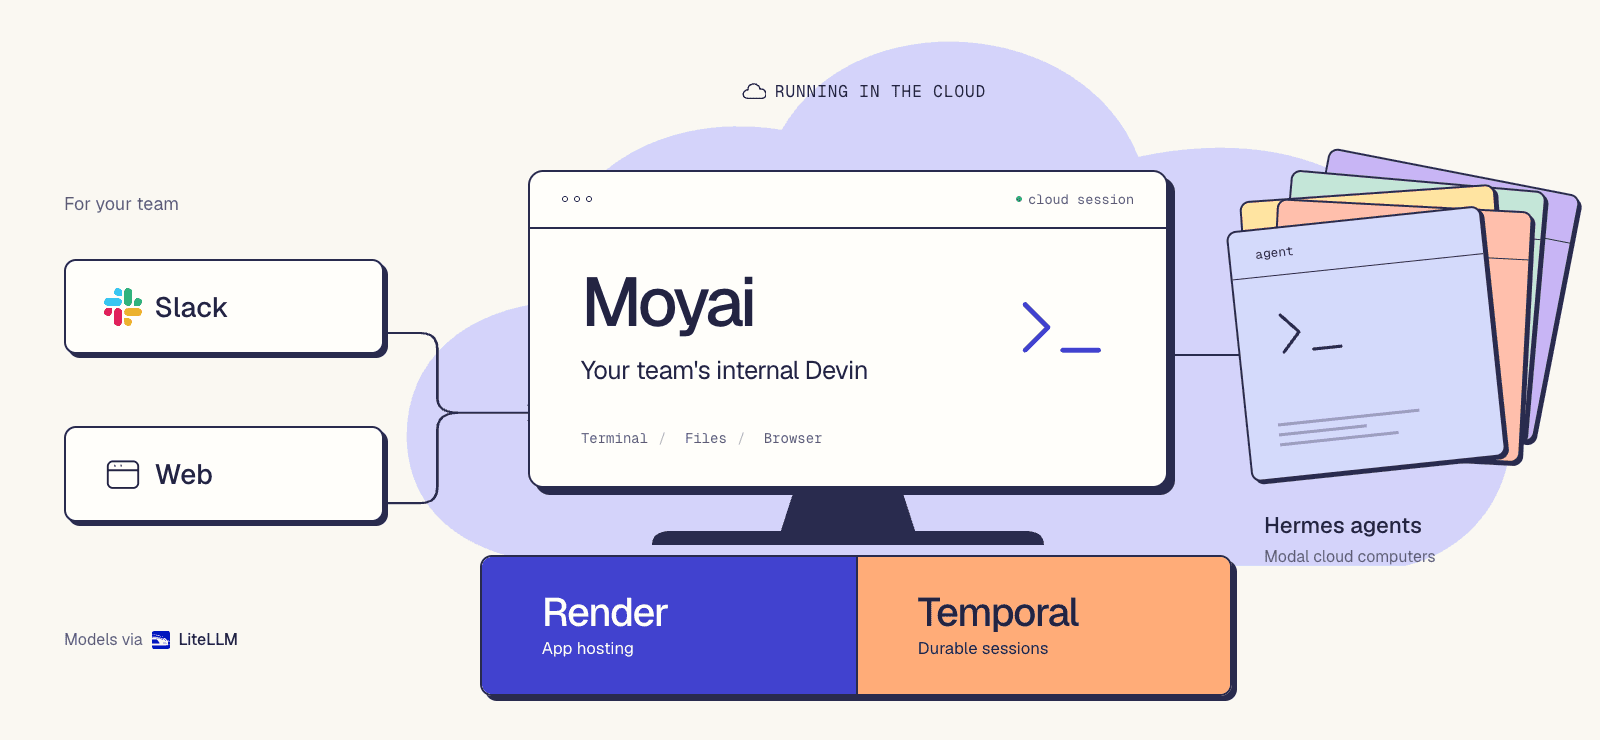
How we built our own internal Devin in 2 days
How we built Moyai Devin with Render, Modal, Hermes, Temporal, and LiteLLM: durable sessions, parallel agents, Slack, and shared organization connections.
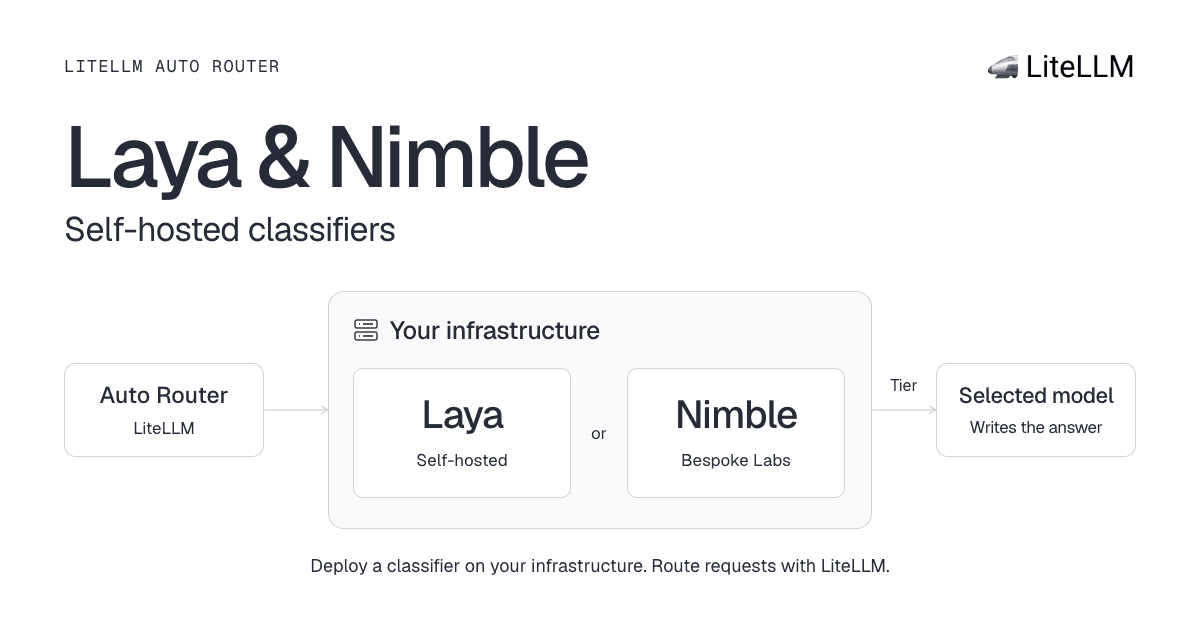
Adding Self-hosted Auto Router Classifiers: Laya & Nimble
Use Laya or Bespoke Nimble to classify Auto Router requests on your own infrastructure. Control where classification runs, which model you serve, and how you provision it.
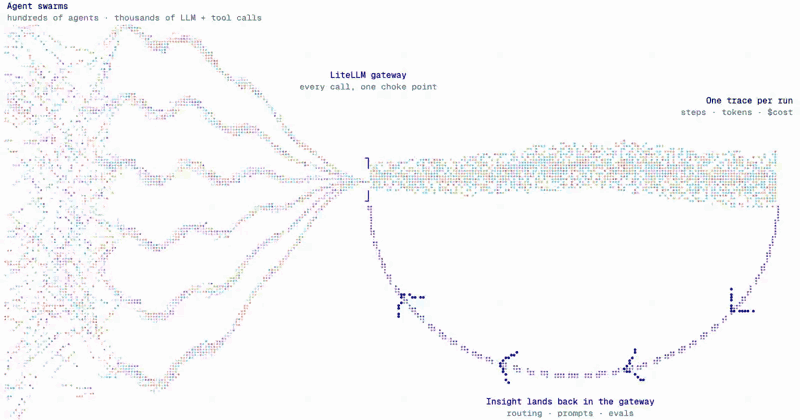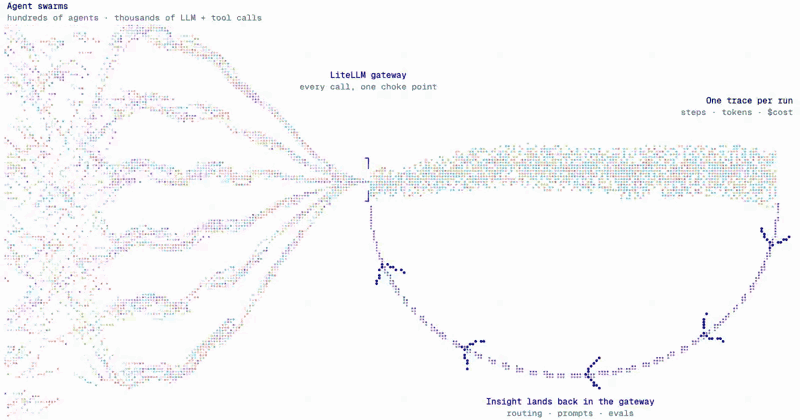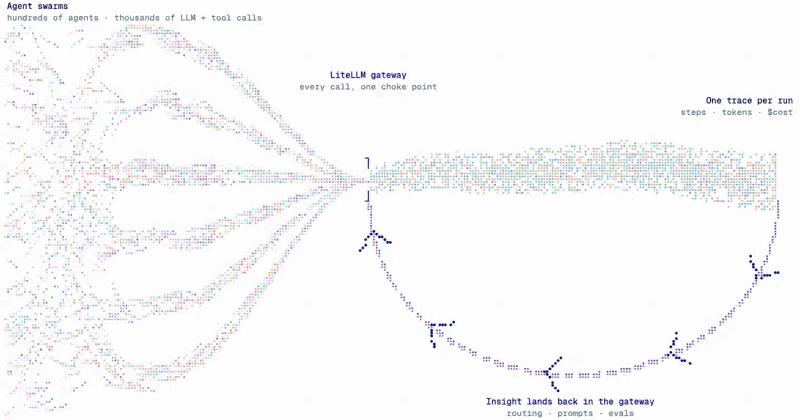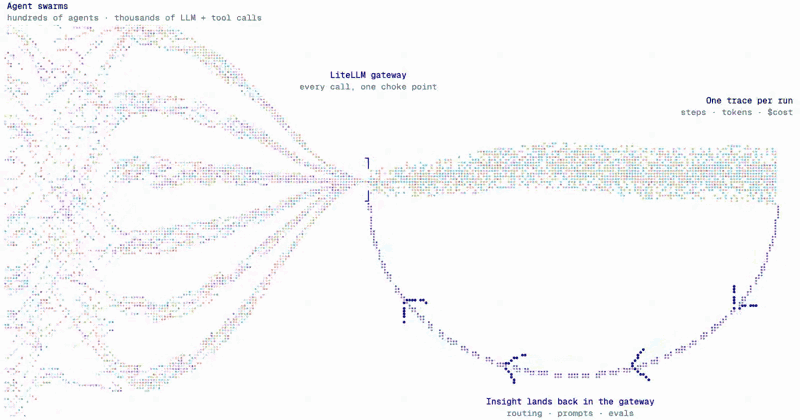
Launching LiteLLM Lens
LiteLLM Lens turns the traces flowing through your gateway into findings your agents can act on. Built for agent swarms generating 200K+ traces.
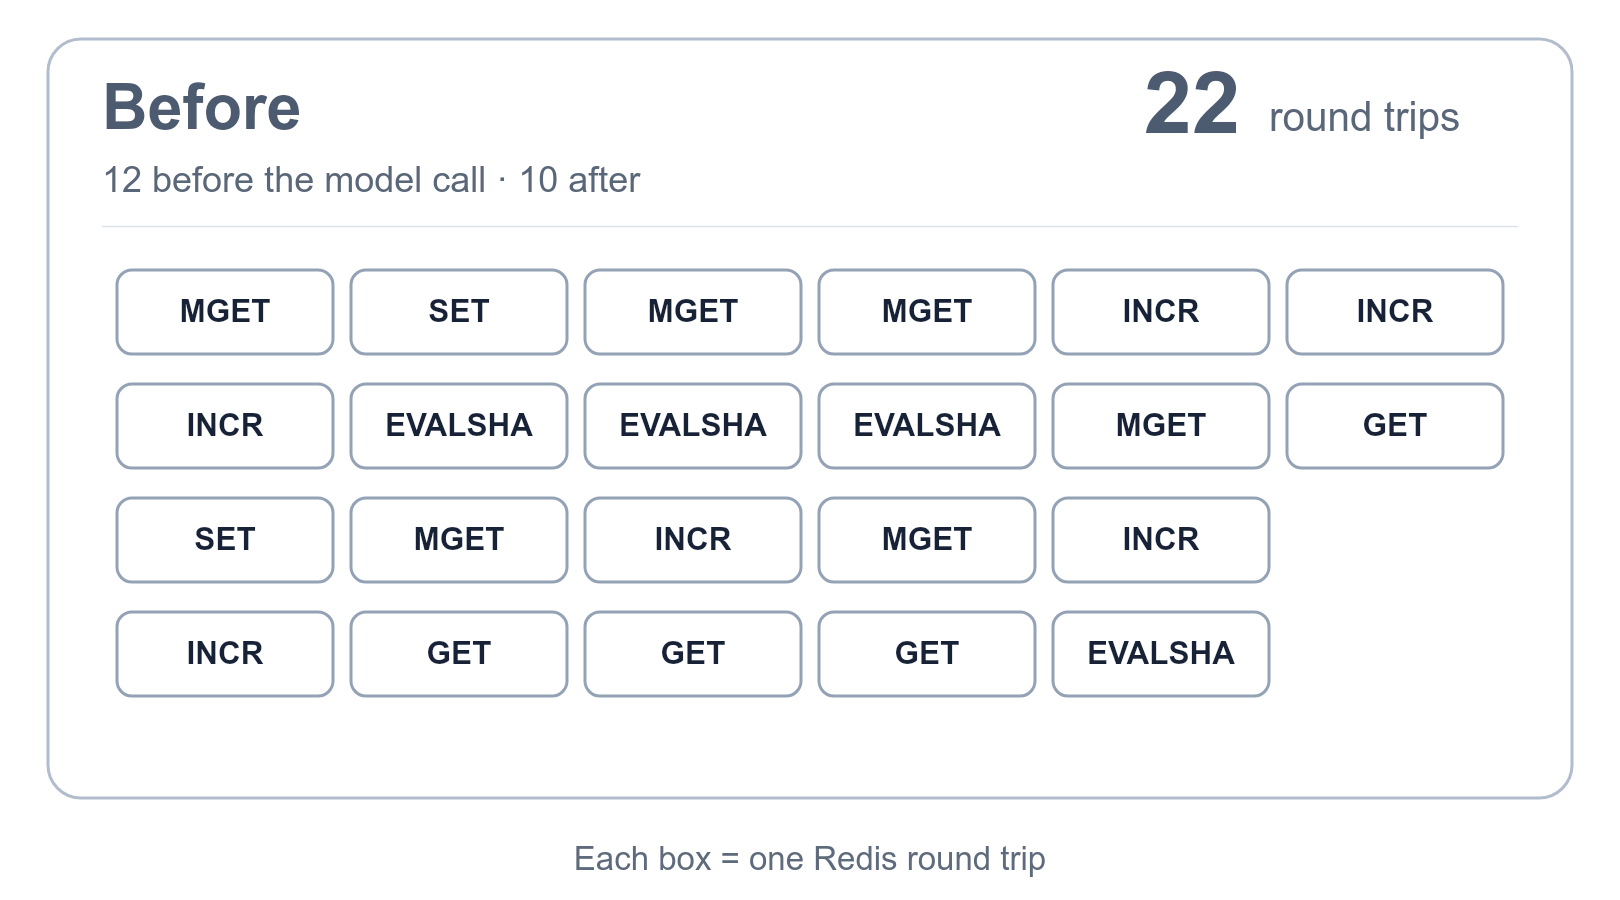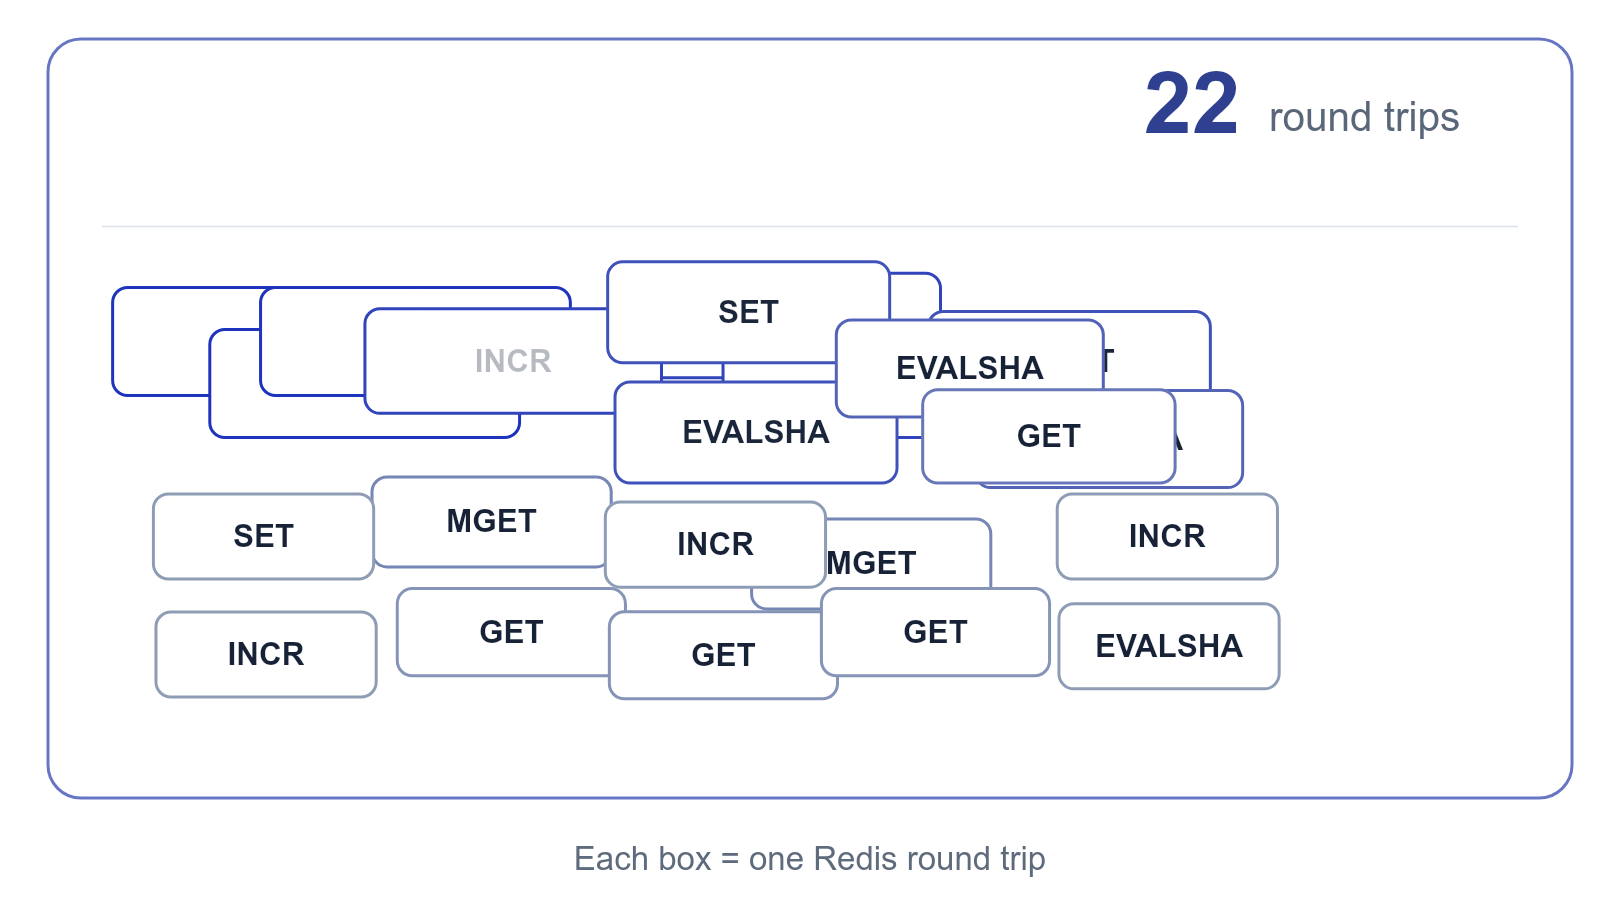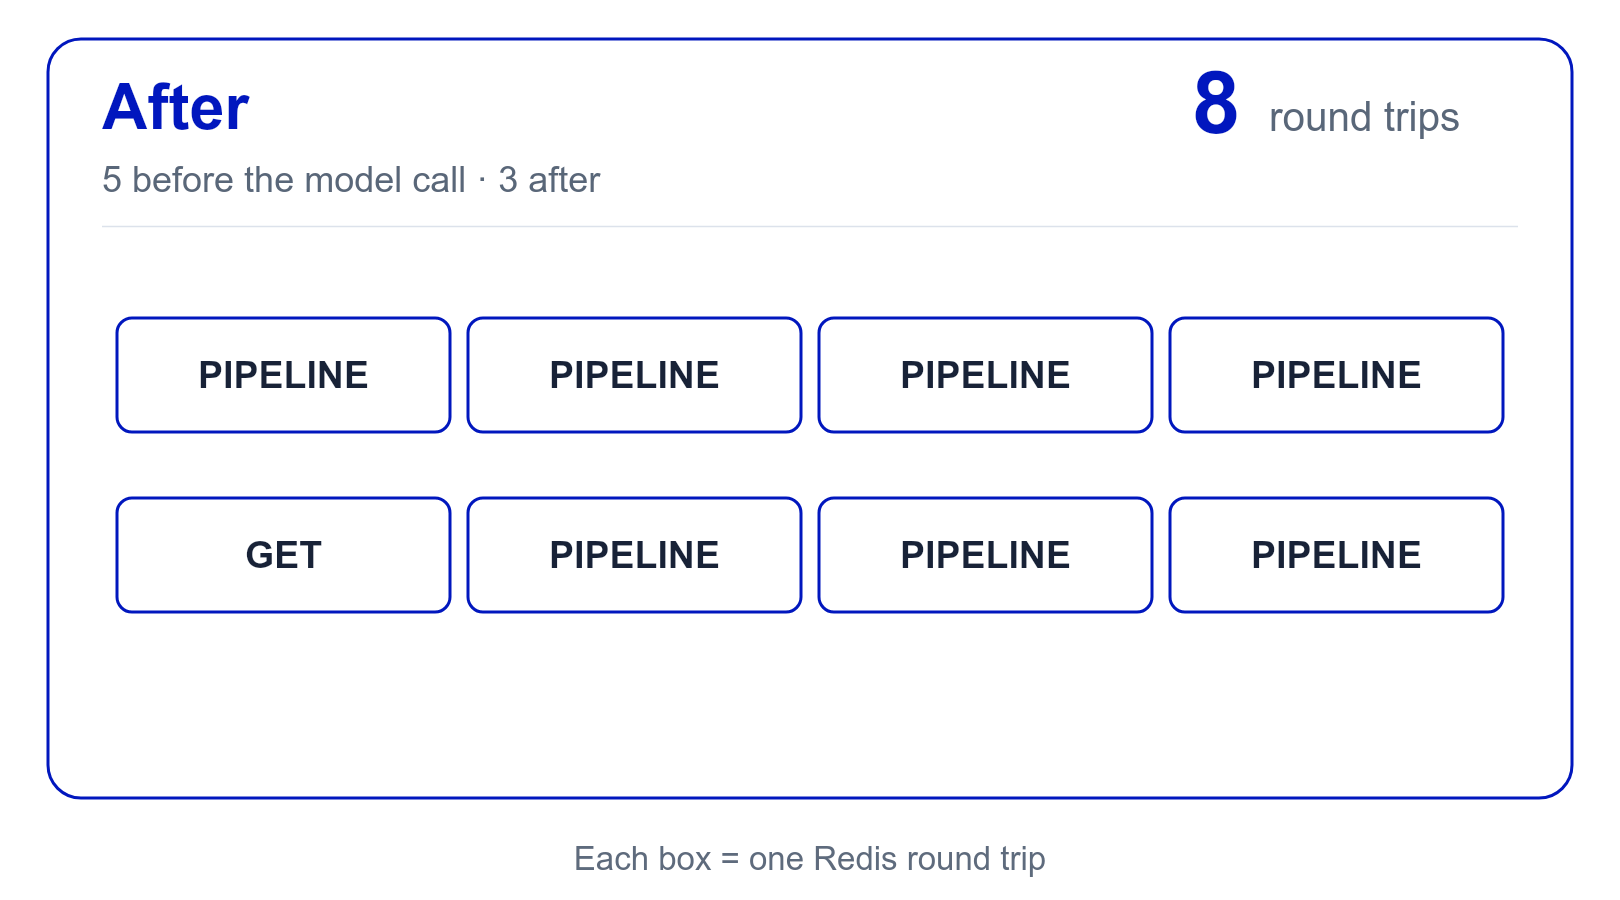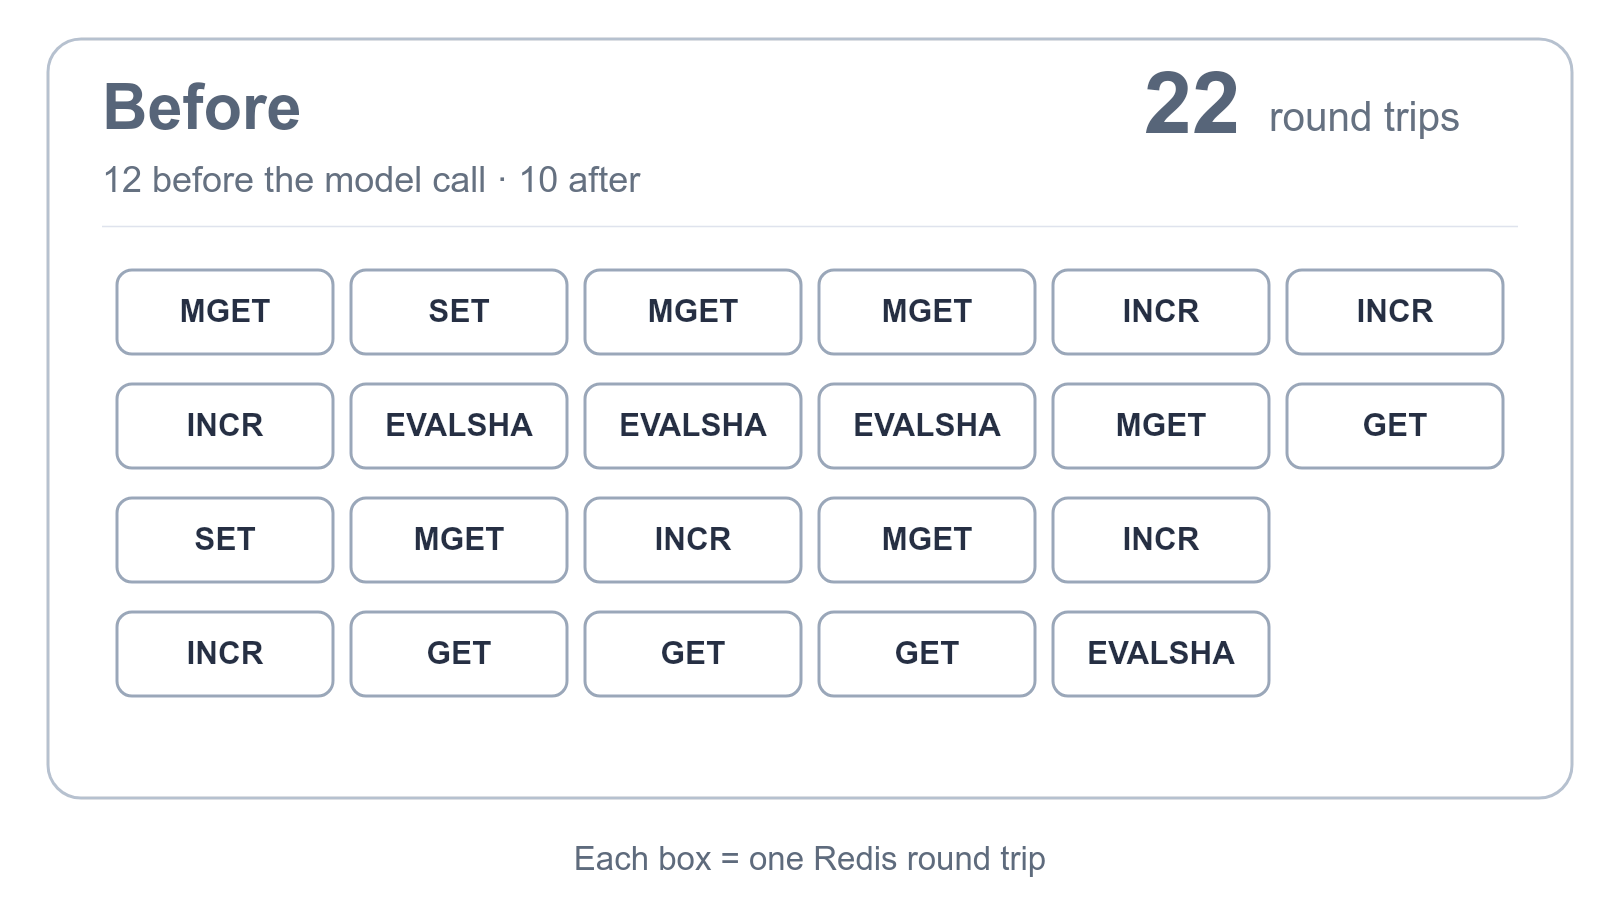
How we cut LiteLLM's Redis round trips per request by 64%
A governed request to the LiteLLM AI Gateway waited on Redis 22 times. It now waits 8 times: one pipeline per Redis backend before the model call, one after.
How we made the LiteLLM Usage page 120x faster
From six minutes to 3.2 seconds: how moving aggregation into Postgres made LiteLLM's Usage page roughly 120x faster in our benchmark.
Day 0 Support: GPT-6.1 Sol
Day 0 support for GPT-6.1 Sol on LiteLLM, with cached input at half GPT-6 Sol's price.
Learn the LiteLLM gateway with a guided course
Follow a request through the LiteLLM gateway, Router, and SDK. A guided course for teams deploying the gateway and contributors making code changes.
Day 0 Support: Claude Sonnet 5.5
Day 0 support for Claude Sonnet 5.5 on the LiteLLM AI Gateway. Use it across Anthropic, Bedrock, Gemini Enterprise Agent Platform, and Azure.
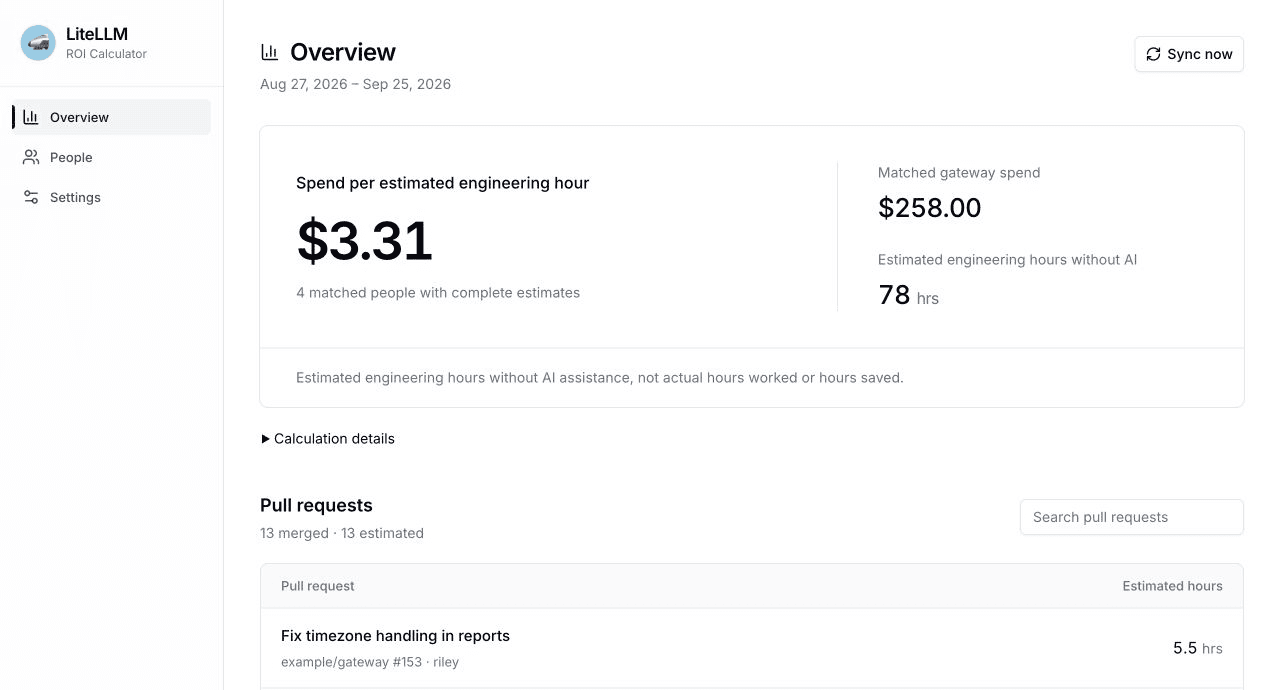
Introducing the LiteLLM ROI Calculator
Compare each engineer's LiteLLM gateway spend with the estimated effort of their merged pull requests. Open source and self-hosted.
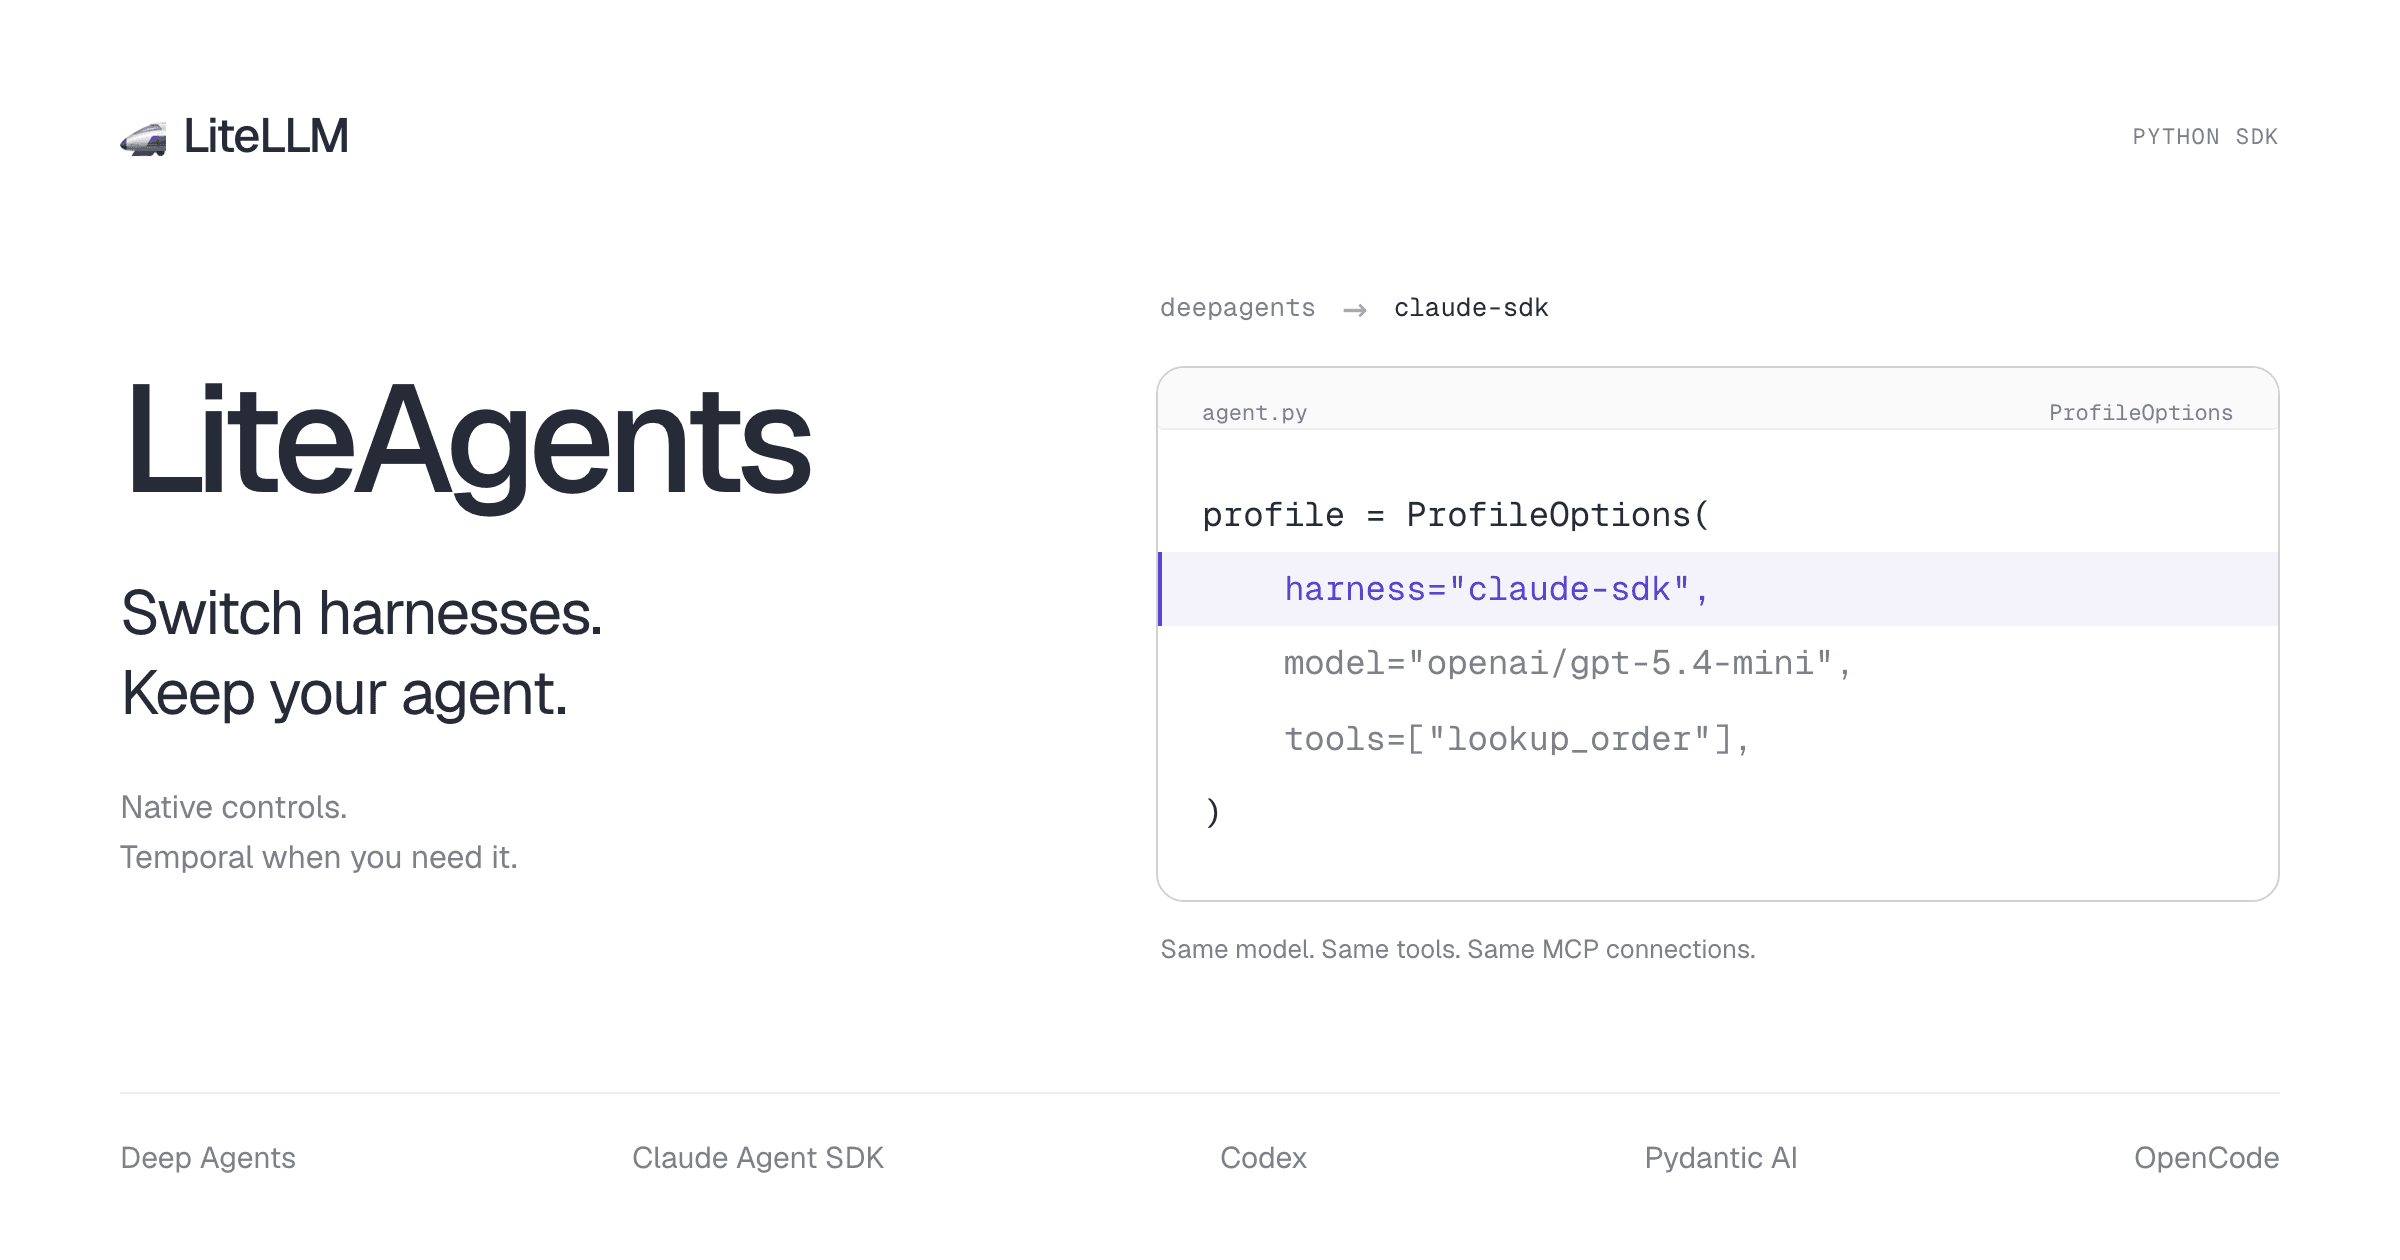
Introducing LiteAgents
Switch agent harnesses without rewriting your agent. Keep your tools and model configuration, use native harness controls, and add Temporal when you need durable runs.
September Townhall Updates: 583 Bug Fixes, OCR on Rust, and 83.5% Coverage
A recap of the September LiteLLM town hall: security and stability updates, OCR running on Rust by default, test coverage past the 80% target, and new Fusion and liteagents launches.
Day 0 support: Gemini 3.8 Flash TTS and Flash-Lite TTS
Day 0 support for Gemini 3.8 Flash TTS and Flash-Lite TTS on LiteLLM's /v1/audio/speech, with launch pricing tracked through 2026.
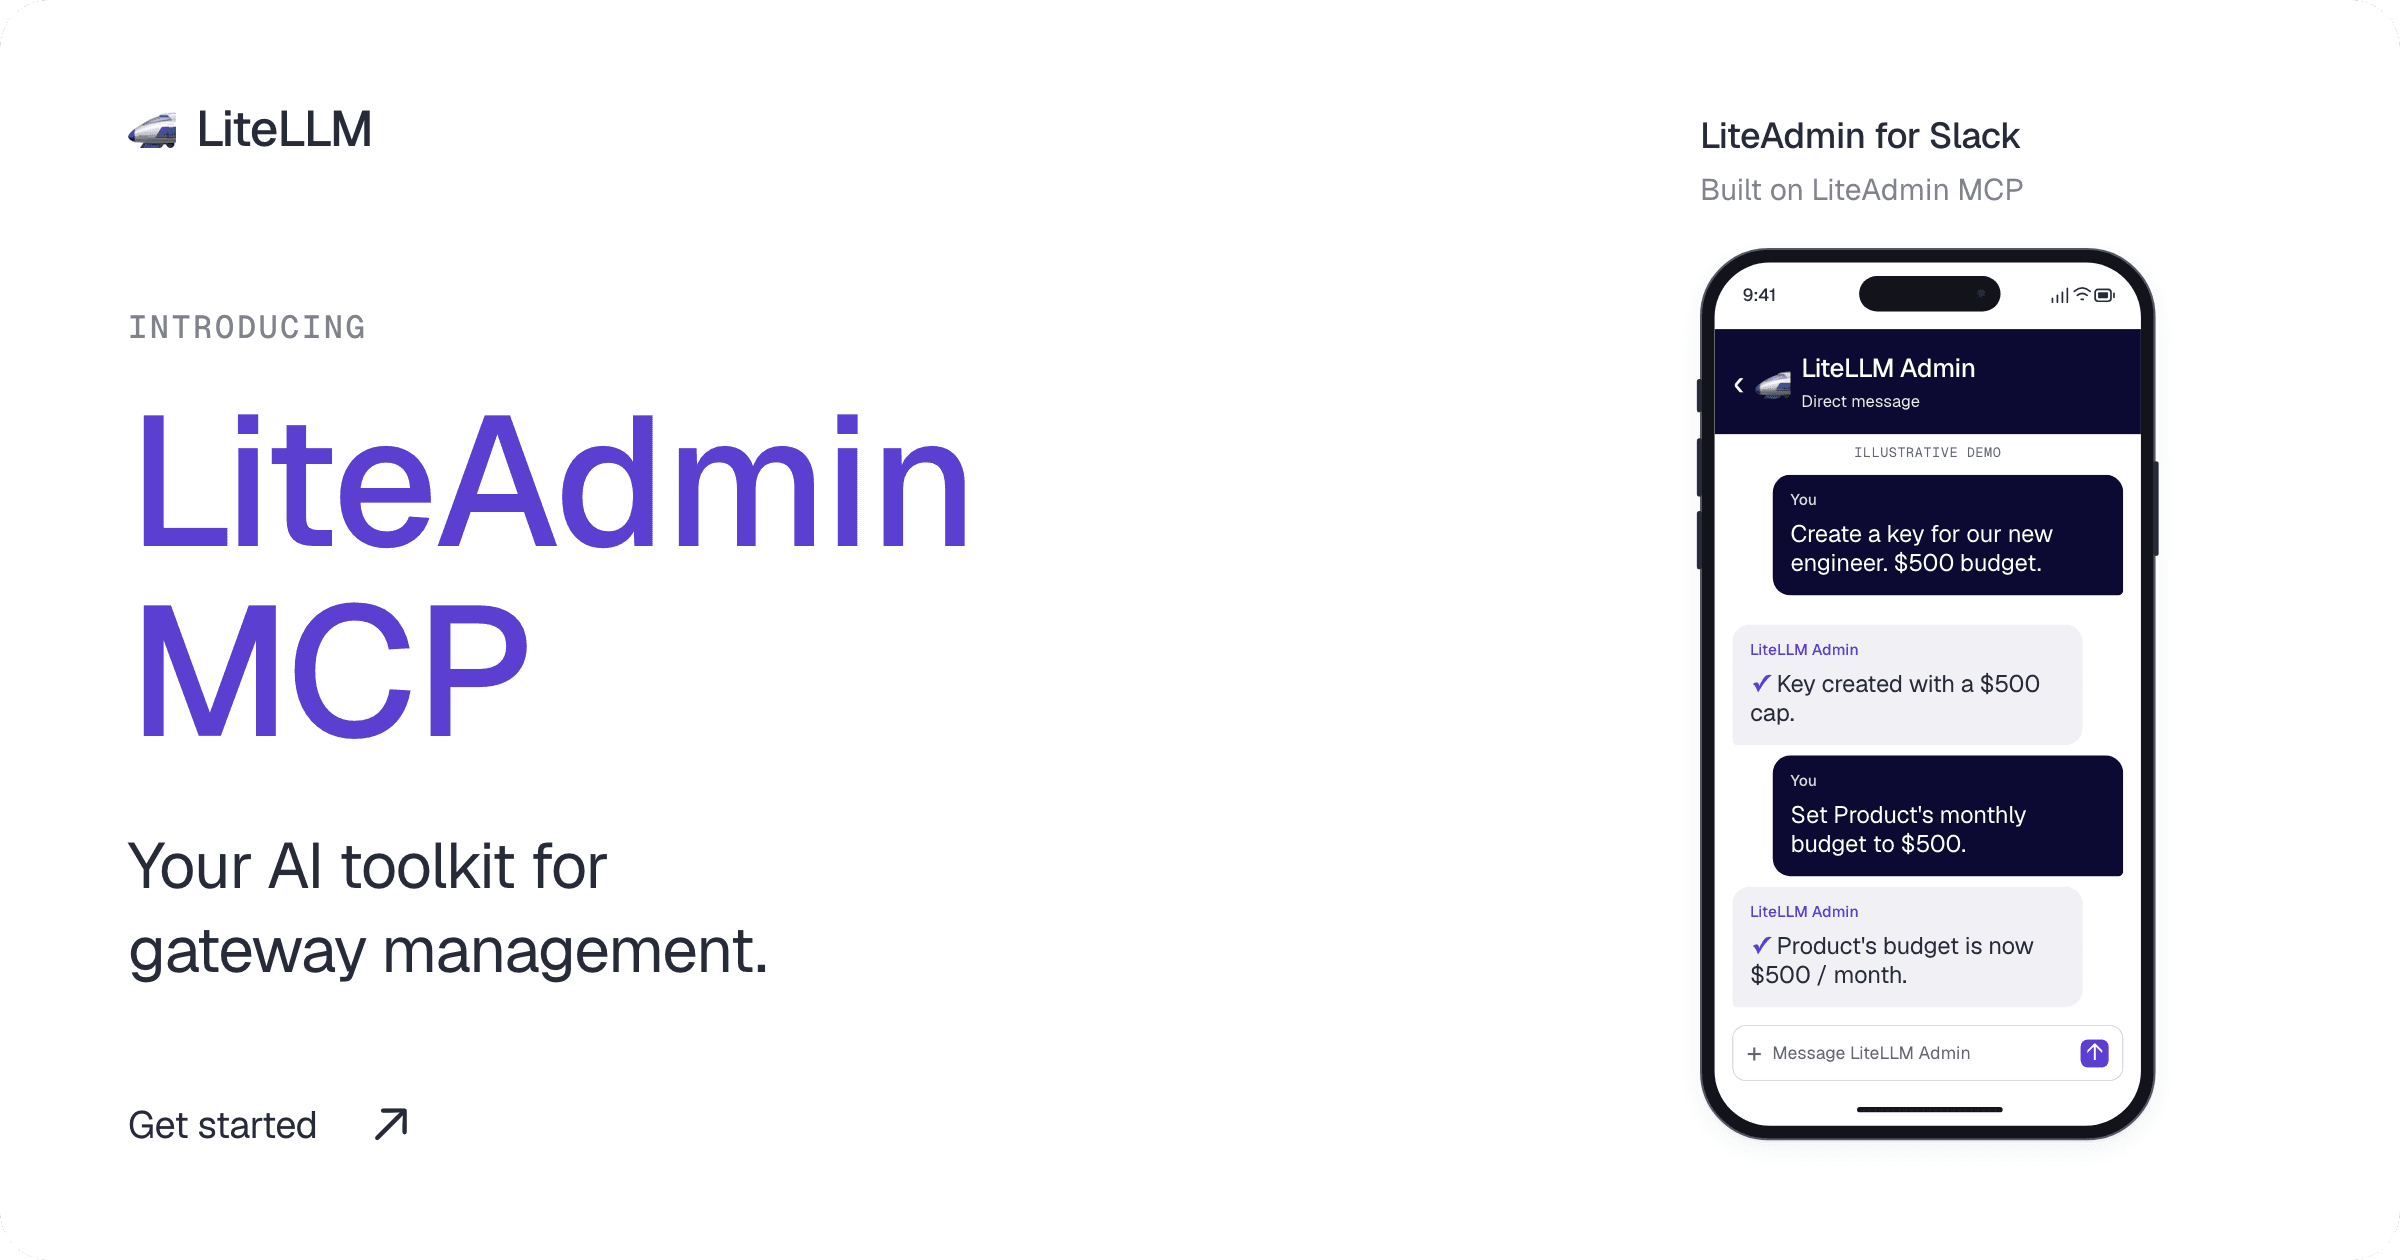
Introducing LiteAdmin MCP
Give your agent tools to create keys, add models, and manage budgets with LiteAdmin MCP. Use the same connector through LiteAdmin, our Slack admin agent.
Day 0 Support: GPT-6 Sol and GPT-6 Luna
Day 0 support for GPT-6 Sol and GPT-6 Luna on LiteLLM, at half the price of their GPT-5.6 counterparts.
Day 0 Support: Claude Opus 5.5
Day 0 support for Claude Opus 5.5 on the LiteLLM AI Gateway. Use it across Anthropic, Bedrock, Gemini Enterprise Agent Platform, and Azure.
Getting Started with Fireworks AI on LiteLLM
A beginner tutorial: run an open model on Fireworks AI behind a LiteLLM gateway, call it with the OpenAI SDK you already use, then add a second model and a fallback.
Day 0 Support: Xiaomi MiMo V2.6
Day 0 support for Xiaomi MiMo V2.6 Pro and Flash on LiteLLM, priced on the native route for the first time.
Claude Code server-side auto mode through LiteLLM
Anthropic is moving Claude Code auto mode's safety classifier server-side. LiteLLM's native /v1/messages route now forwards the safeguards contract to the Anthropic API, Bedrock InvokeModel, Bedrock Mantle and Vertex AI. Here is the contract, what changed, which releases carry it, and how to verify it.
Day 0 Support: Grok 4.7
Day 0 support for Grok 4.7 on LiteLLM, at the same price as Grok 4.6.
JEV Classifier: 5.43x as Fast as Haiku, 96% Lower Cost
JEV classified requests 5.43x as fast as Haiku by median latency in our AI Gateway benchmark. Explore the setup, cost savings and methodology.
TypeSafe Jev on LiteLLM
TypeSafe AI's Jev lands in LiteLLM v1.103.0-rc: call it through the proxy with logging and cost tracking.
Auto-Router: Switching Tiers Without Encrypted Content Failures
How LiteLLM safely removes undecryptable encrypted reasoning from cross-tier follow-ups so Auto-Router can keep routing requests
Day 0 Support: Qwen3.8-Omni-Flash
Day 0 support for Qwen3.8-Omni-Flash on LiteLLM, with text, image, audio and video input.
Reduce agent context with TypeSafe Jev and LiteLLM
Use TypeSafe Jev to remove old tool results from bot conversations and enable compaction for a team in LiteLLM.
Auto Router: 5 Improvements for Cost, Speed, and Team Control
Five Auto Router updates: cache-cost estimates, Fast Mode by tier, team-managed routers, live CLI stats, and more accurate Anthropic savings.
September Townhall: Product + Roadmap Updates
Join the LiteLLM September townhall on Thursday, 24 September at 7:30 AM PT to learn about LiteLLM's product updates and roadmap.
Auto Router: Maximize Quality & Savings with Our Fuse LLM Classifier
We’re improving Fuse V2 by combining complexity and capability assessment to learn where each model succeeds, fails, and needs an upgrade.
OCR uses Rust by default starting with v1.102.0-rc.1
Starting with v1.102.0-rc.1, OCR calls use the Rust implementation by default while preserving the existing API.
Incident Report: Retry Breadcrumb Memory Growth Causing OOM on v1.100.0
Date: September 7 to September 9, 2026
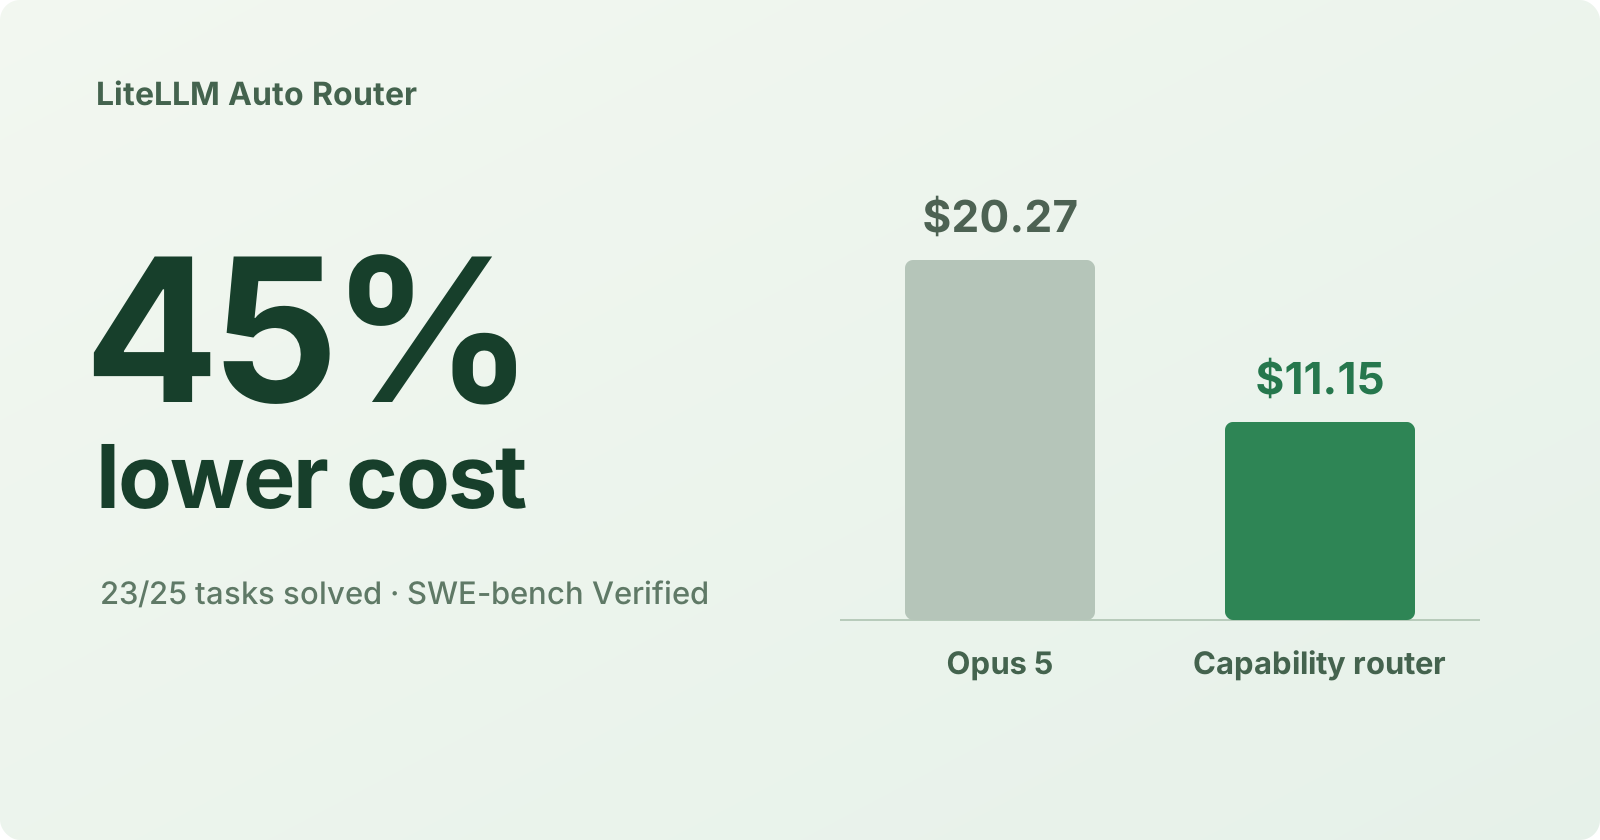
Auto Router: 45% Lower Cost on 25 SWE-bench Tasks
We solved 23 of 25 SWE-bench Verified tasks with LiteLLM's experimental capability router for $11.15, compared with $20.27 using Opus 5.
How Pfizer Improved LiteLLM Gateway Performance and Resiliency at Scale
How Pfizer AI Platform Engineering isolated a Redis connection handling bug that cut LiteLLM gateway throughput by ~48% with zero HTTP errors, reduced CI load-test latency by 76%, and built a regression prevention framework with LiteLLM.
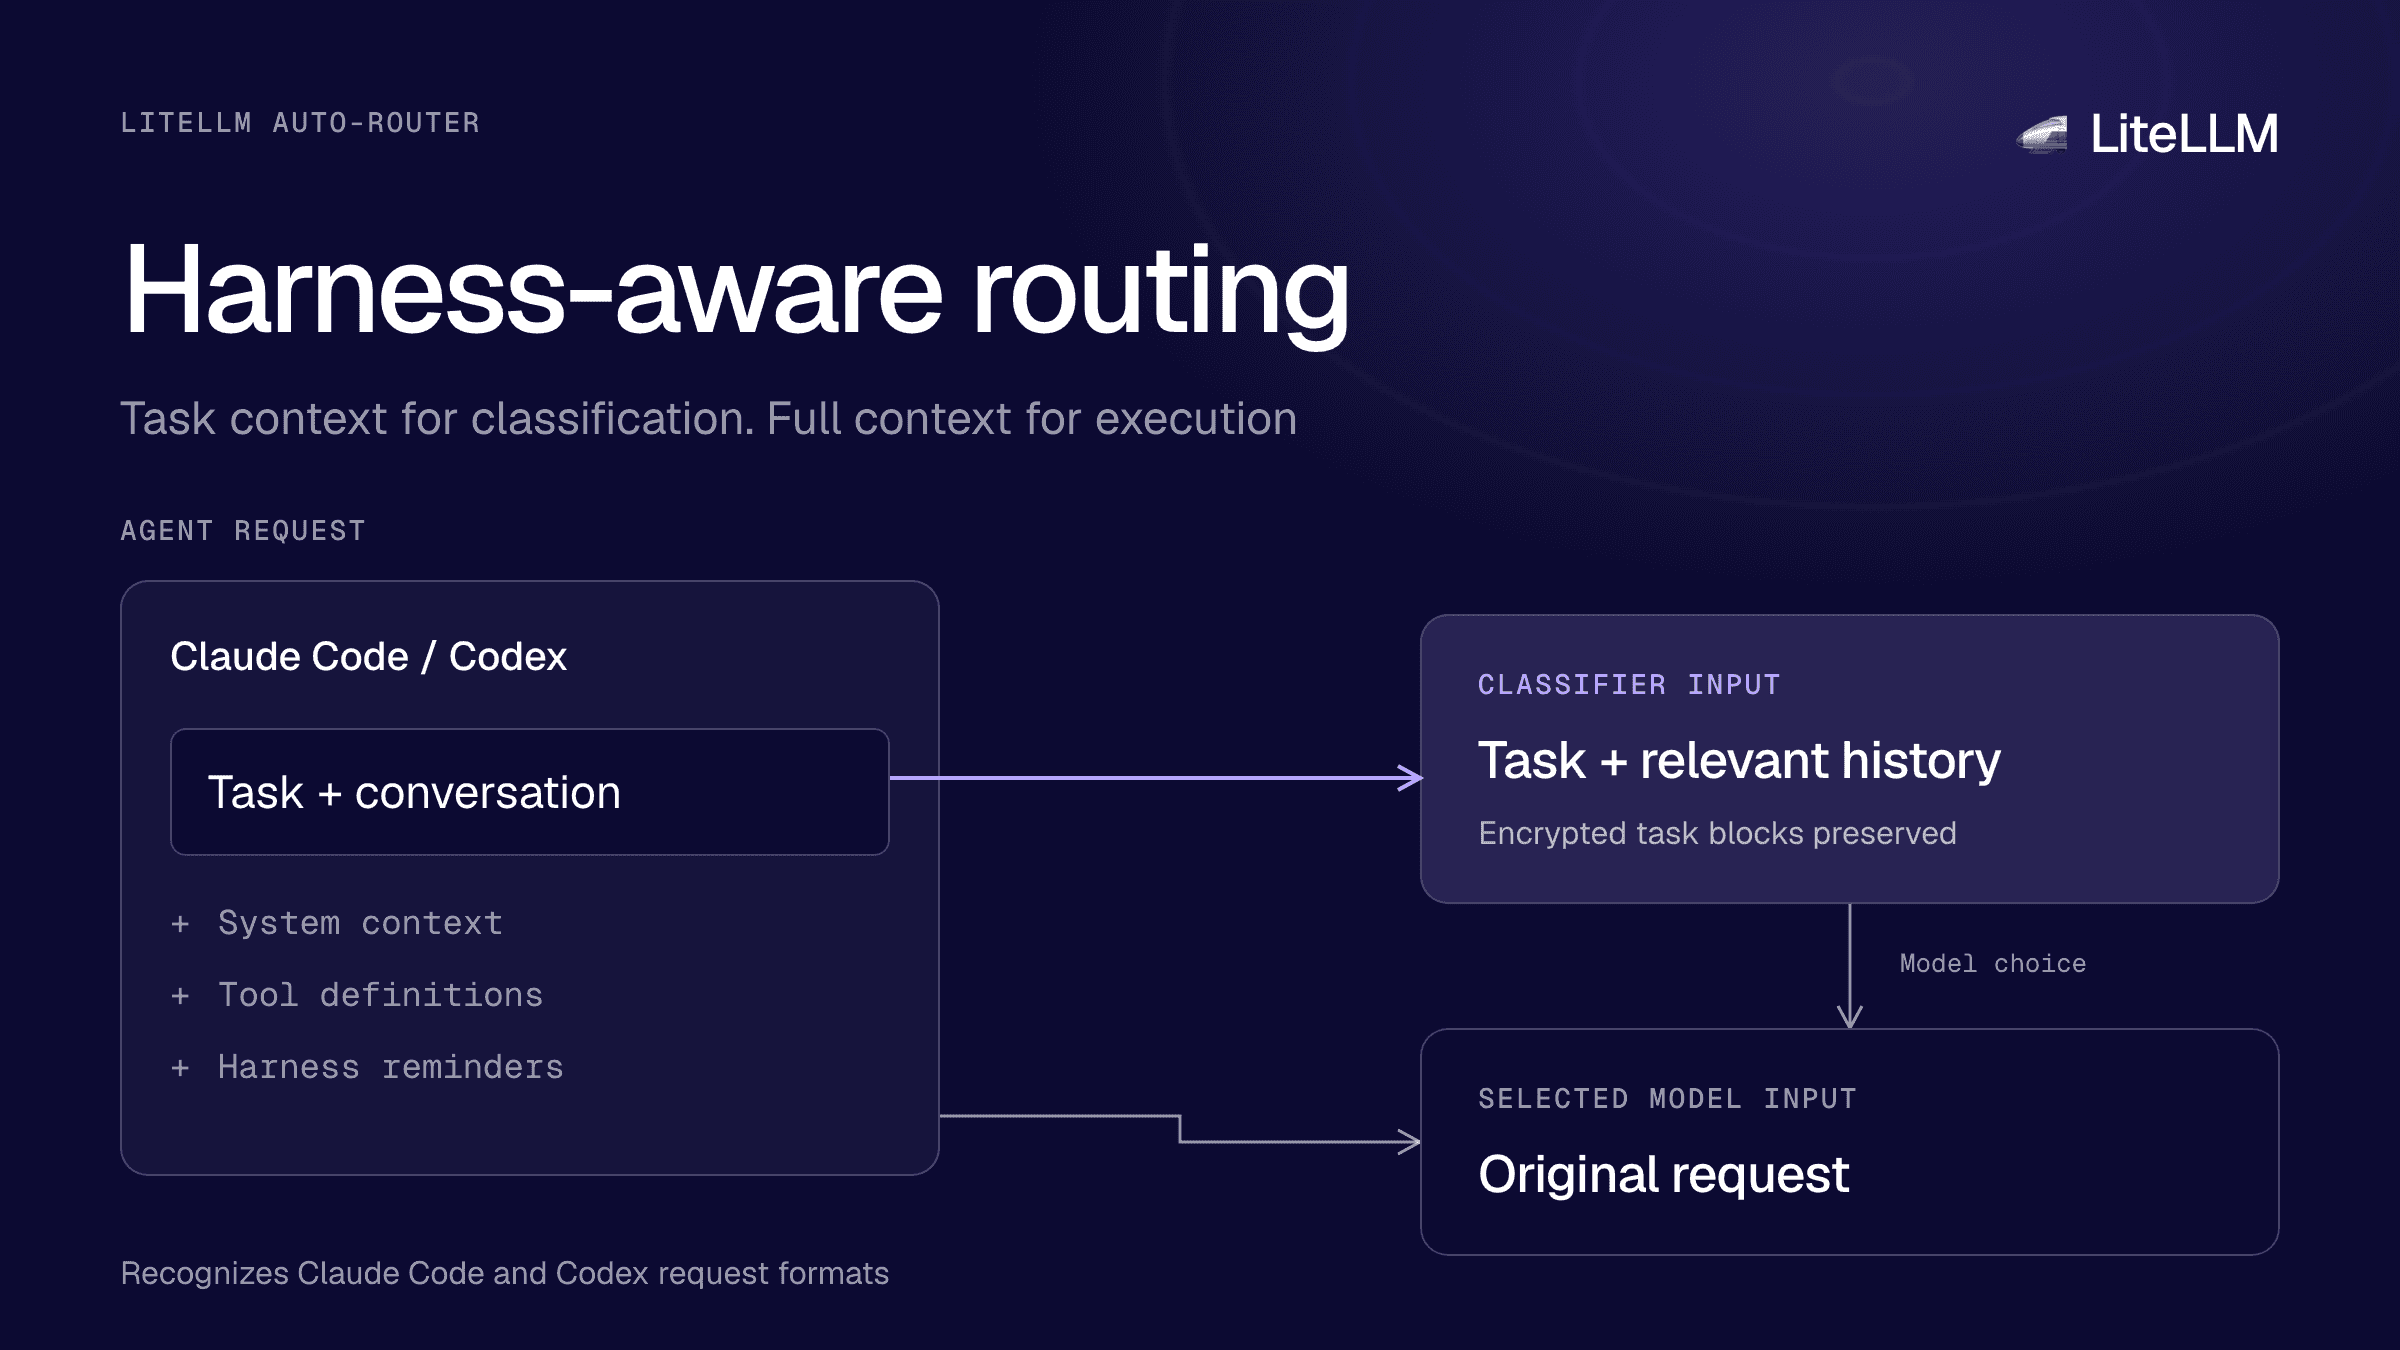
Auto-Router Updates: Harness-Aware Routing
Harness-aware Auto-Router updates for Claude Code and Codex: less classifier context, encrypted task support, and clearer routing logs.
Secure shared AI agents with identity-aware access and spend controls
How LiteLLM preserves caller identity across shared agents, governs model and MCP access, and enforces independent budgets for each business unit.
AutoRouter: Tune Heuristics for Your Traffic
Tune AutoRouter heuristic dimensions for specific workloads, improve classification accuracy, and configure tiers from models you already serve.
Our Updated SOC 2 Type 2 Report Is Available
LiteLLM's updated SOC 2 Type 2 report is now available through the LiteLLM Trust Center.
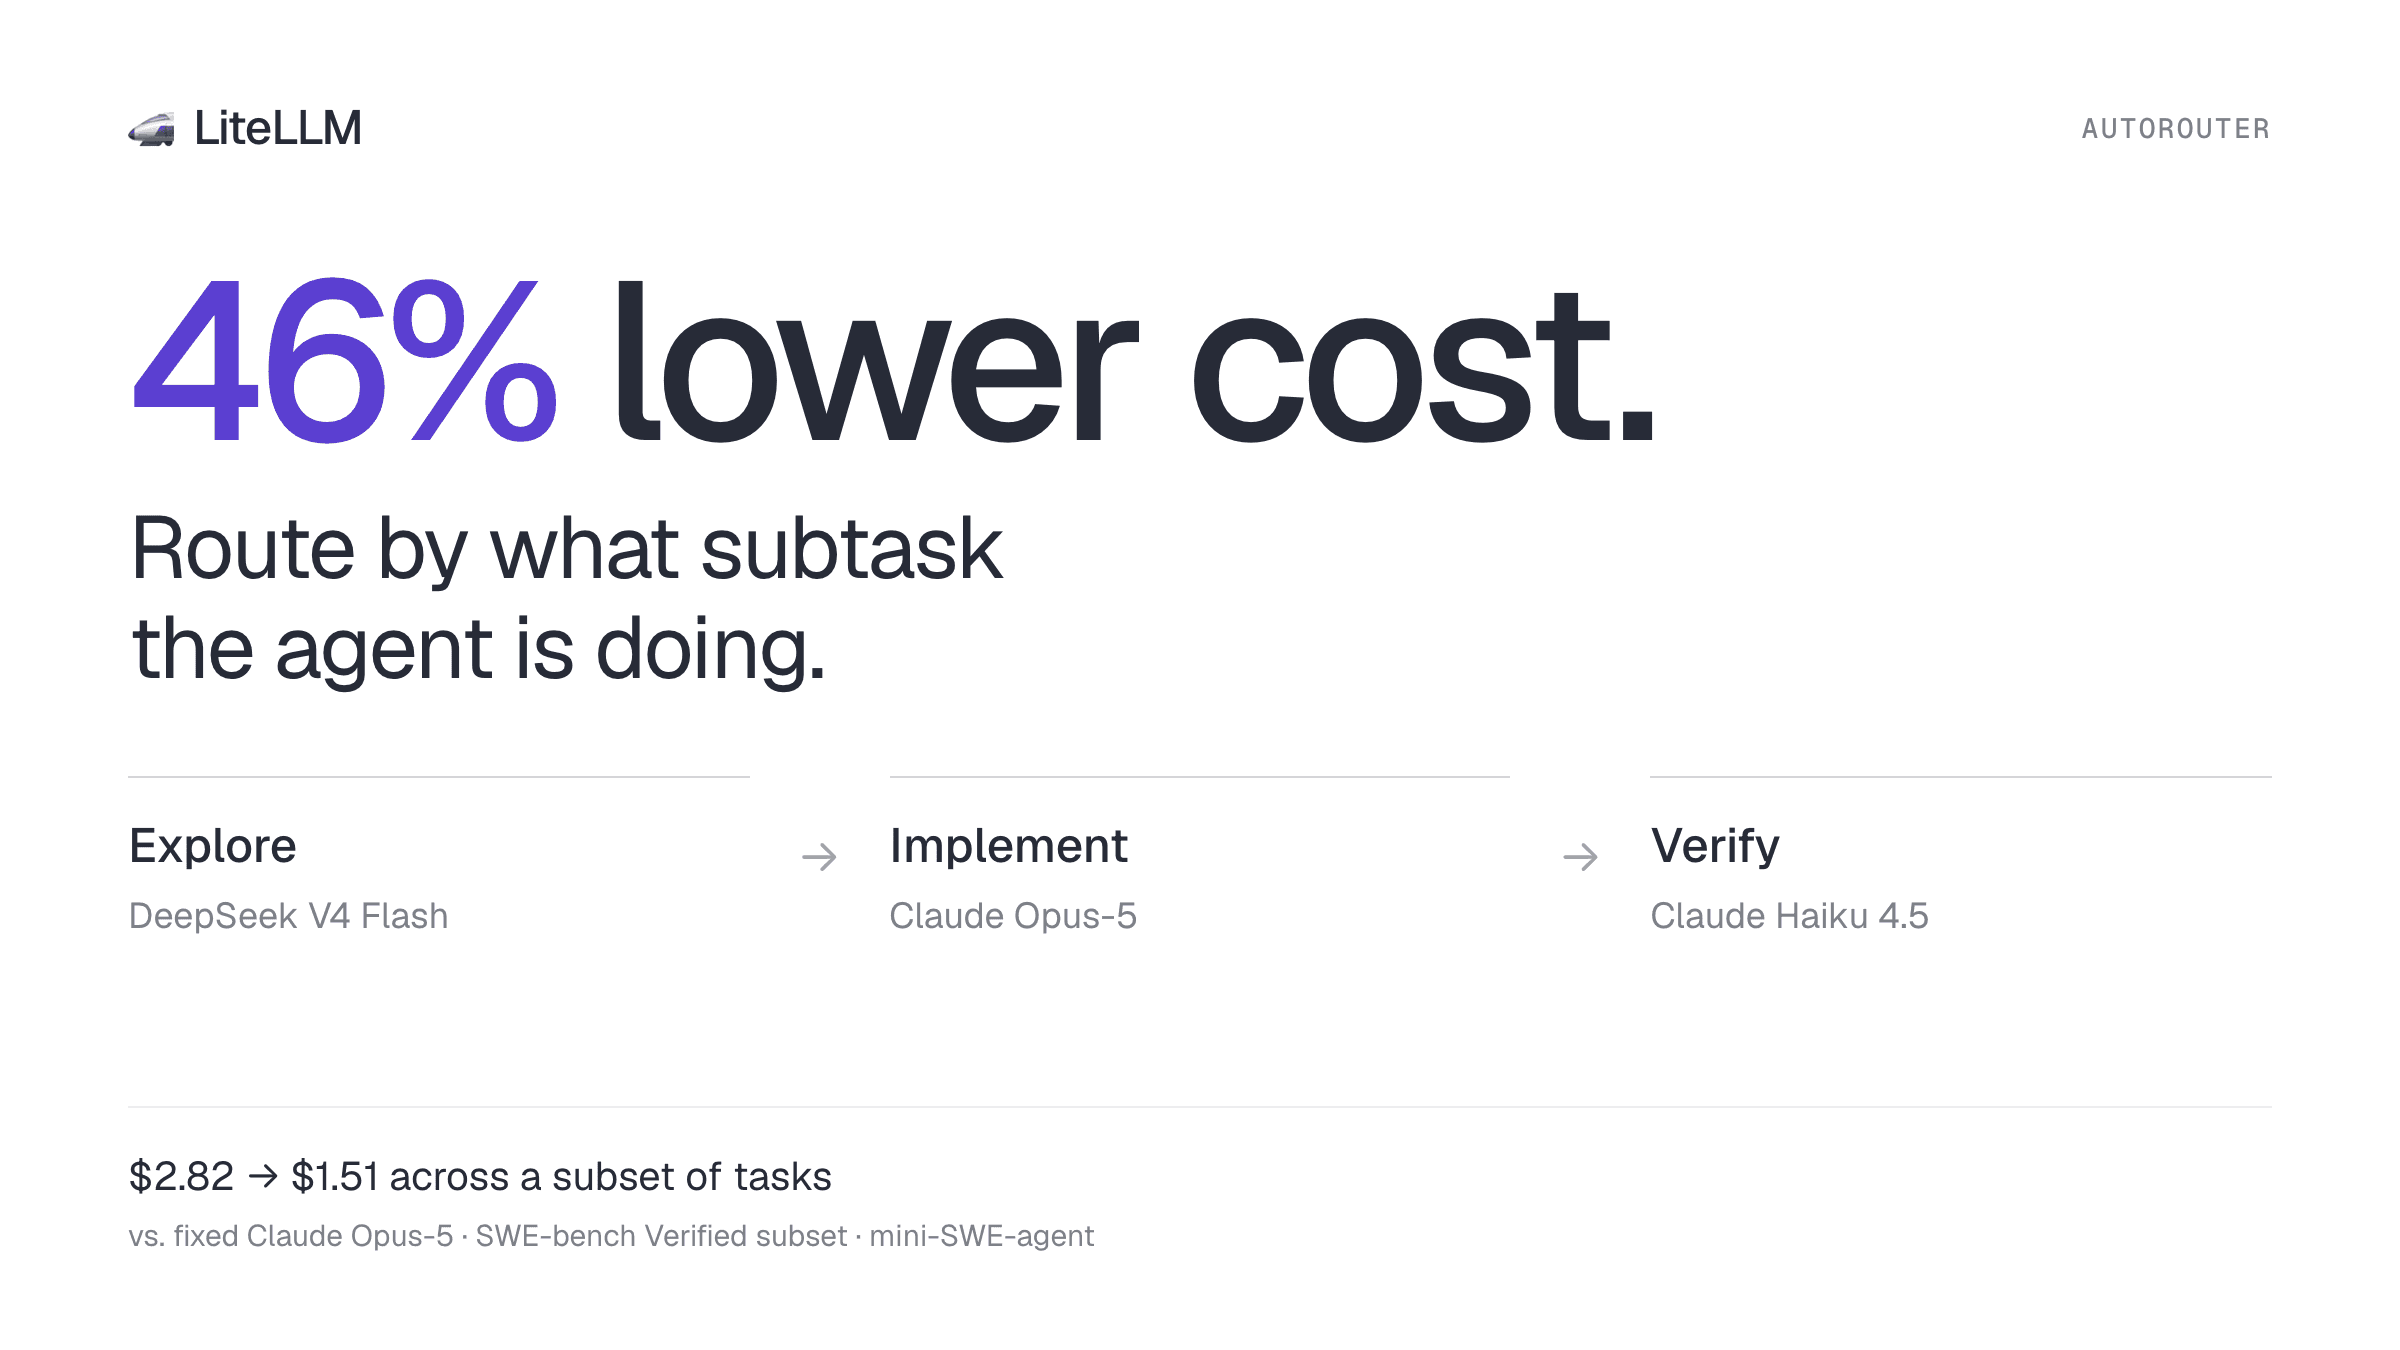
Subtask-Specific Routing: Same Quality, 46% Less Cost
Routing each agent turn by what the agent is doing, exploring, implementing, or verifying, instead of by how hard the prompt looks. On a SWE-bench Verified subset it matched fixed Claude Opus-5 quality for 46% less, with 86% of turns never touching a frontier model.
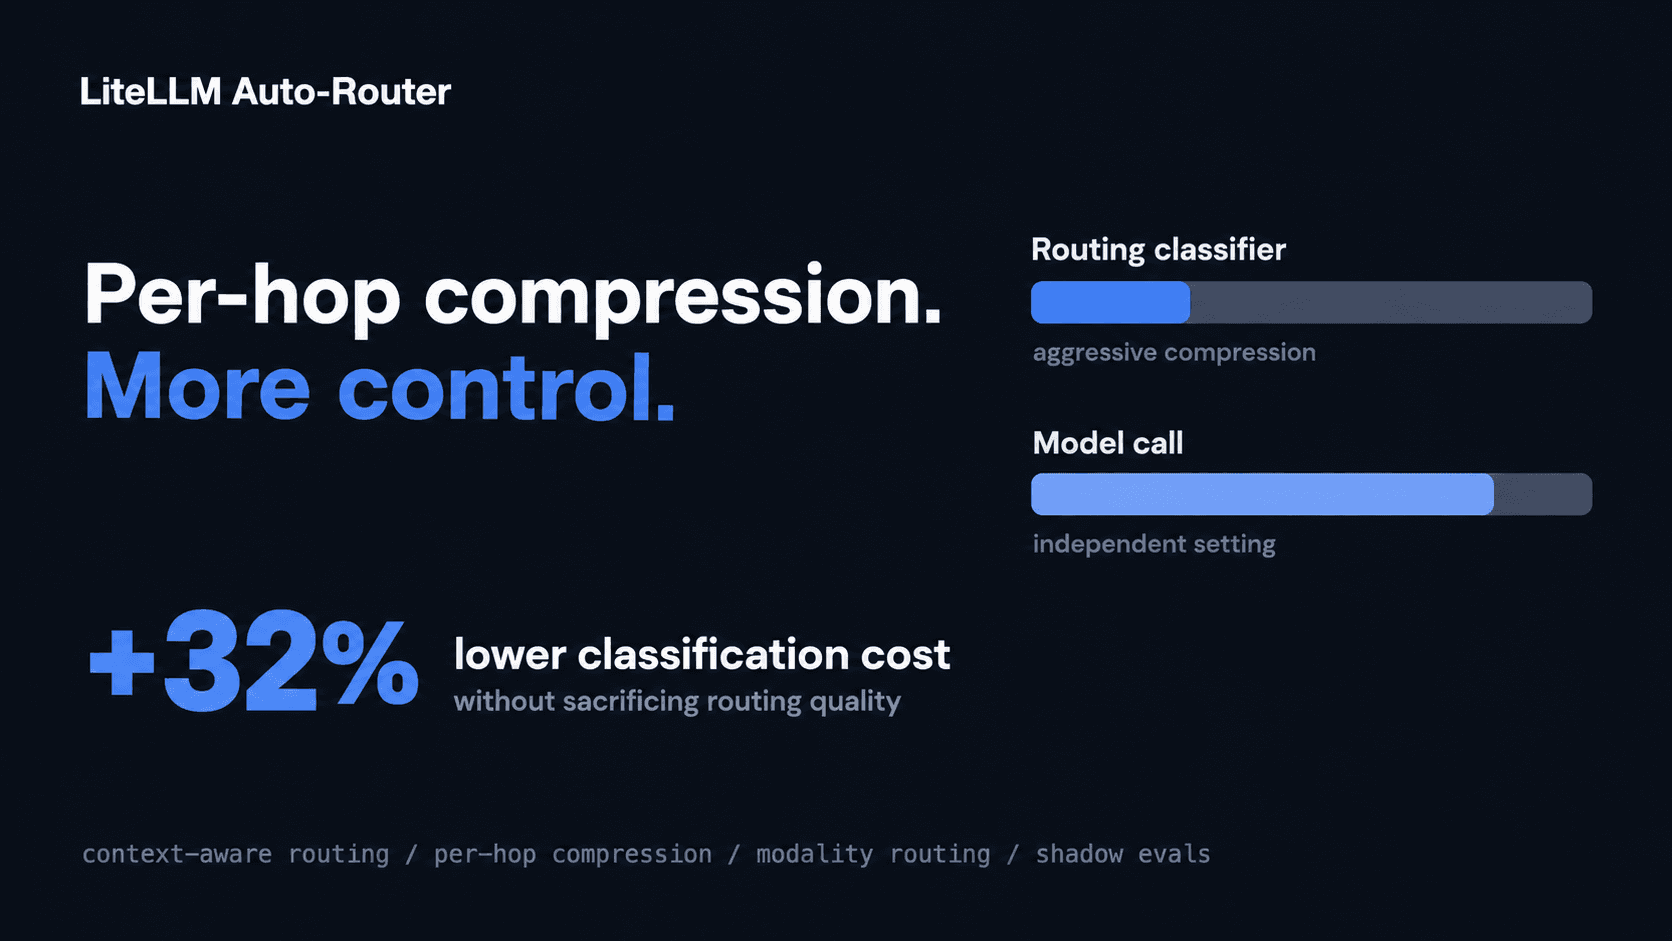
AutoRouter Per-Hop Compression: Cut LLM Classifier Costs Another 32%
The complexity router's LLM classifier can now use different compression than the model call it routes to. The classifier only needs enough context to route correctly, not to generate an answer. In internal testing, compressing it aggressively cut classification costs a further 32% beyond shared compression, with no change in routing accuracy.
Auto-Router: Escalate a Task That Gets Stuck
The Auto-Router now reads the assistant's own recent tool calls, notices when an agentic task is stuck in a retry loop, and escalates it one tier automatically, the same bump escalation_keywords already offers.
Day 0 Support: GPT-6 Astra
Day 0 support for OpenAI's GPT-6 Astra on LiteLLM, with pricing, reasoning params, and the Responses API bridge.
Day 0 support: Meta Muse Spark 1.3
Day 0 support for Meta Muse Spark 1.3 on LiteLLM, with cost tracking for both the standard and contributor tiers.
Day 0 support: Gemini 3.8 Flash
day 0 support for Gemini 3.8 Flash on LiteLLM, with launch pricing tracked across Google AI Studio and Vertex AI.
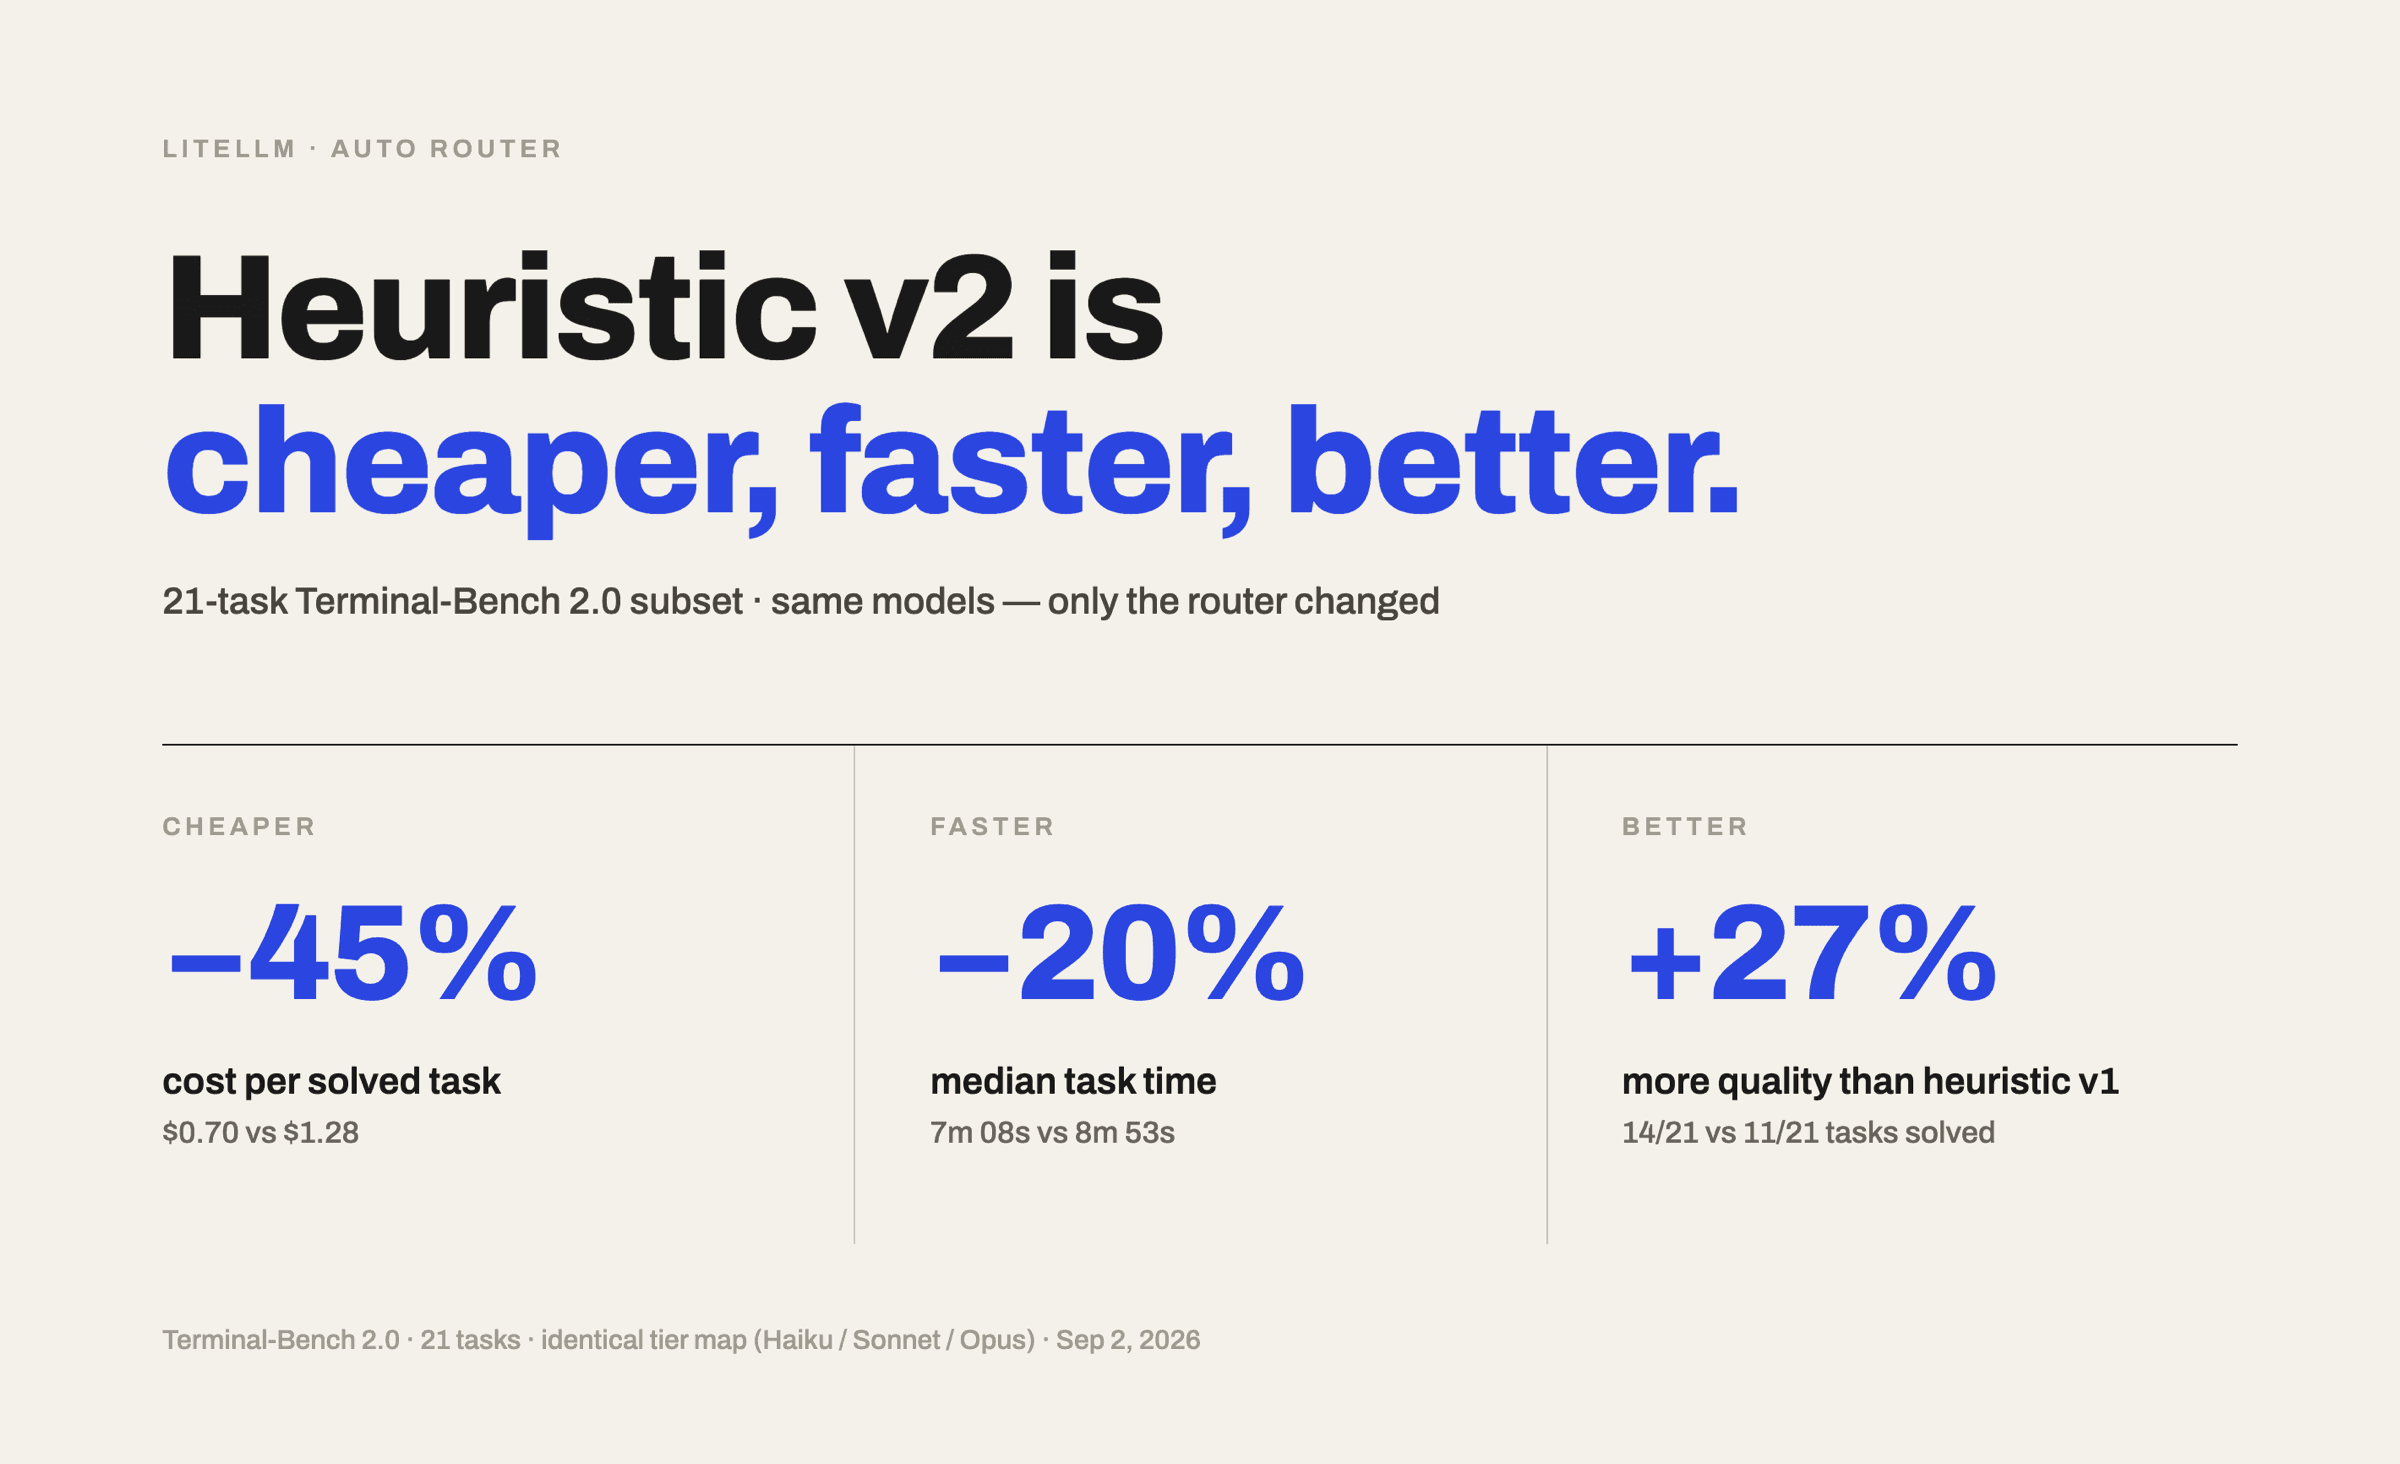
Introducing AutoRouter Heuristic v2: 27% More Tasks Solved at 45% Lower Cost
Heuristic v2 is a new classifier for LiteLLM's AutoRouter, pretrained across multiple rounds of graded response data so it ships with zero cold start. On a 21-task Terminal-Bench 2.0 subset it solved 3 more tasks than Heuristic v1, at 45% lower cost per solved task and lower latency.
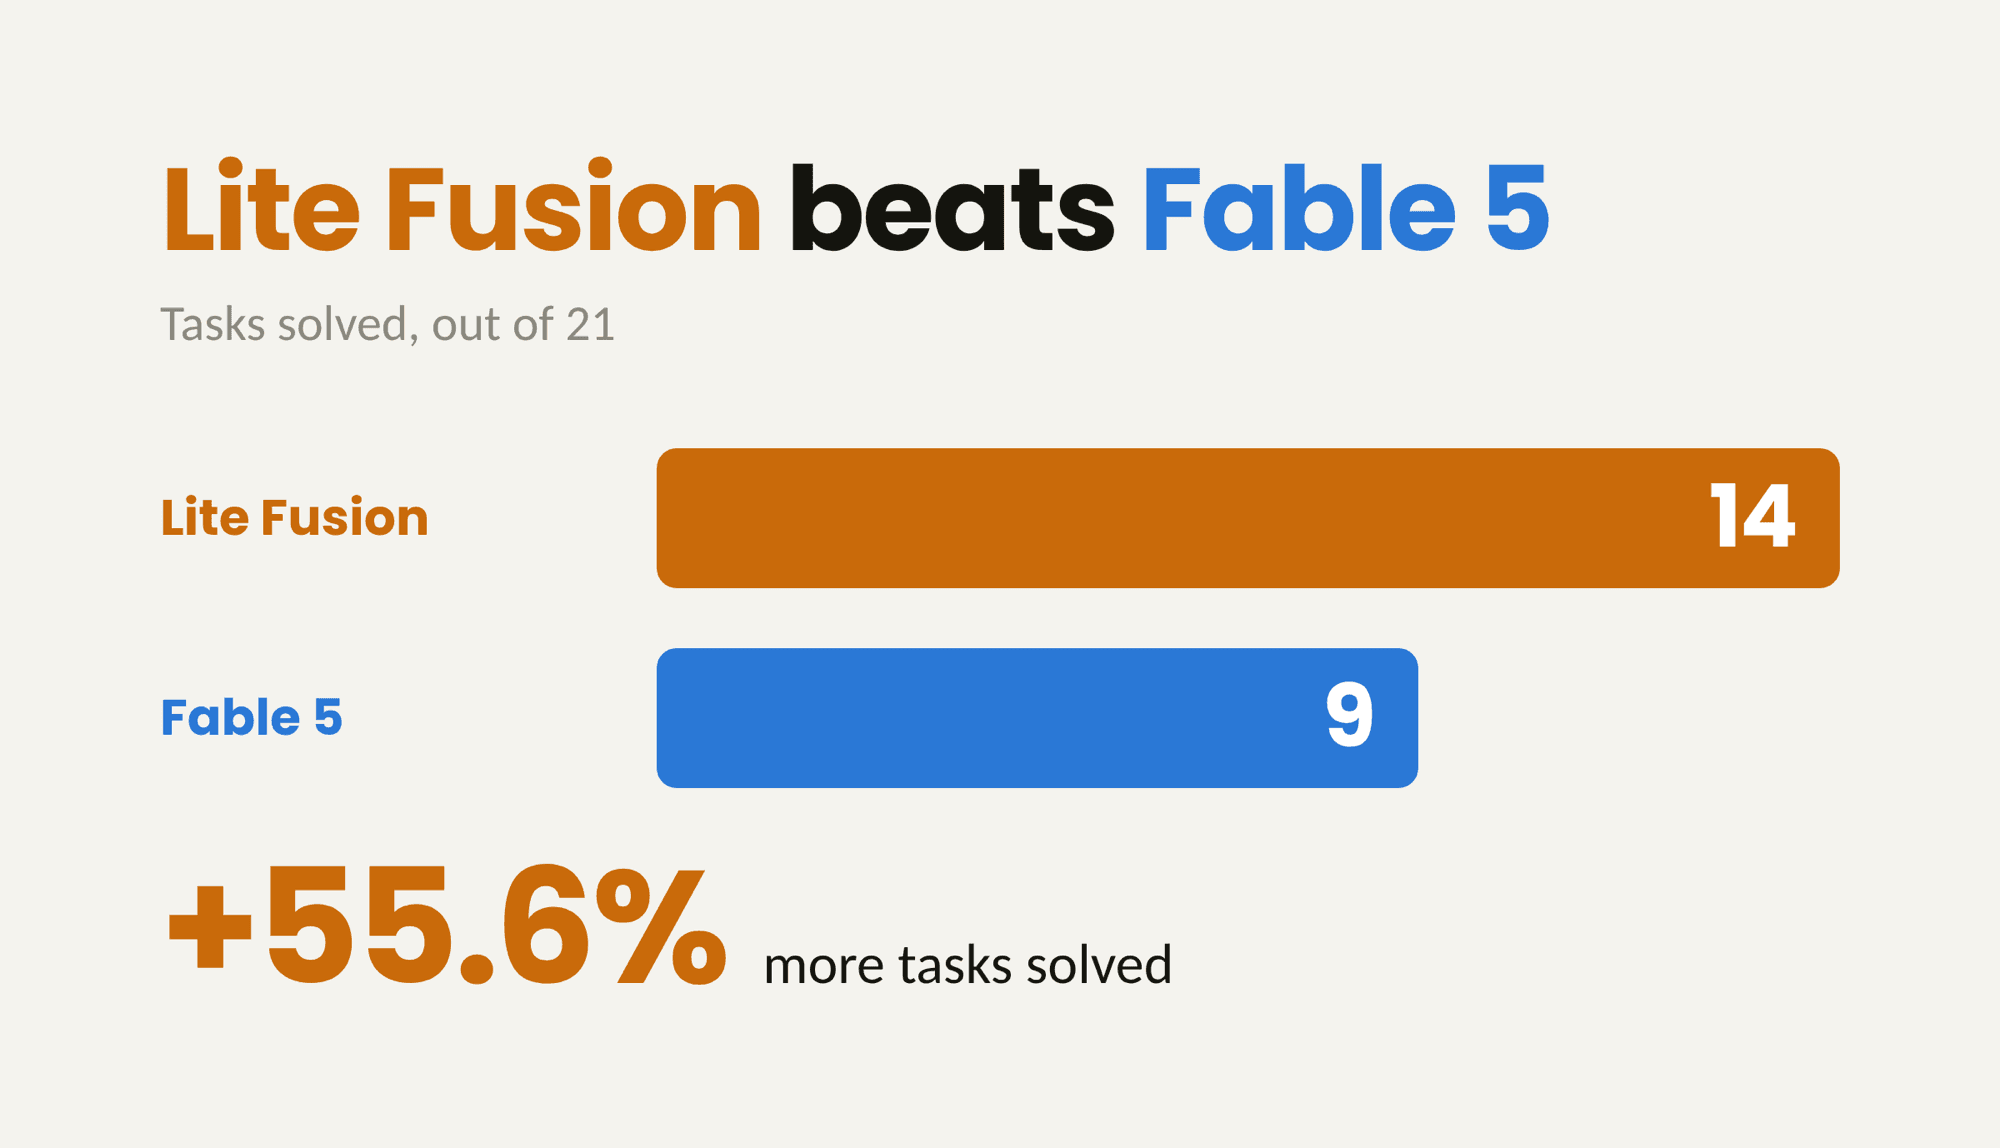
Introducing LiteLLM Fusion: 56% More Tasks Solved Than Fable 5
LiteLLM Auto Router Fusion ran three models on the same task and synthesized their work, solving 14 of 21 Terminal-Bench tasks against 9 for Claude Fable-5 alone. Total spend rose 36%, cost per solved task fell 12%, and turn latency went up 5x.
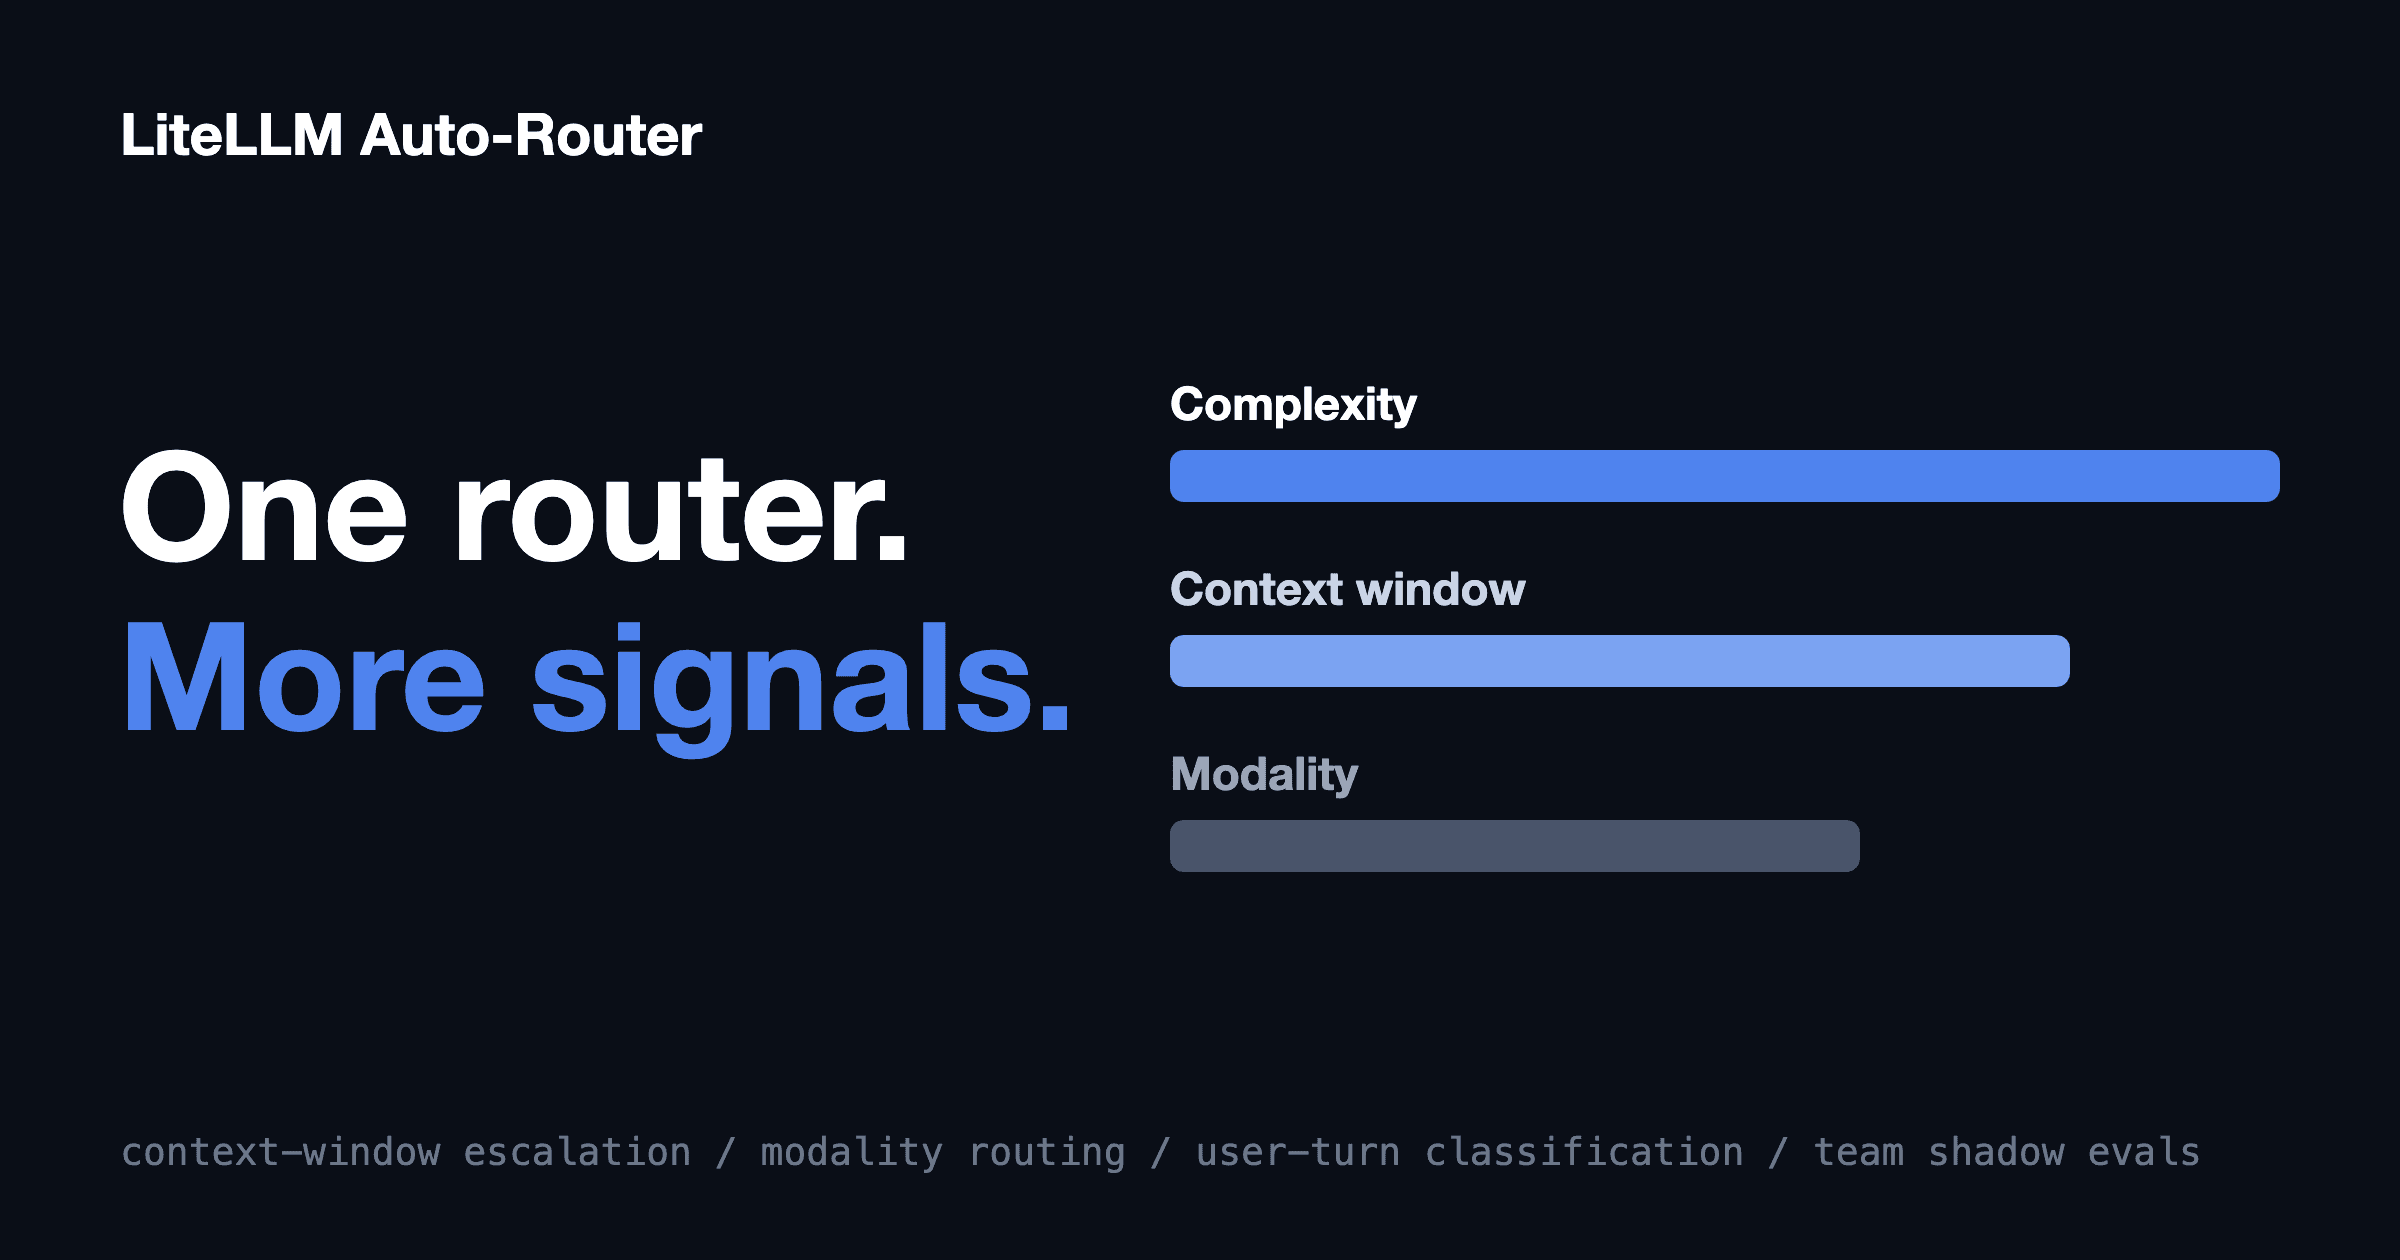
Auto-Router: Route on Context Size and Modality
The Auto-Router now supports more routing configurations: context-window escalation moves oversized prompts to the cheapest tier that fits them before dispatch, modality routing sends image requests to tiers that can see, classification can run on user turns only, and shadow evaluations can compare several router configs on a team's live traffic.
Day 0 Support: Claude Fable 5.1
Day 0 support for Claude Fable 5.1 on the LiteLLM AI Gateway, with the 0.025x cache read price tracked from the first call.
August Townhall Updates: Security, Stability, and Product
A recap of the August LiteLLM town hall: 79 security fixes, 375 bug fixes, 142 feature commits, a new Director of Security, the public status dashboard, and Auto-Router results from production.
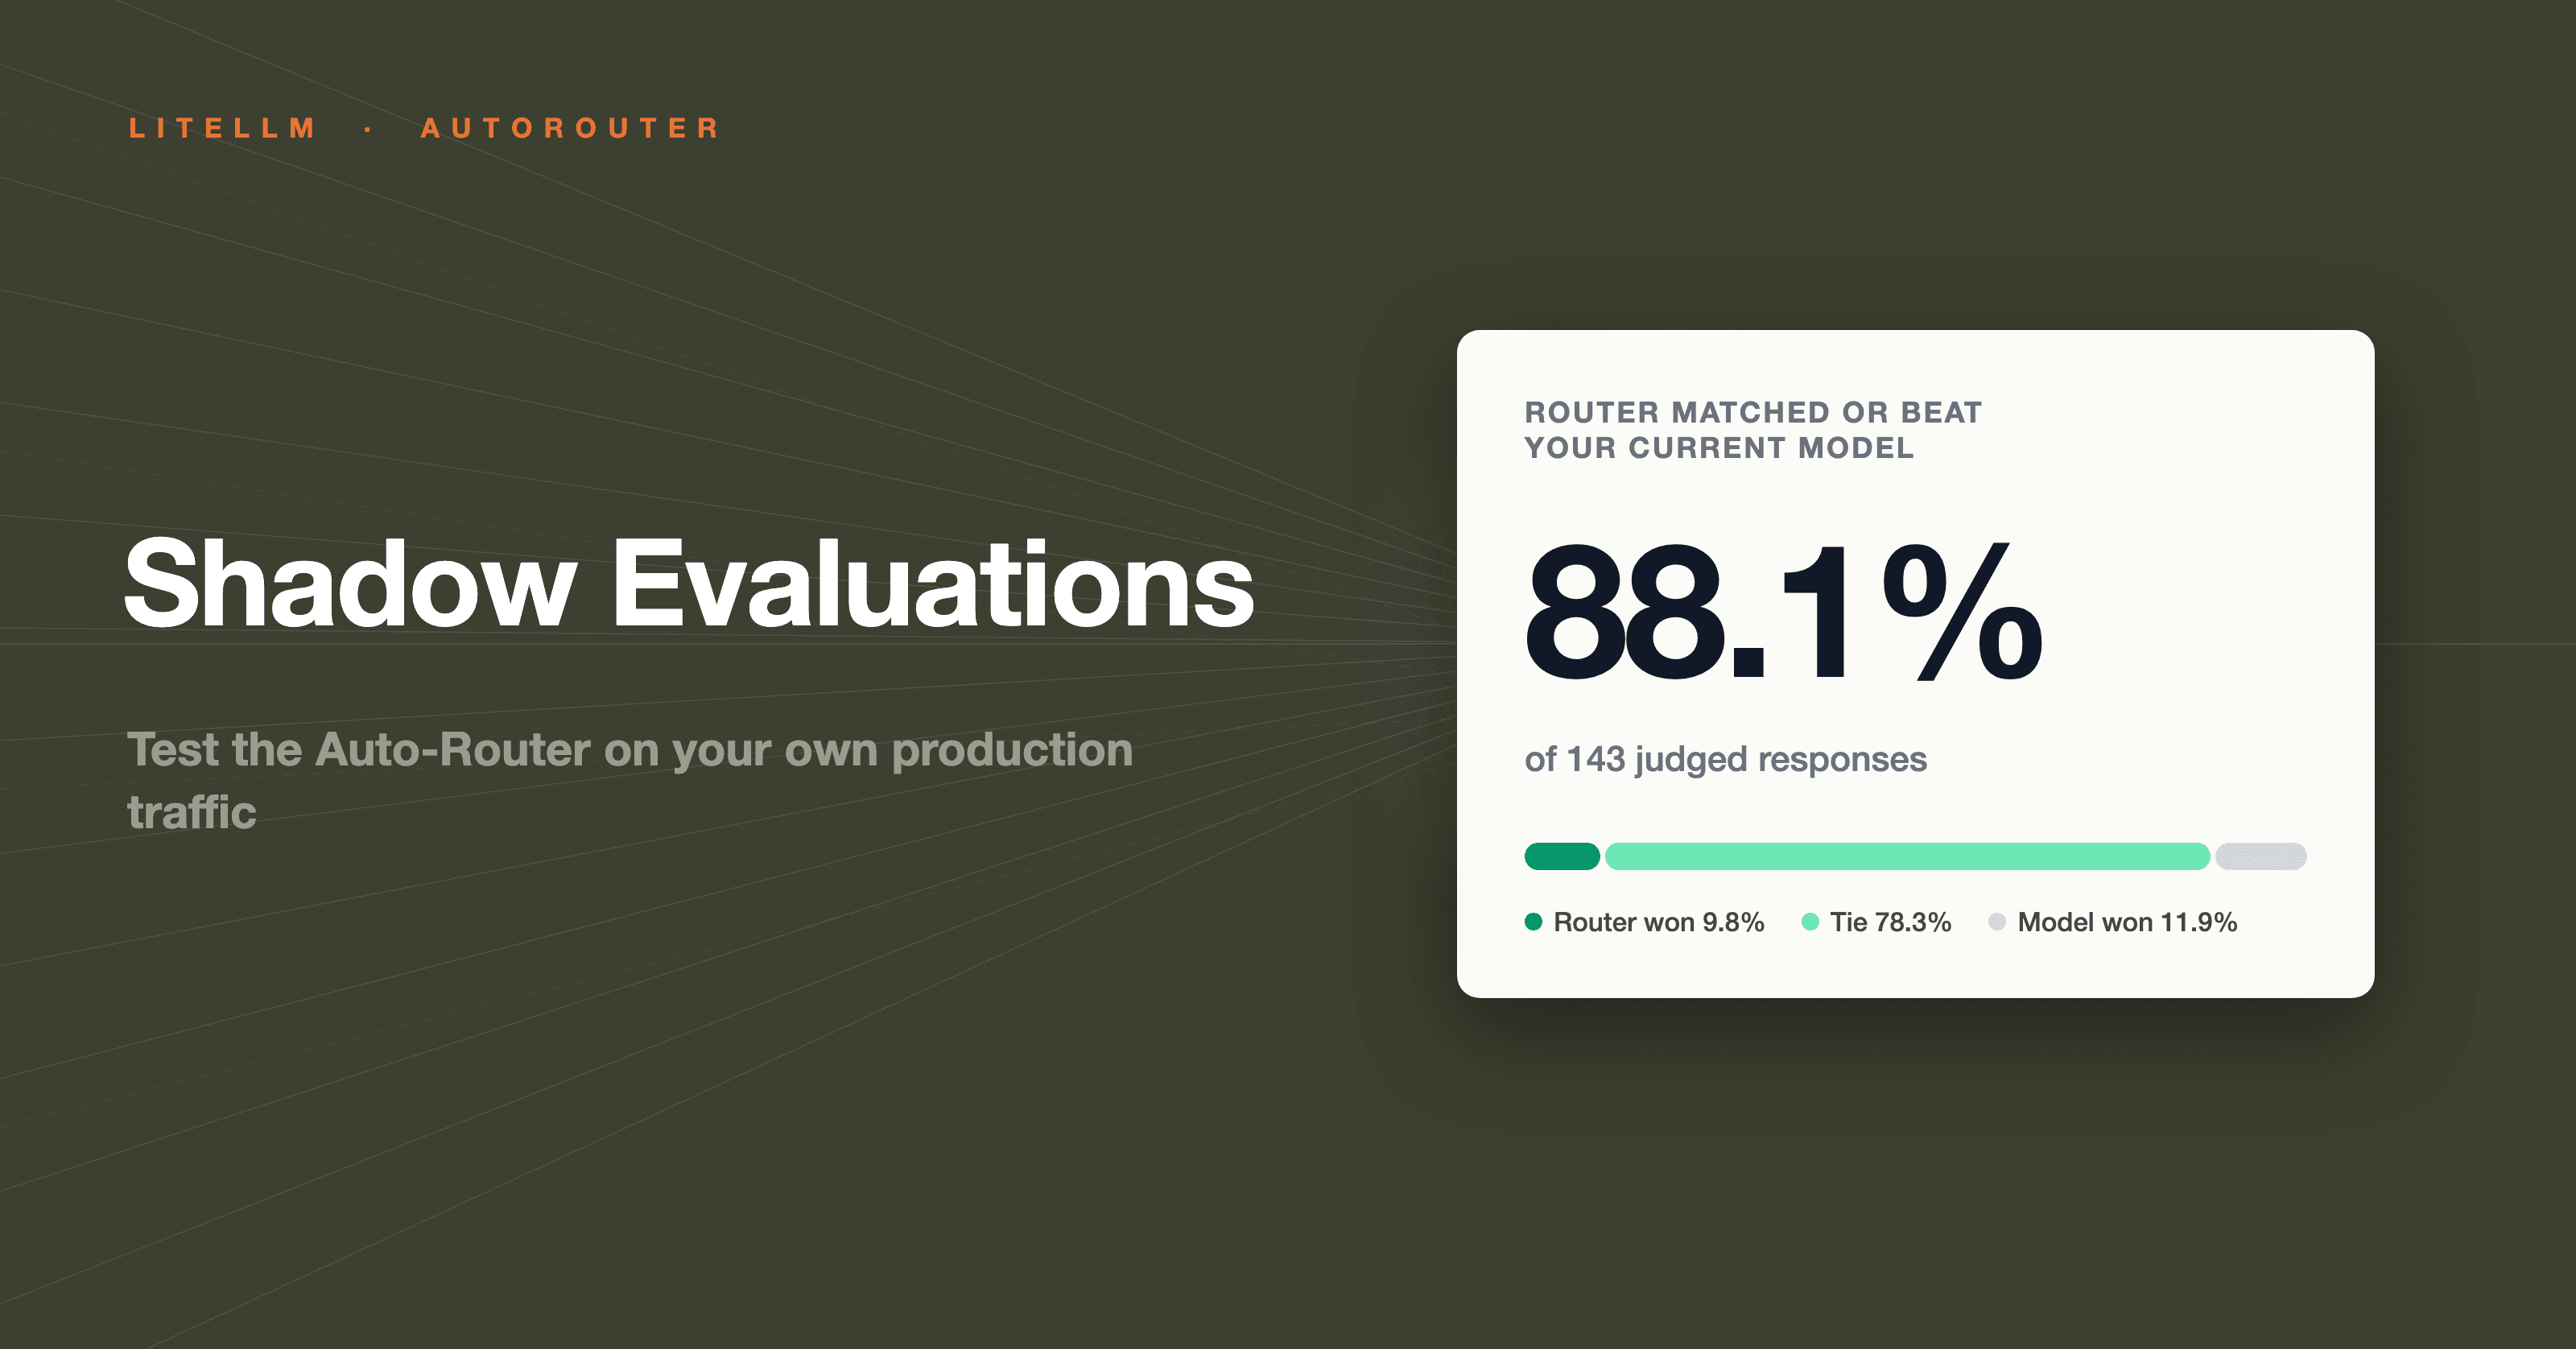
Shadow Evaluations: Test the Auto-Router on Your Own Production Traffic
Shadow evaluations duplicate a sampled slice of one key's live traffic through an auto-router and have an LLM judge blindly compare the answers. On our own traffic the router matched or beat the current model on 88.1% of judged responses, measured before a single user-facing response changed.
Day 0 support: Gemini 3.7 Flash
day 0 support for Gemini 3.7 Flash on LiteLLM, with launch pricing tracked across Google AI Studio and Vertex AI.
August Townhall: Product + Roadmap Updates
Join the LiteLLM August townhall on Thursday, 27 August at 7:30 AM PT to learn about LiteLLM's product updates and roadmap.
51% Cost Savings Reported From a Live Production Deployment
A LiteLLM customer rolled the Auto Router out to 450+ users in production and shared four months of numbers: 272,876 requests, 7.08 billion tokens, and $12,249 saved against an all-flagship baseline.
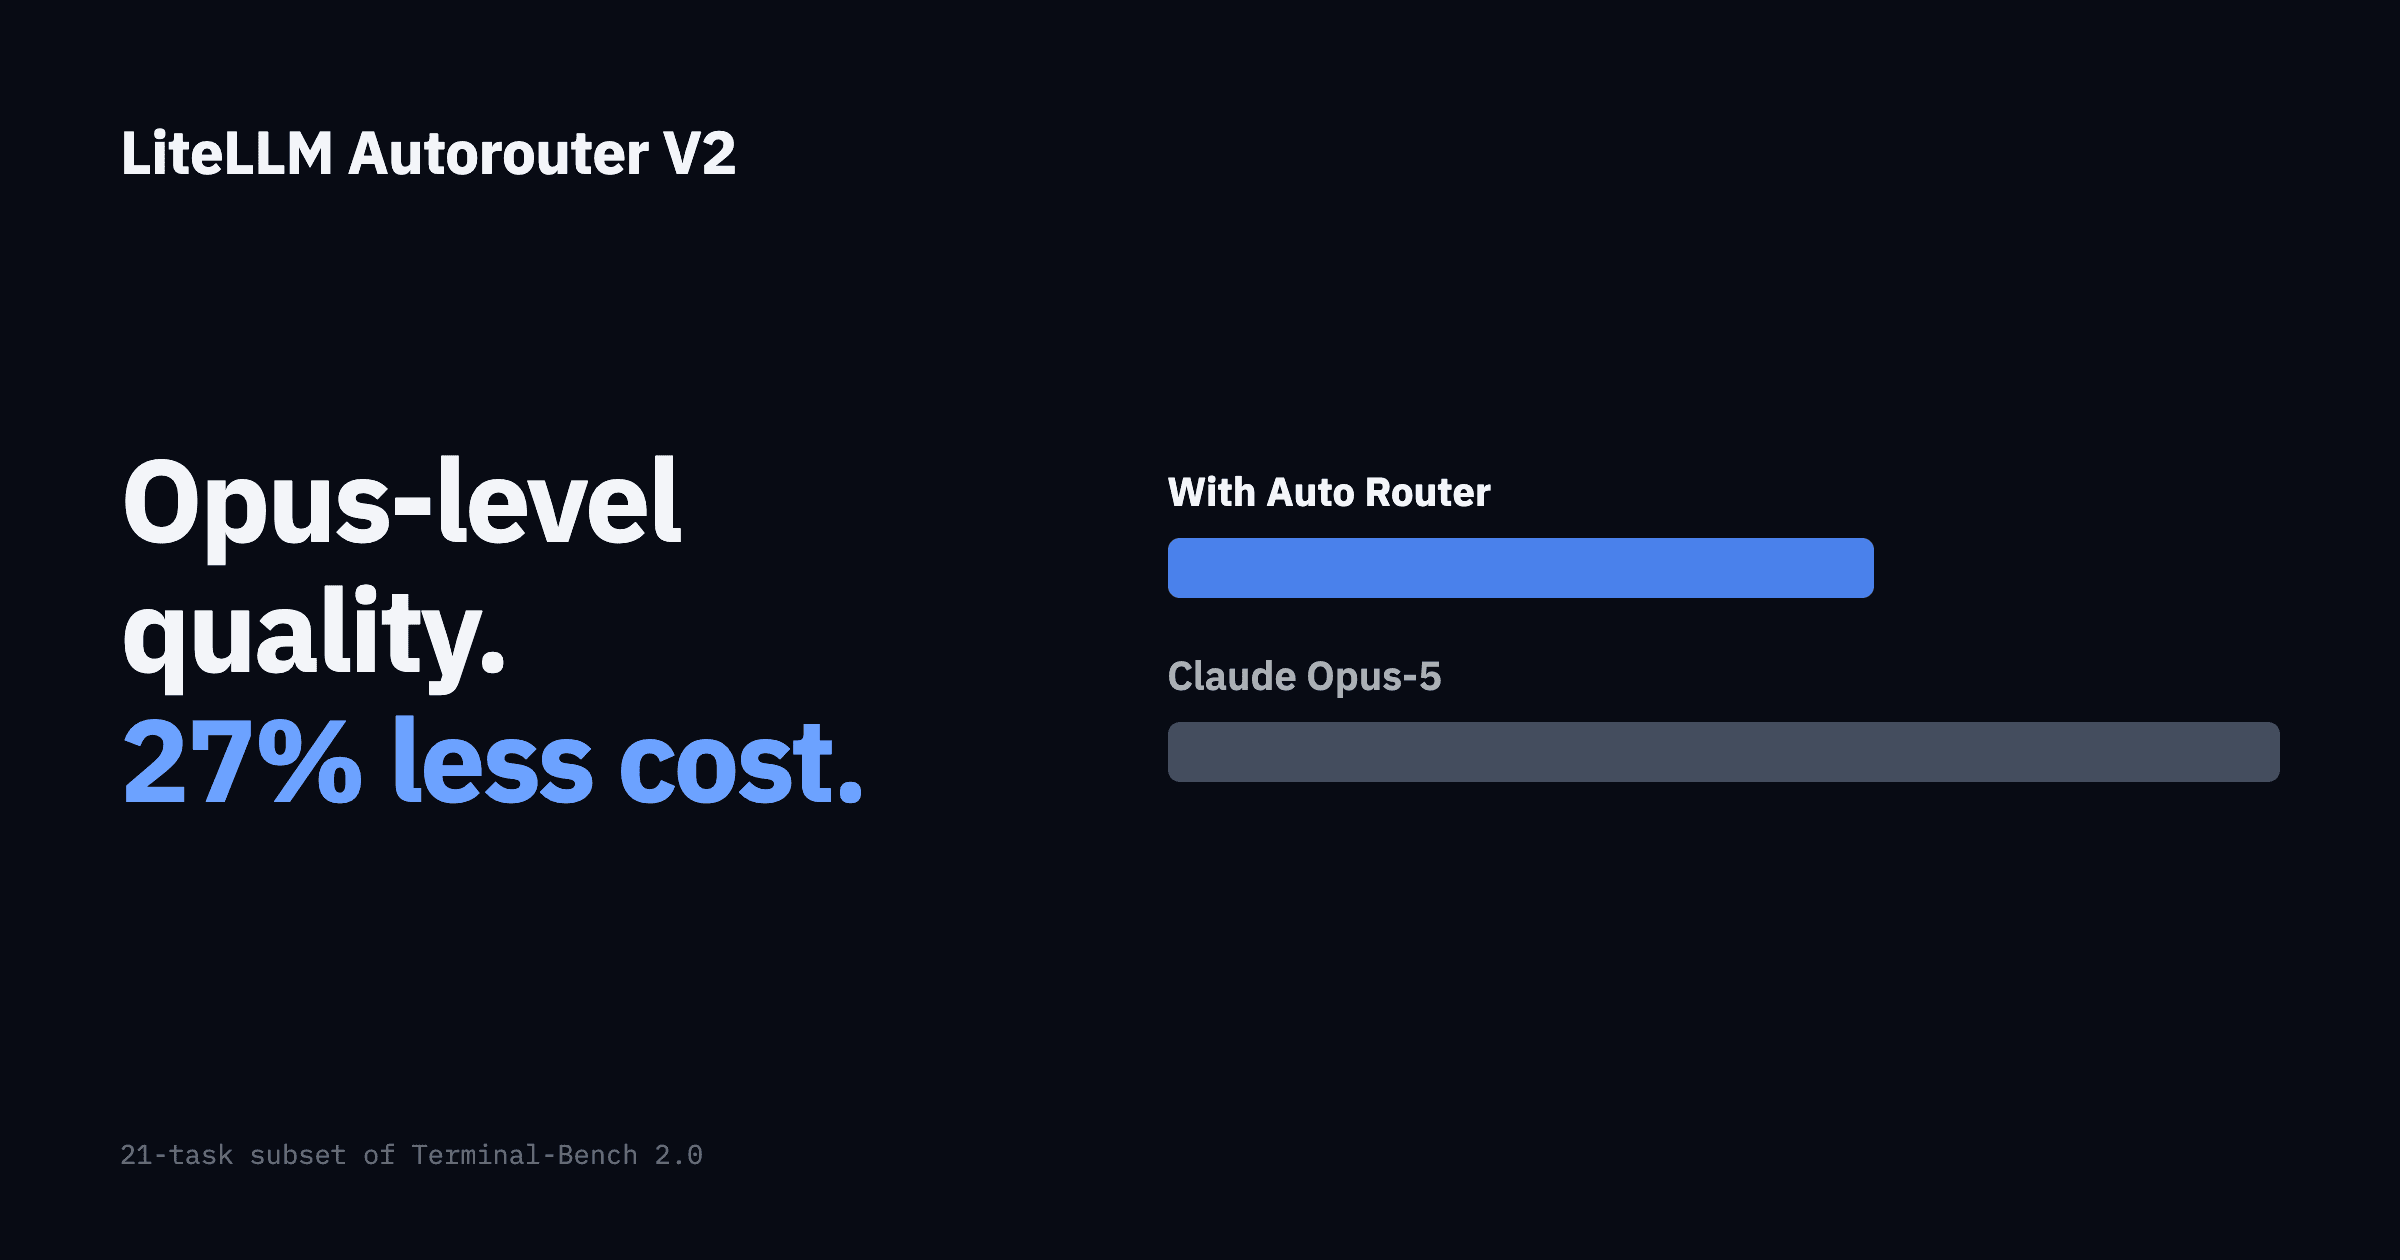
Auto Router: Opus level quality at up to 27% lower cost
On a 21 task subset of Terminal-Bench 2.0, an auto router matched Claude Opus-5 solve rate at 27% lower cost. Adding the last 3 user messages as classifier context raised relative quality 14% but cost 44% more; adding assistant replies made both worse.
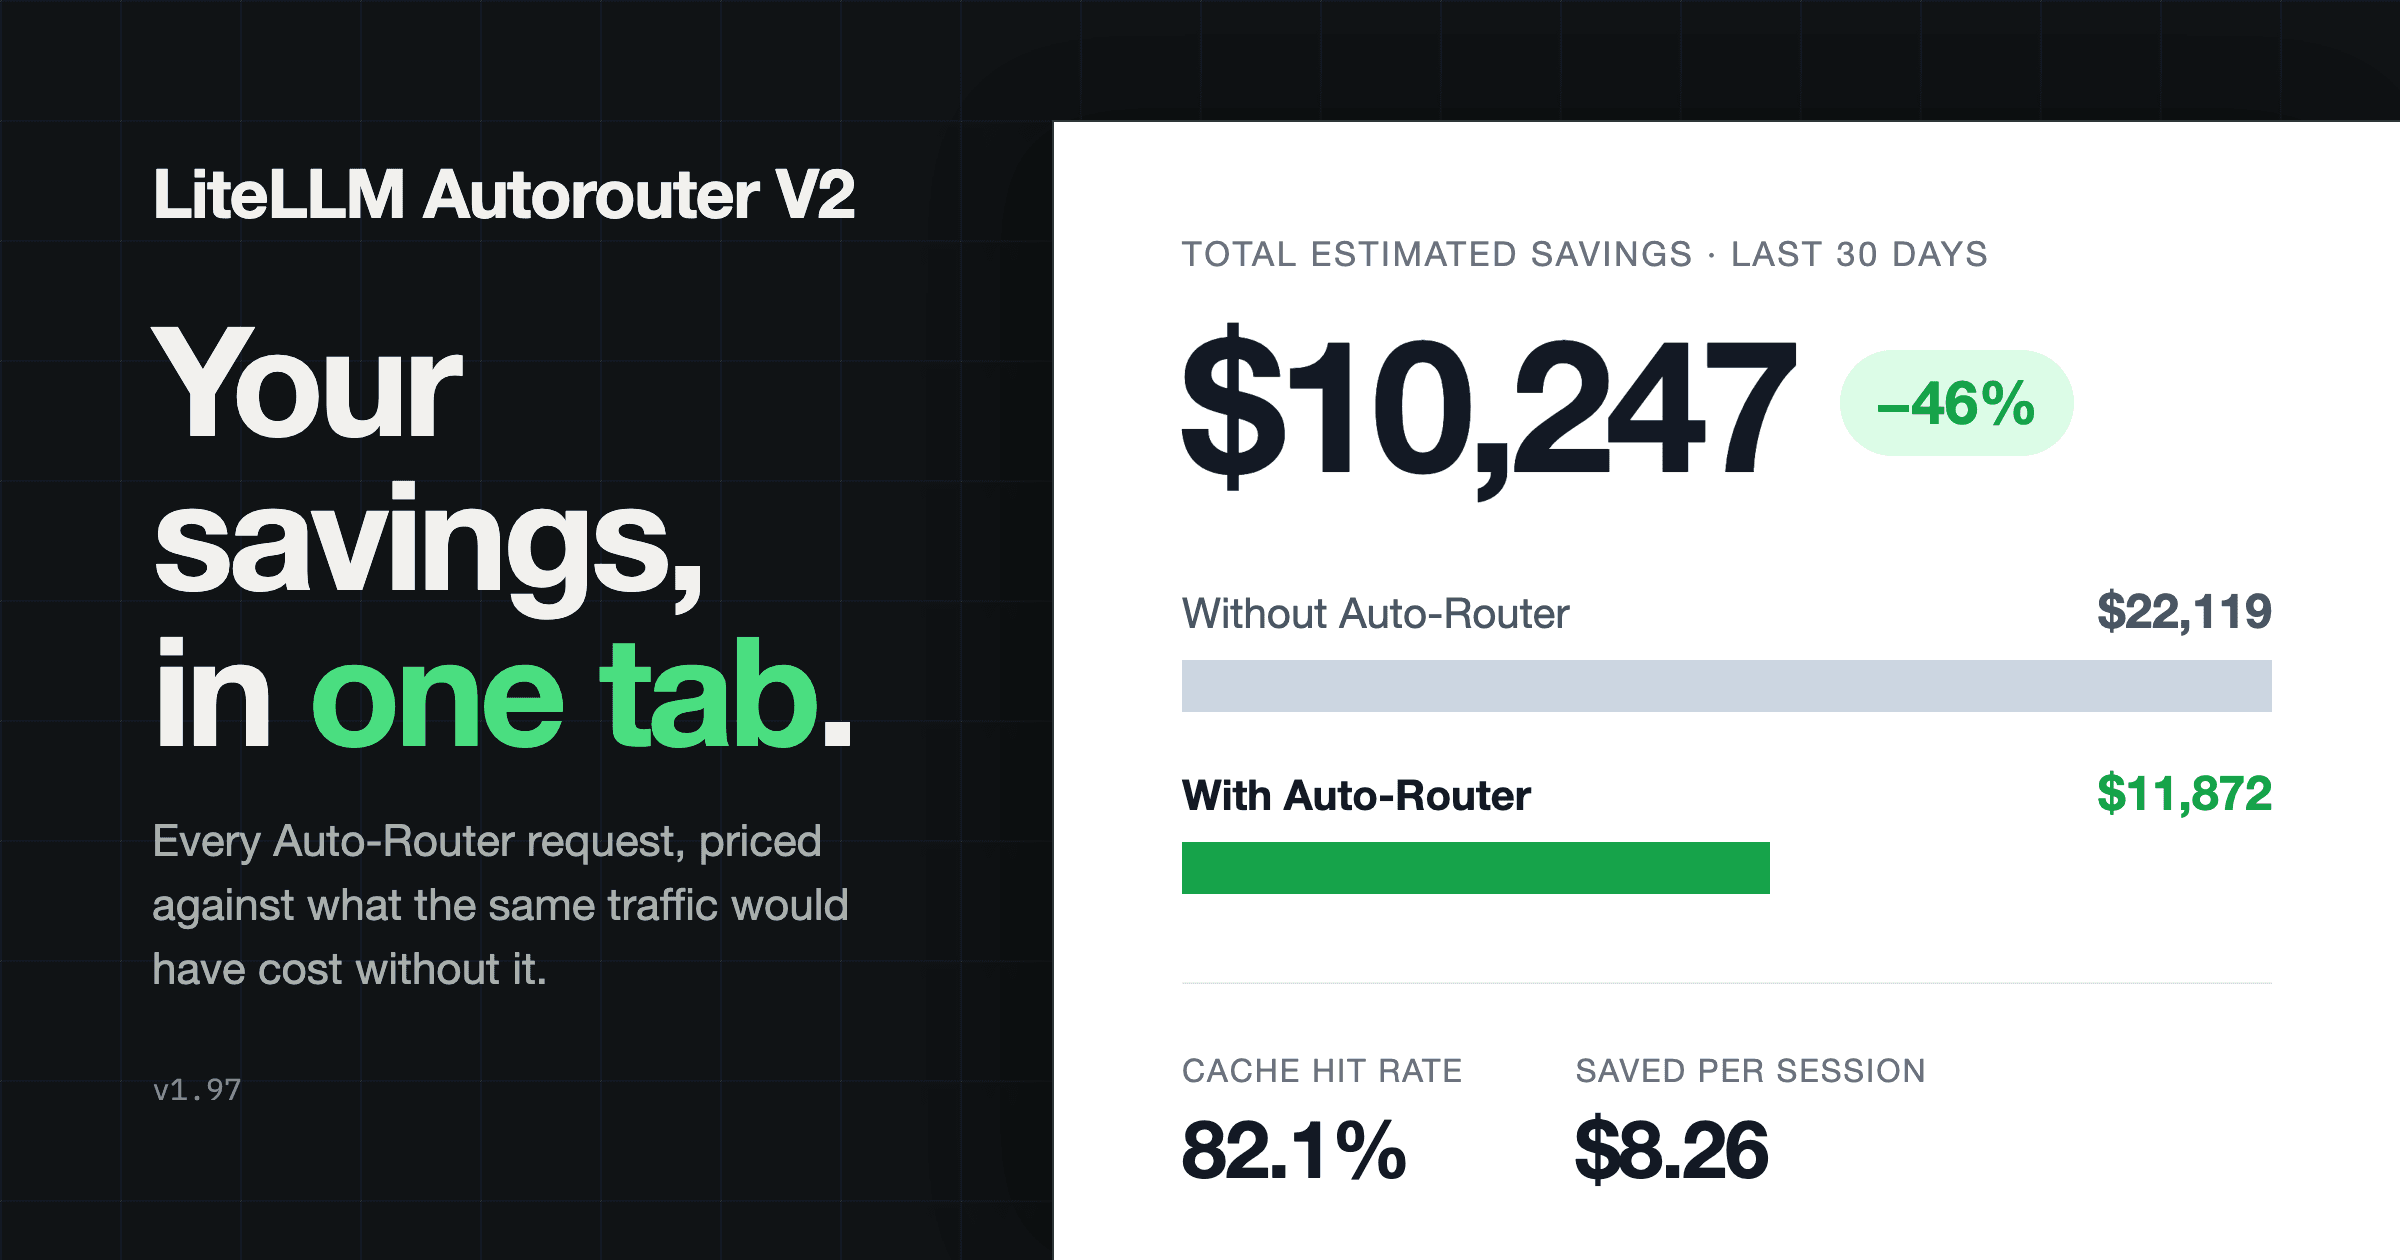
AutoRouter: Easy Visibility to Your Savings
A new Auto-Router Usage tab in Cost Optimization, per-request classifier cost reporting, preset matching against your own deployments, and two routing fixes.
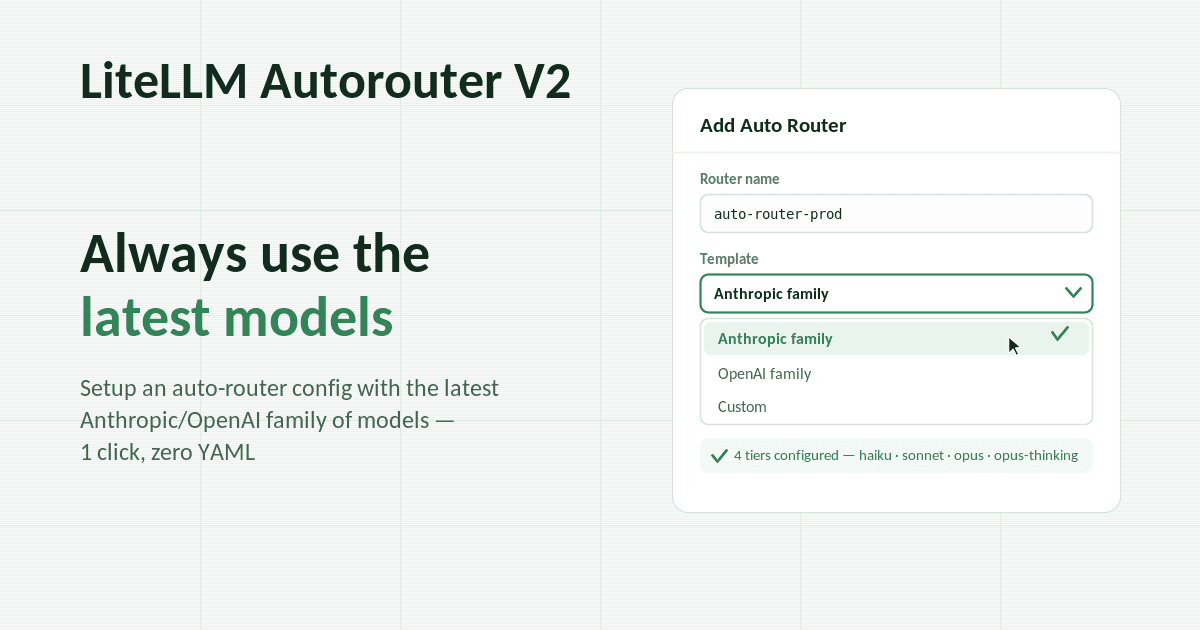
AutoRouter: 1 Click Deploy
Six changes to the Auto-Router: 1-click Anthropic and OpenAI presets, a one-line agent setup skill, Test Routing in the UI, a replaceable classifier prompt, customizable tiers, and configurable reminder markers.
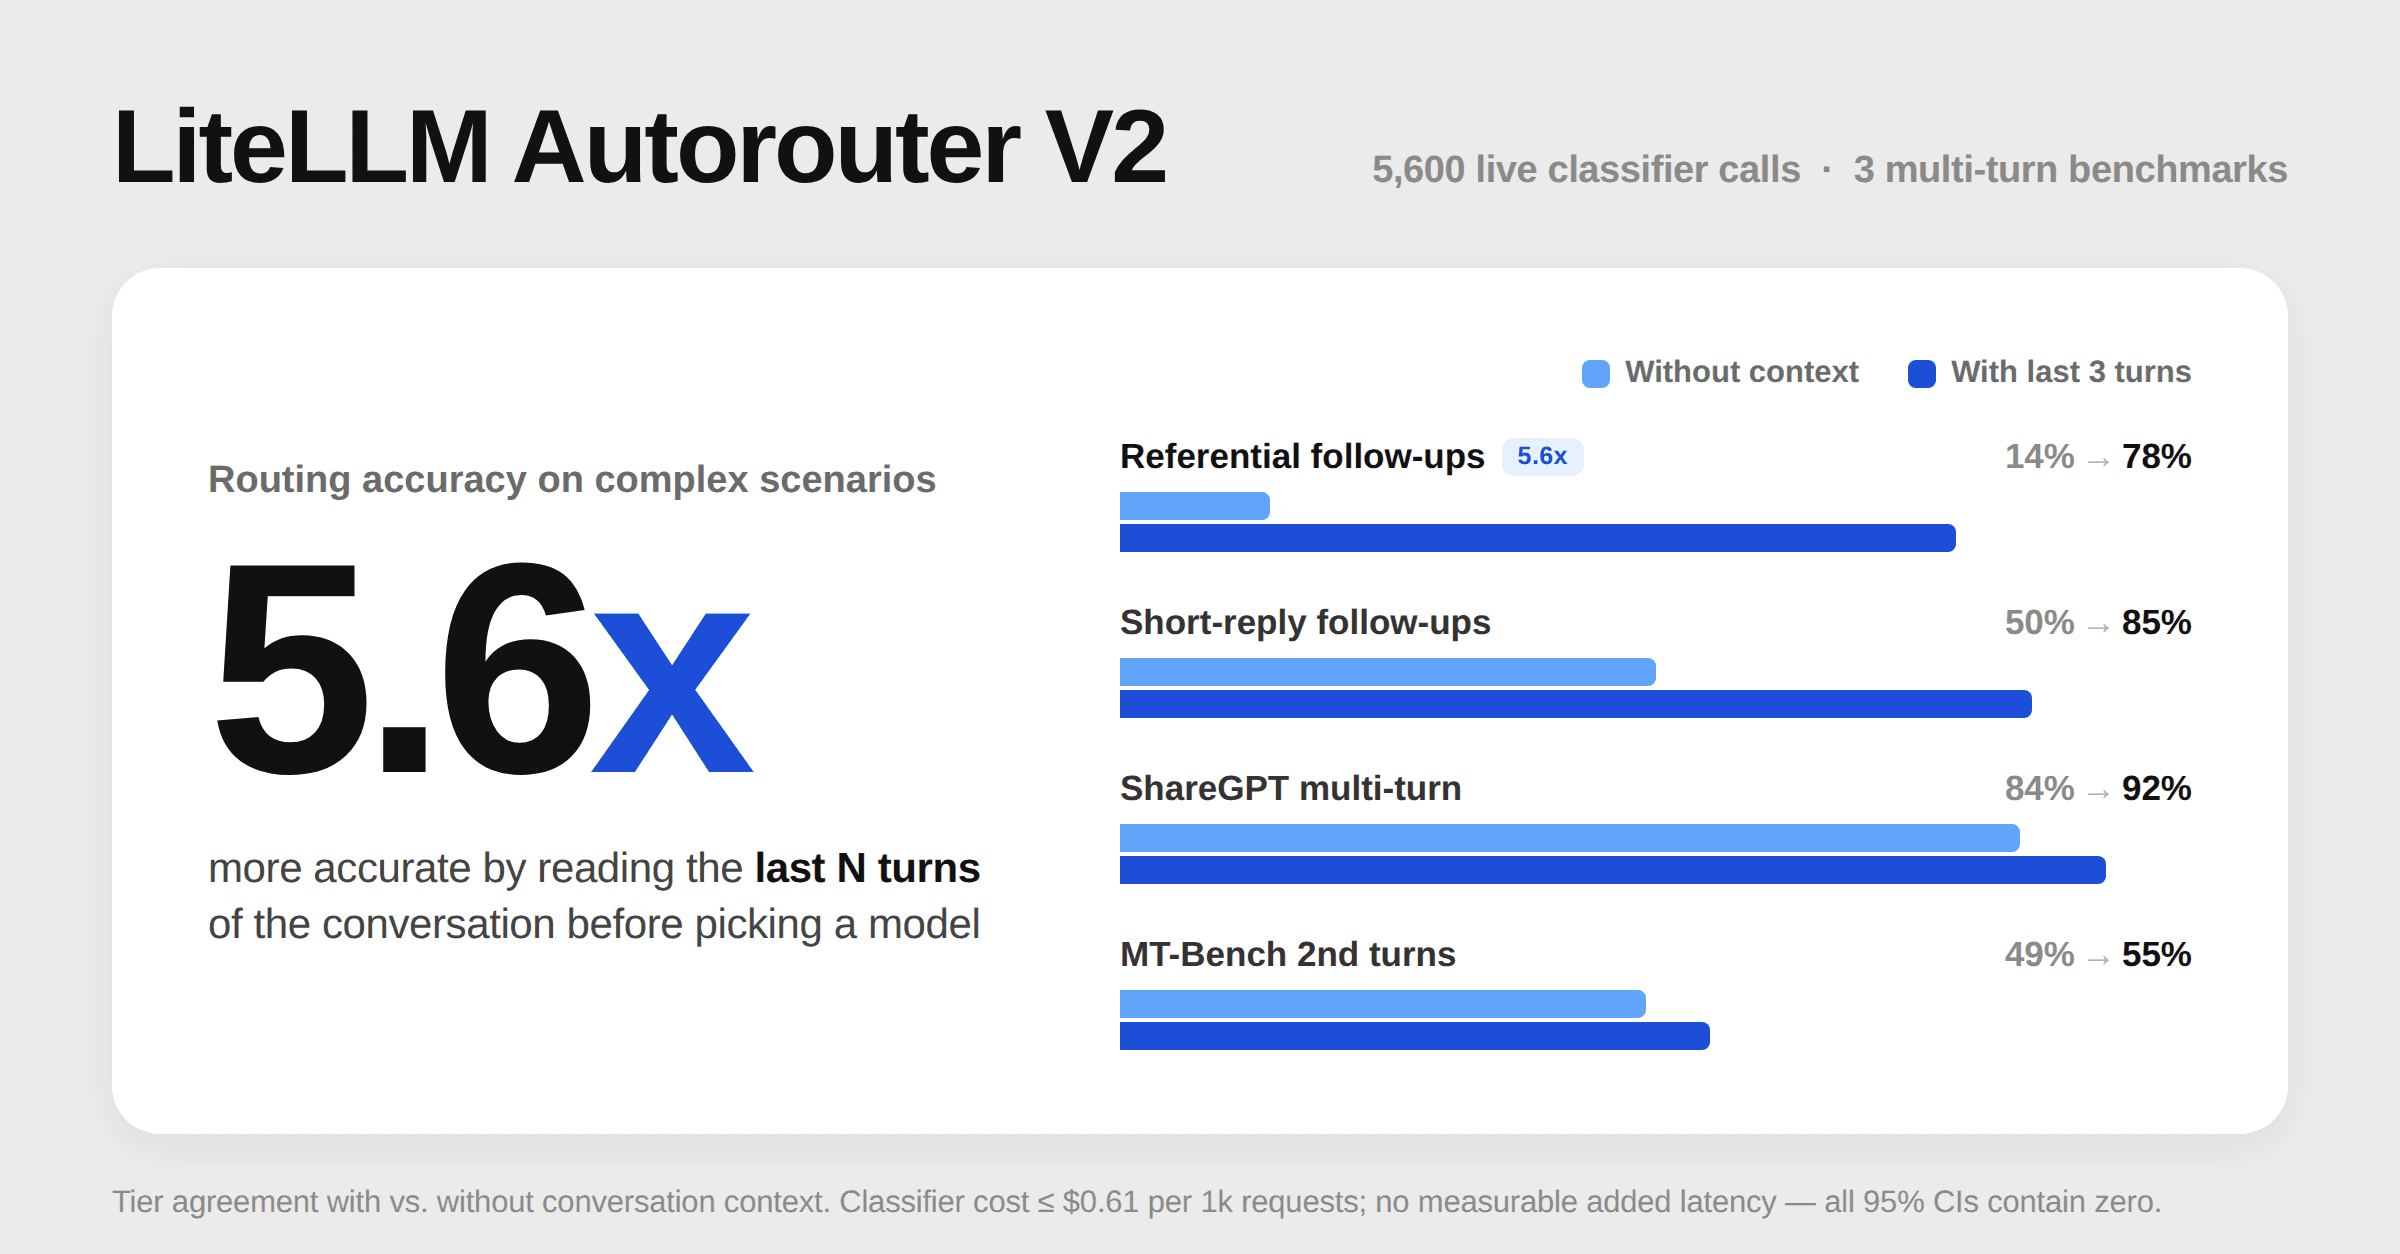
Auto Router v1.97: usage benchmarks and better quality for lower cost
v1.97 adds cost and usage benchmarks for the auto router, gives the LLM classifier a window of prior turns, and turns session affinity off by default. Across 5,600 live classifier calls, prior turns raised tier agreement on referential follow-ups from 14% to 78% at under a tenth of a cent per request, with no measurable latency change.
Prompt Caching Works with Auto Router
The most common objection to auto-routing is that switching models throws away your prompt cache. We measured it across five datasets, including real gateway traffic with the provider's own cache accounting, and the answer is no.
Cut 75% Claude Code cost with near frontier model quality
Two independent evaluations of a four-tier Auto Router config against an all-frontier baseline: 8,619 graded prompts, 14,000 simulated real conversations, and what the cost and quality numbers actually depend on.
July Townhall Updates: 38 Security Fixes, 317 Bug Fixes, and Autorouter V2
A recap of the July LiteLLM town hall: 38 security fixes, 317 bug fixes, 140 feature commits, new Rust gateway benchmarks, and the launch of Autorouter V2.
Day 0 Support: Claude Opus 5
Day 0 support for Claude Opus 5 on the LiteLLM AI Gateway. Use it across Anthropic, Azure, Vertex AI, and Bedrock.
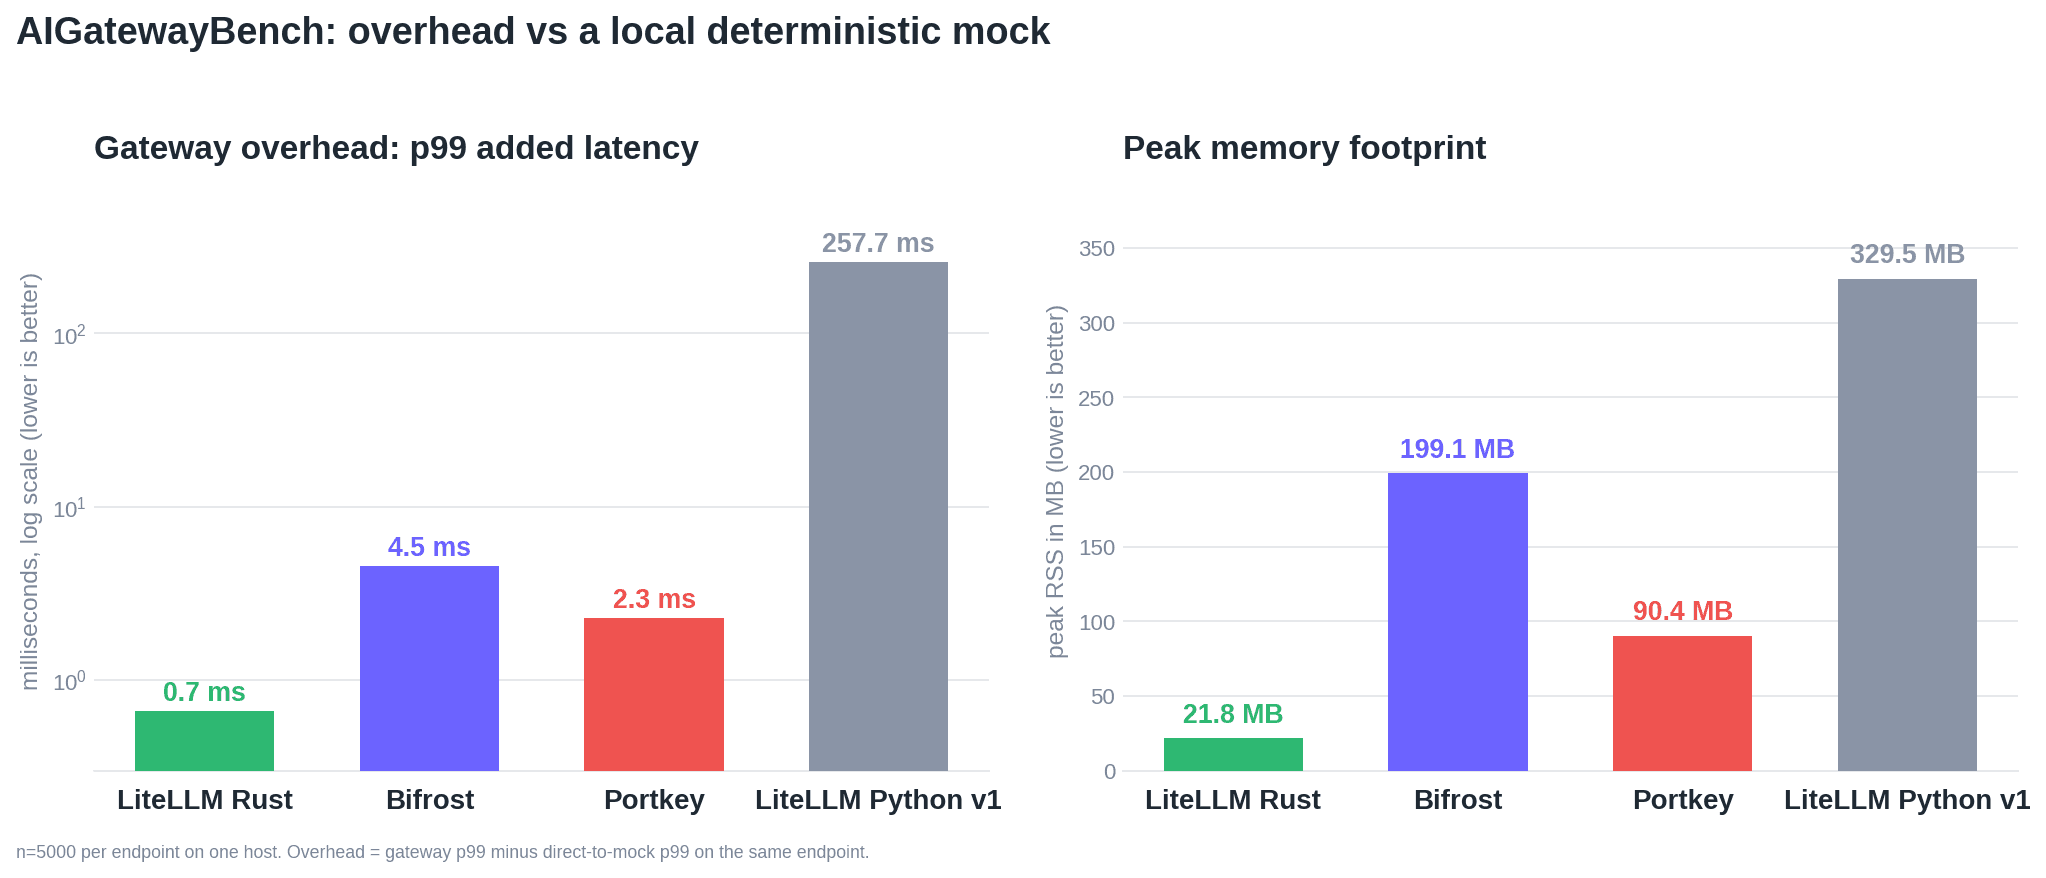
Benchmarking the LiteLLM Rust AI Gateway: Overhead, Memory, and Cost
AIGatewayBench measures the overhead an AI gateway adds on top of the upstream model, isolated against a deterministic mock, across LiteLLM (Rust), LiteLLM (Python v1), Portkey, and Bifrost. The LiteLLM Rust gateway has the lowest overhead and memory footprint of the four.
Announcing Router Plugins: Customize Routing Signals
Router plugins are now live on LiteLLM. Configure a plugin pipeline to determine which models to pick for a given input. Plugins can be chained as well
Auto Router v2: one router for complexity, semantic, and adaptive routing
Auto Router v2 folds LiteLLM's complexity, semantic, and adaptive routers into a single router with an LLM classifier, keyword tiers, multi-model pools, and adaptive Thompson sampling.
Incident Report: Prompt Cache Invalidation for Claude Code on Bedrock Invoke
Date: July 4 to July 10, 2026
July stability update: hardening MCP auth and cutting pass-through memory
A two-week product quality update. We addressed two major issues (MCP credential resolution and pass-through memory) and shipped 134 bug fixes in total. Plus our next goal: 95% end-to-end test coverage.
July Townhall: Product + Roadmap Updates
Join the LiteLLM July townhall on Thursday, 23 July at 7:30 AM PT to learn about LiteLLM's product updates and roadmap.
Day 0 Support: GPT-5.6 (Sol, Terra, Luna)
Day 0 support for the GPT-5.6 family (Sol, Terra, and Luna) on LiteLLM.
5 ways to cut Claude Code costs with LiteLLM
Practical levers a platform admin can pull on the LiteLLM proxy to reduce Claude Code spend without asking developers to change a thing.
Day 0 Support: Claude Sonnet 5
Day 0 support for Claude Sonnet 5 on the LiteLLM AI Gateway. Use it across Anthropic, Azure, Vertex AI, and Bedrock.
LiteLLM × Headroom: Use 60-95% fewer tokens with Claude Code
Cut input tokens on Claude Code and other LLM traffic by attaching Headroom as a pre_call guardrail on LiteLLM.
June Townhall Updates: 94 Bug Fixes, OCR + Realtime are in Rust, and a Zero-Regression Commitment
A recap of the June LiteLLM town hall covering security hardening, our zero-regression commitment, 78 feature commits, and the gradual migration of the gateway to Rust.
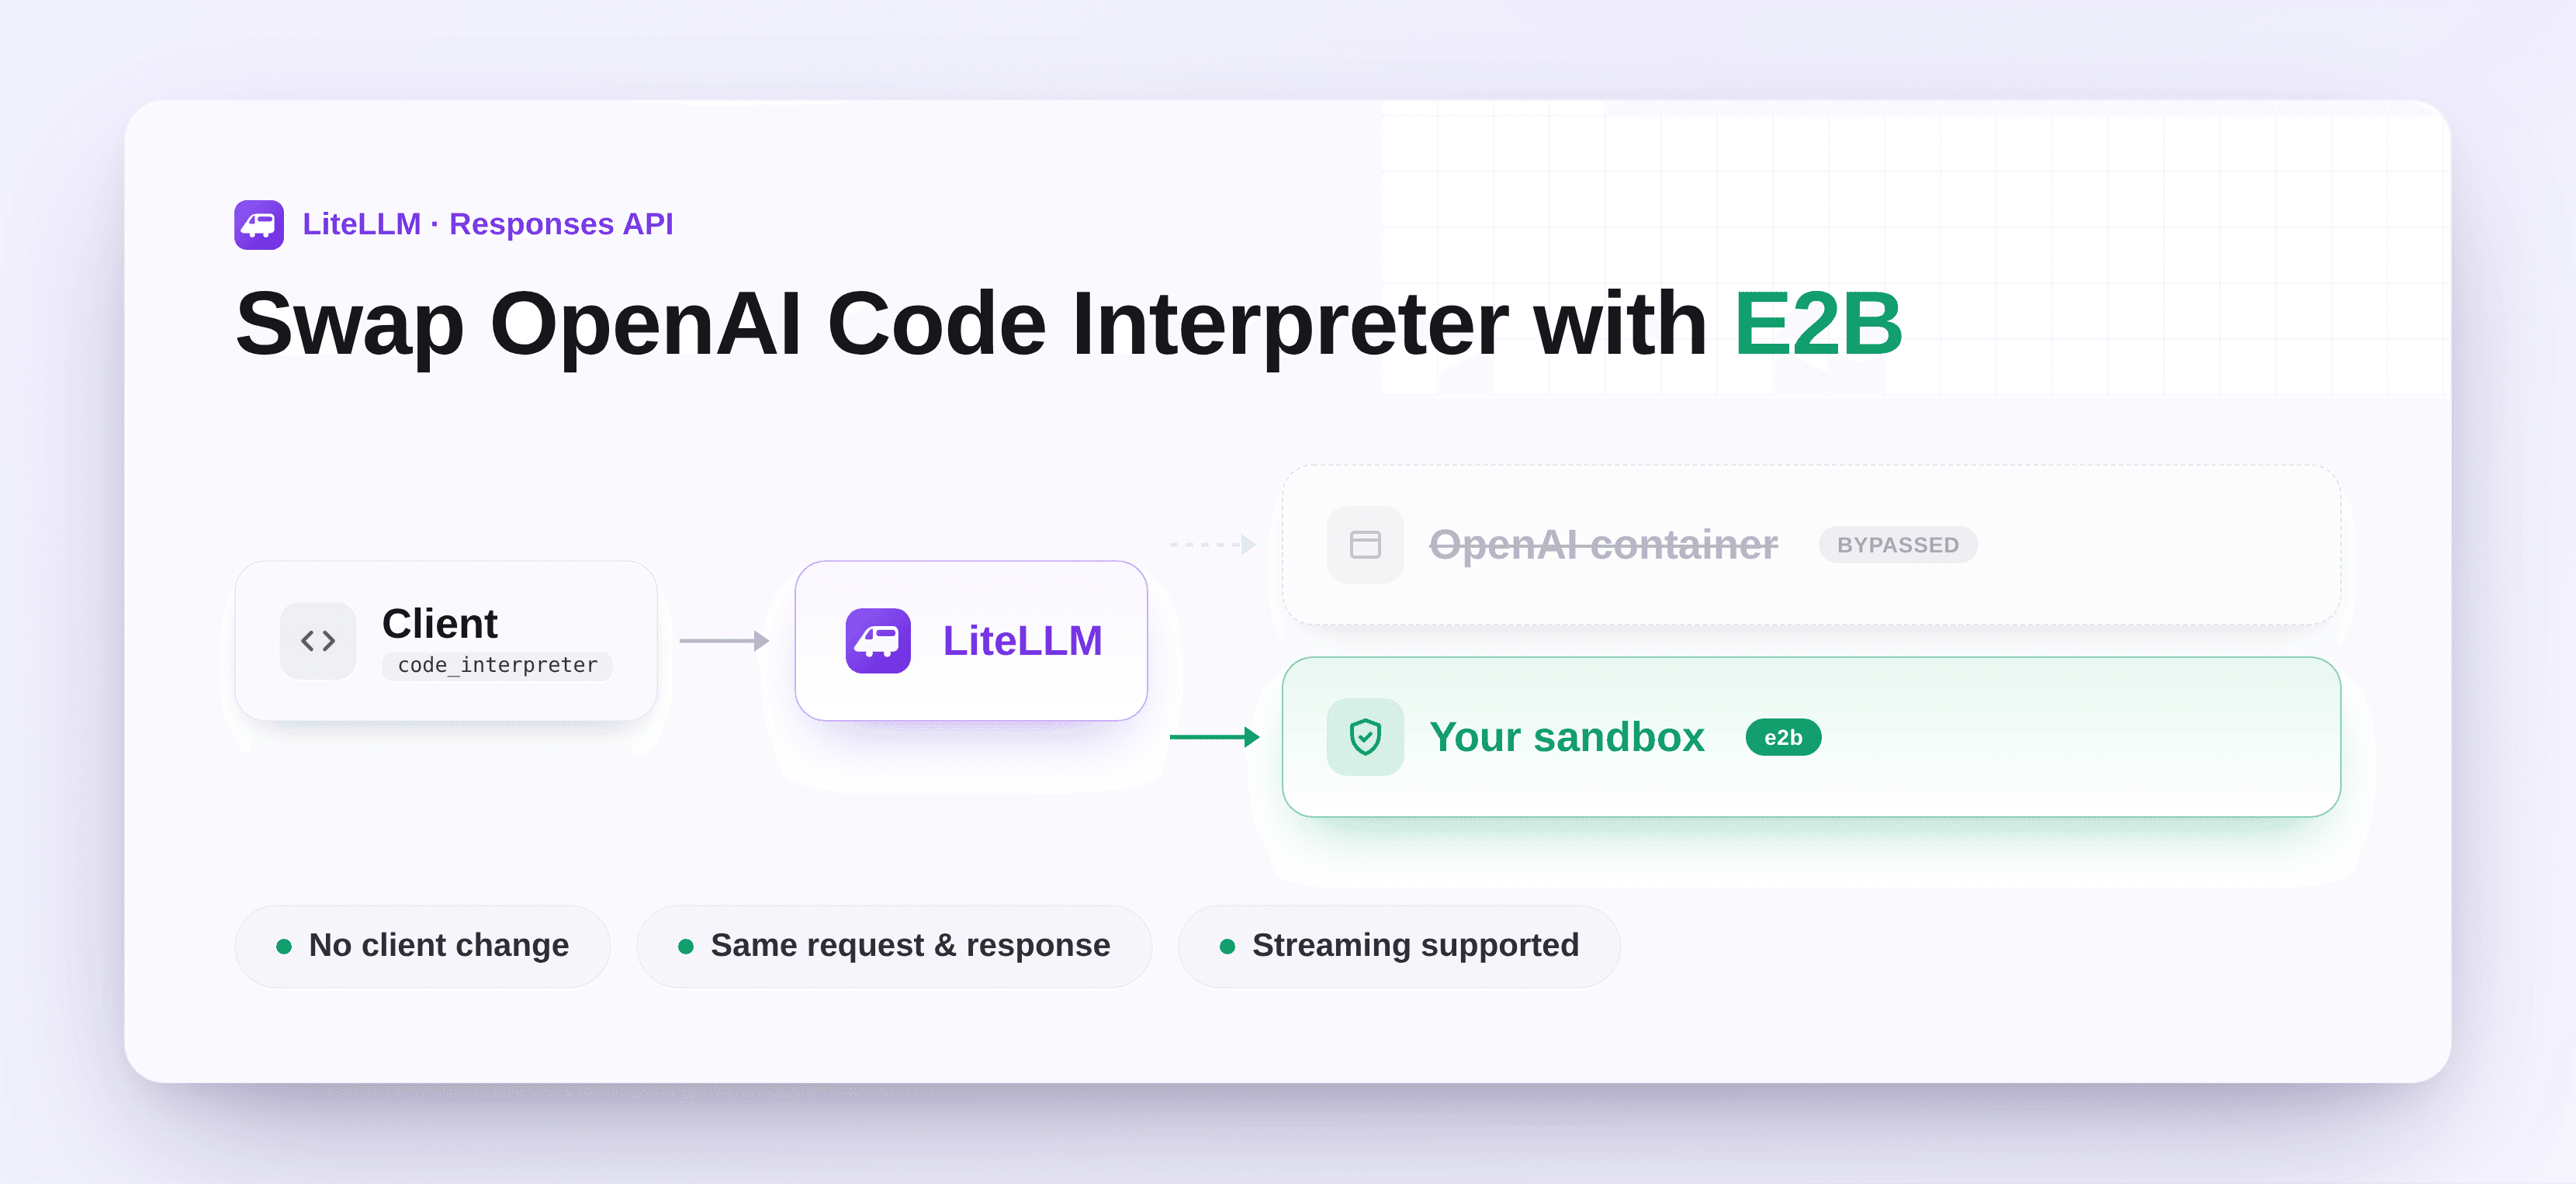
Swap OpenAI Code Interpreter for E2B/OpenSandbox
Keep the OpenAI code_interpreter tool in your requests, run the code in your own sandbox. LiteLLM intercepts the tool call and routes it to E2B or OpenSandbox; no client changes.
Migrating LiteLLM to Rust - Building the Fastest and Litest AI Gateway
LiteLLM is moving its AI gateway to Rust: 15x throughput, 11x less memory, and sub-1ms per-request overhead. No v2, no migration, your config stays the same.
LiteLLM version support: focusing on the four most recent stable lines
Starting Monday, June 29, 2026, LiteLLM actively supports the four most recent stable minor lines. Older lines reach end of life, and the window rolls forward as new stable lines ship.
Semantic Caching on Valkey and AWS ElastiCache
LiteLLM now supports semantic prompt caching on Valkey clusters running the valkey-search module, including AWS ElastiCache for Valkey, with no RediSearch, Redis Stack, or Qdrant required.
June Townhall: Product + Roadmap Updates
Join the LiteLLM June townhall on Thursday, 25 June at 7:30 AM PST to learn about LiteLLM's product updates and roadmap.
June Stability Update: We're Making Stability a First-Class Citizen at LiteLLM
Day 0 Support: Claude Fable 5
Day 0 support for Claude Fable 5 on the LiteLLM AI Gateway. Use it across Anthropic, Azure, Vertex AI, and Bedrock.
A Unified Agent Control Plane
The AI Gateway is moving up the stack: from routing model calls to routing agent work.
Announcing LiteLLM x Microsoft ASSERT
LiteLLM now integrates with Microsoft ASSERT for policy-driven agent evaluation — catch safety and quality defects before they reach production.
LiteLLM Labs: Announcing Lite-Harness SDK — Unified API for Claude Code, Codex, and Pi AI
One SDK. Swap between Claude Code, Codex, and Pi AI by changing a string. Pairs with the LiteLLM AI Gateway for keys, budgets, logs, and fallbacks.
Fixed in 1.84.0+ - Version Update: Authentication Bypass via Host Header Injection (GHSA-4xpc-pv4p-pm3w)
Disclosure of a Host-header authentication bypass in the LiteLLM proxy. Addressed in v1.84.0. Very limited deployments are potentially affected, and no LiteLLM Cloud customers were affected.
Day 0 Support: Claude Opus 4.8
Day 0 support for Claude Opus 4.8 on the LiteLLM AI Gateway. Use it across Anthropic, Azure, Vertex AI, and Bedrock.
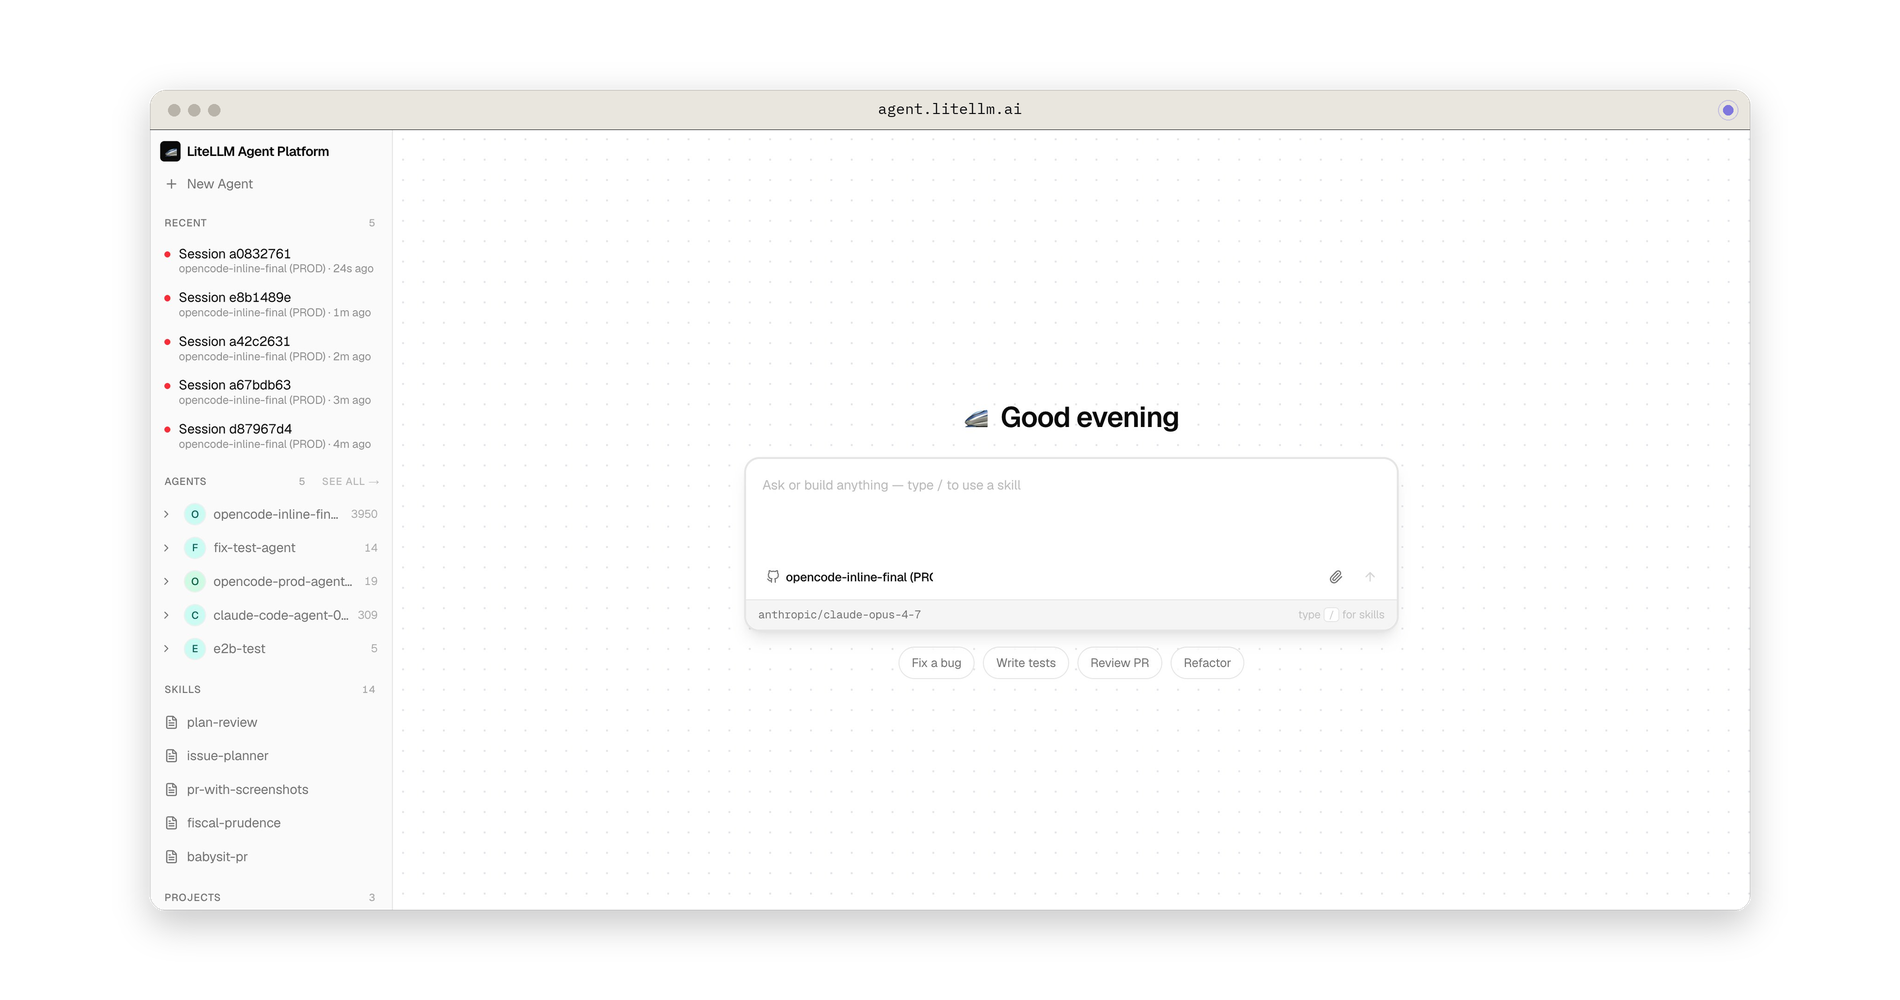
How we built a background agent to cover 30% of our backlog
How we built a background agent on the LiteLLM AI Gateway that merges PRs with no human in the loop (the infra, harness, and credential-scoping calls behind it).
May Townhall Updates: Security Hardening, Release Versioning, and the Agent Platform
A recap of the May LiteLLM town hall covering 89 security fixes, new release versioning, MCP toolsets, performance wins, and the LiteLLM Agent Platform.
DAY 0 Support: Gemini 3.5 Flash on LiteLLM
Guide to using Gemini 3.5 Flash on LiteLLM Proxy and SDK with day 0 support.
Google AI Studio Managed Agents on LiteLLM
LiteLLM now supports the Google AI Studio Managed Agents API. Create, manage, and run custom agents through LiteLLM.
May Townhall: Product + Roadmap Updates
Join the LiteLLM May townhall on Tuesday, 19 May at 7:30 AM PST to learn about LiteLLM's product updates and roadmap.
Announcing Componentized Deployments
How LiteLLM's componentized deployment isolates the management/UI control plane from the LLM data plane, improving reliability at scale.
Security Update: Mistral AI PyPI Supply Chain Attack — LiteLLM Not Impacted
On May 11, 2026, a malicious version of the mistralai PyPI package was published as part of a coordinated supply chain attack. LiteLLM is not affected — we call Mistral exclusively via httpx, never by importing the mistralai SDK.
LiteLLM Managed Agents Platform — Alpha Now Open for Public Preview
Spawn sandboxed agent sessions on the LiteLLM Gateway — a control plane for managed agents, now in public preview.
Security Update: CVE-2026-42208 in LiteLLM Proxy
CVE-2026-42208 (SQL injection in LiteLLM Proxy's API key verification path) is fixed. Upgrade to v1.83.10-stable.
Incident Report: Prisma DB Reconnect Blocks the Event Loop and Kills Liveliness
Date: April 2026
LiteLLM release versioning is changing: standard names, MINOR for weekly, PATCH for hotfixes
Dropping `-stable` and `-nightly` suffixes. Weekly releases bump MINOR; PATCH is now reserved for actual hotfixes. Old releases keep their tags forever; new ones start with `1.84.0`.
Gemini Embedding 2 (GA): Multimodal Embeddings on LiteLLM
Use generally available gemini-embedding-2 for multimodal embeddings on LiteLLM via Gemini API and Vertex AI—the same flows as preview, stable model id.
Day 0 Support: GPT-5.5 and GPT-5.5 Pro
Day 0 support for GPT-5.5 and GPT-5.5 Pro on LiteLLM.
Security Update: CVE-2026-30623 — Command Injection via Anthropic's MCP SDK
CVE-2026-30623 (authenticated RCE via MCP stdio transport) is fixed. Upgrade to v1.83.6-nightly or v1.83.7-stable or later.
LiteLLM × Akto: Model-Based Detection Alongside Built-in Guardrails
Chain Akto's model-based detection with LiteLLM's built-in guardrails — catch PII, prompt injection, and policy violations that pattern-based checks miss.
Day 0 Support: Claude Opus 4.7
Day 0 support for Claude Opus 4.7 on LiteLLM AI Gateway - use across Anthropic, Azure, Vertex AI, and Bedrock.
Making the AI Gateway Resilient to Redis Failures
How LiteLLM's production AI Gateway handles Redis degradation at scale without cascading failures — circuit breaker pattern, 0ms fast-fail, automatic recovery.
April Townhall Updates: CI/CD v2, Stability, and Product Roadmap
A recap of the April LiteLLM town hall covering CI/CD v2, product stability work, and the near-term roadmap.
Security Update: Vulnerability Disclosures and Ongoing Hardening
Disclosure of security vulnerabilities fixed in LiteLLM v1.83.0, and the launch of our bug bounty program.
April Townhall: Security + Product Roadmap
Join the LiteLLM April townhall on Friday, 10 April at 7:30 AM to learn about LiteLLM's security and product roadmap.
Announcing CI/CD v2 for LiteLLM
CI/CD v2 introduces isolated environments, stronger security gates, and safer release separation for LiteLLM.
LiteLLM + Vanta: SOC 2 Type 2 and ISO 27001 Recertification
LiteLLM is partnering with Vanta on SOC 2 Type 2 and ISO 27001 recertification and engaging independent auditors for verification.
Security Townhall Updates
What happened, what we've done, and what comes next for LiteLLM's release and security processes.
Security Update: Suspected Supply Chain Incident
As of 2:00 PM ET on March 24, 2026
Incident Report: Guardrail logging exposed secret headers in spend logs and traces
Date: March 18, 2026
Day 0 Support: GPT-5.4-mini and GPT-5.4-nano
GPT-5.4-mini and GPT-5.4-nano model support in LiteLLM
New Video Characters, Edit and Extension API support
LiteLLM now supports creating, retrieving, and managing reusable video characters across multiple video generations.
Realtime WebRTC HTTP Endpoints
Use the LiteLLM proxy to route OpenAI-style WebRTC realtime via HTTP: client_secrets and SDP exchange.
Day 0 Support: GPT-5.4
GPT-5.4 model support in LiteLLM
DAY 0 Support: Gemini 3.1 Flash Lite Preview on LiteLLM
Guide to using Gemini 3.1 Flash Lite Preview on LiteLLM Proxy and SDK with day 0 support.
Incident Report: Cache Eviction Closes In-Use httpx Clients
Date: February 27, 2026
Day 0 Support: GPT-5.3-Codex
Day 0 support for GPT-5.3-Codex on LiteLLM, including phase parameter handling for Responses API.
Incident Report: Encrypted Content Failures in Multi-Region Responses API Load Balancing
Date: Feb 24, 2026
Incident Report: Wildcard Blocking New Models After Cost Map Reload
Date: Feb 23, 2026
Incident Report: SERVER_ROOT_PATH regression broke UI routing
Date: January 22, 2026
DAY 0 Support: Gemini 3.1 Pro on LiteLLM
Guide to using Gemini 3.1 Pro on LiteLLM Proxy and SDK with day 0 support.
Incident Report: vLLM Embeddings Broken by encoding_format Parameter
Date: Feb 16, 2026
Day 0 Support: Claude Sonnet 4.6
Day 0 support for Claude Sonnet 4.6 on LiteLLM AI Gateway - use across Anthropic, Azure, Vertex AI, and Bedrock.
Incident Report: Invalid beta headers with Claude Code
Date: February 13, 2026
Day 0 Support: MiniMax-M2.5
Day 0 support for MiniMax-M2.5 on LiteLLM
Incident Report: Invalid model cost map on main
Date: January 27, 2026
Your Middleware Could Be a Bottleneck
How we improved LiteLLM proxy latency and throughput by replacing a single middleware base class
Improve release stability with 24 hour load tests
How we built a long-running, release-validation system to catch regressions before they reach users.
Day 0 Support: Claude Opus 4.6
Day 0 support for Claude Opus 4.6 on LiteLLM AI Gateway - use across Anthropic, Azure, Vertex AI, and Bedrock.
Achieving Sub-Millisecond Proxy Overhead
Our Q1 performance target and architectural direction for achieving sub-millisecond proxy overhead on modest hardware.
DAY 0 Support: Gemini 3 Flash on LiteLLM
Guide to using Gemini 3 Flash on LiteLLM Proxy and SDK with day 0 support.
Day 0 Support: Claude 4.5 Opus (+Advanced Features)
Guide to Claude Opus 4.5 and advanced features in LiteLLM: Tool Search, Programmatic Tool Calling, and Effort Parameter.
DAY 0 Support: Gemini 3 on LiteLLM
Common questions and best practices for using gemini-3-pro-preview with LiteLLM Proxy and SDK.
Gemini Embedding 2 Preview: Multimodal Embeddings on LiteLLM
Generate embeddings from text, images, audio, video, and PDFs with gemini-embedding-2-preview on LiteLLM via Gemini API (one vector per input, OpenAI-compatible) and Vertex AI (single unified vector per request).