
2 posts tagged with "vllm"

View All Tags

Cache-Aware Routing for Self-Hosted Models
Yassin Kortam
Senior SWE @ LiteLLM

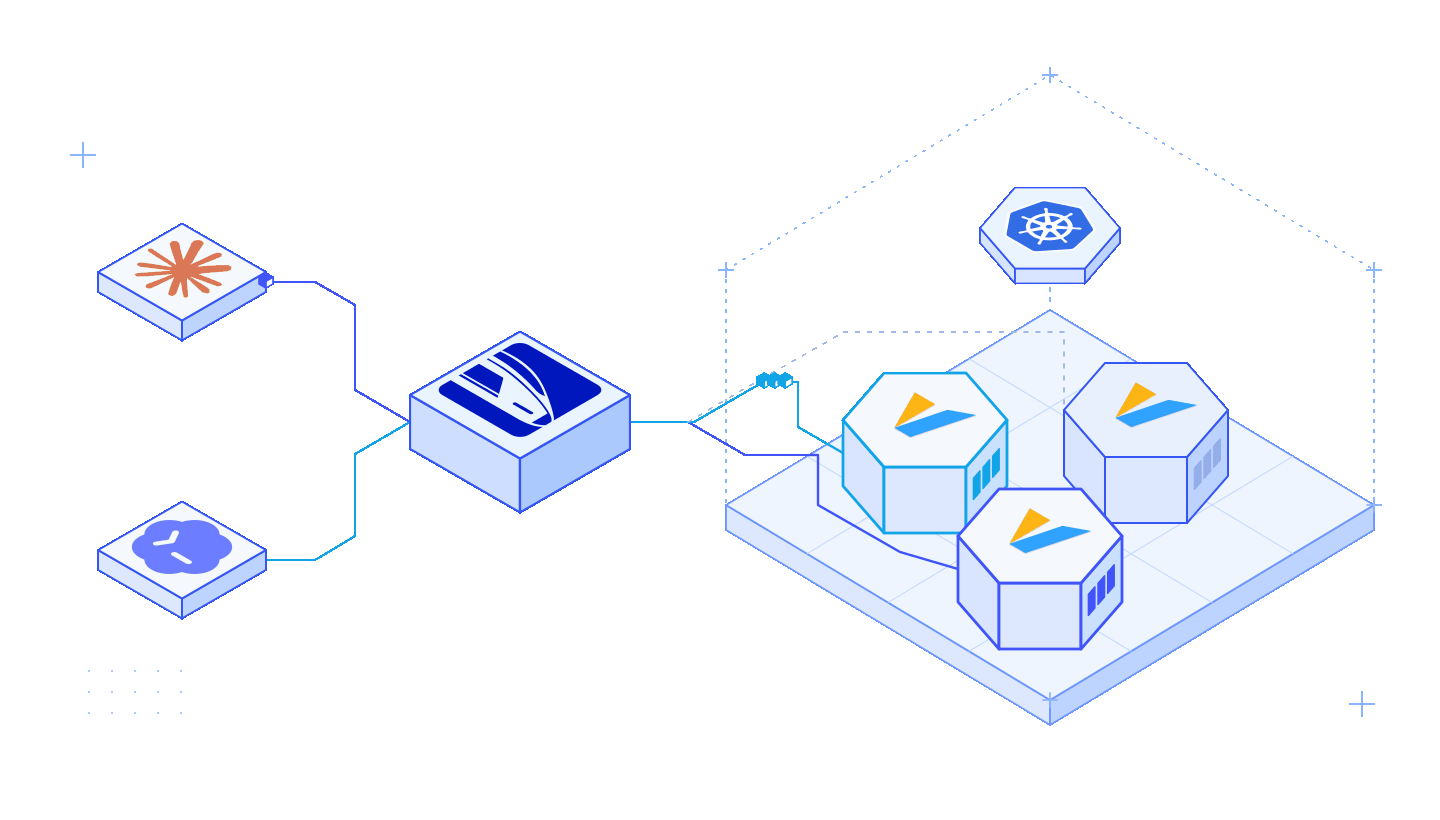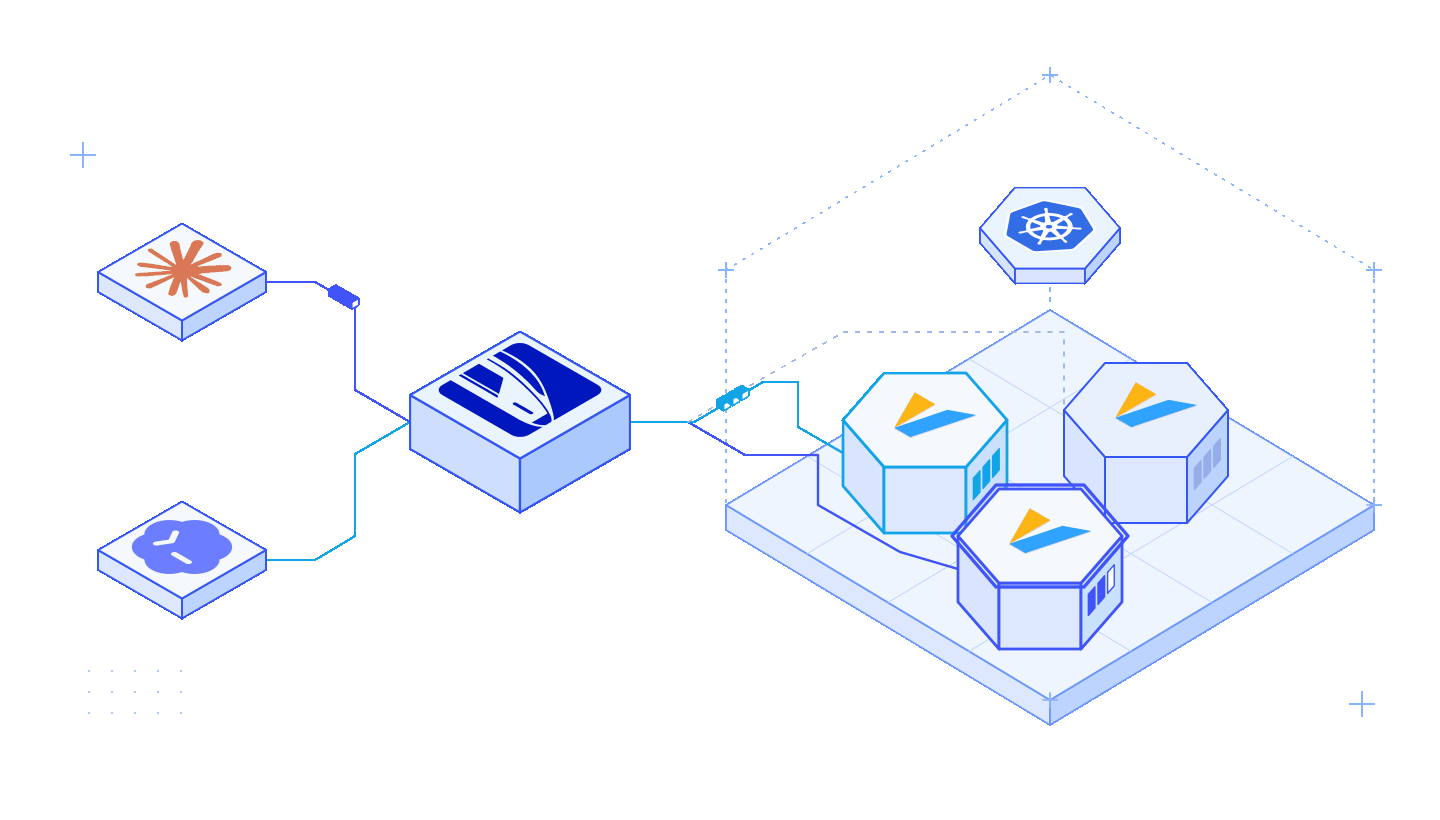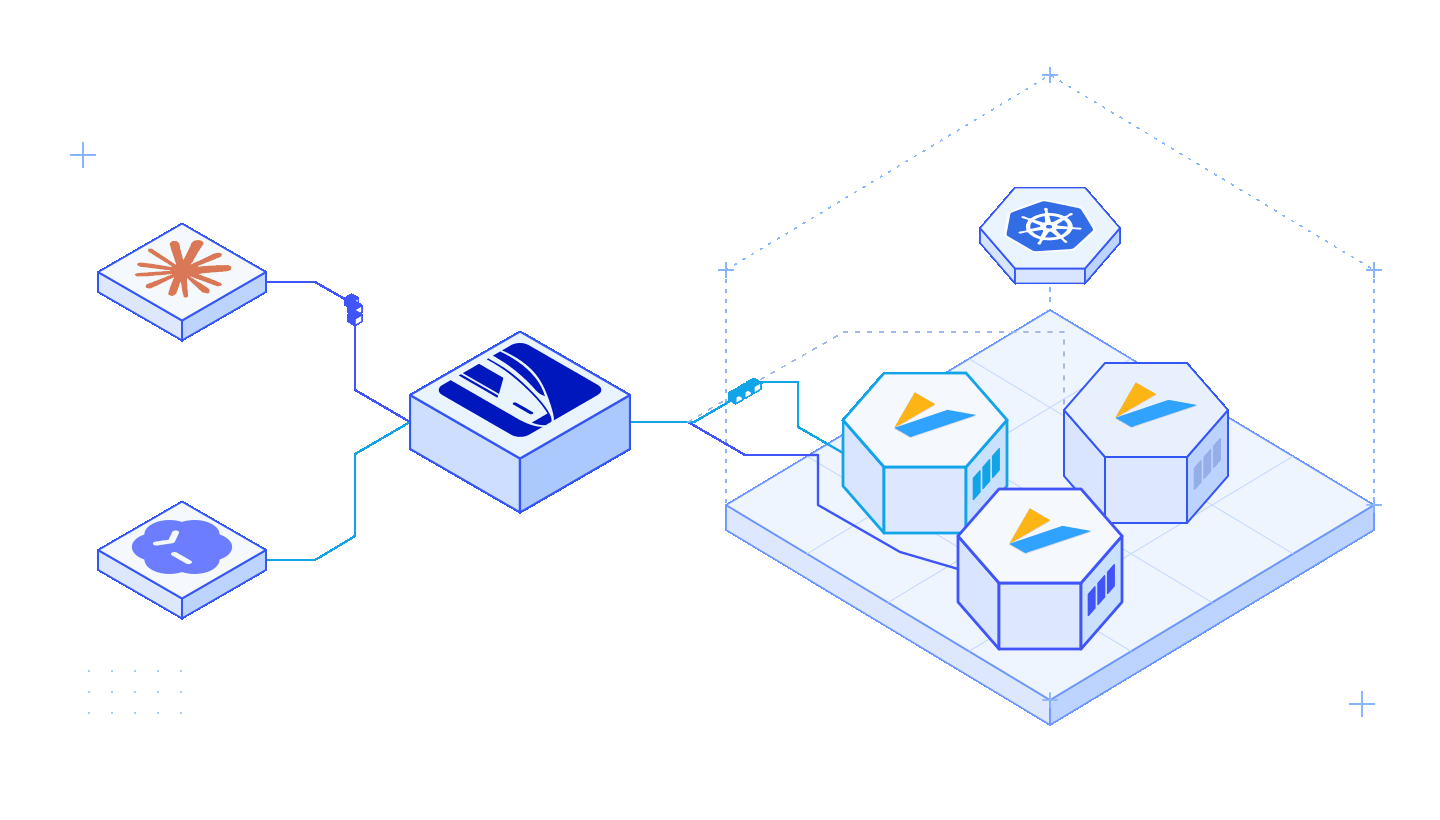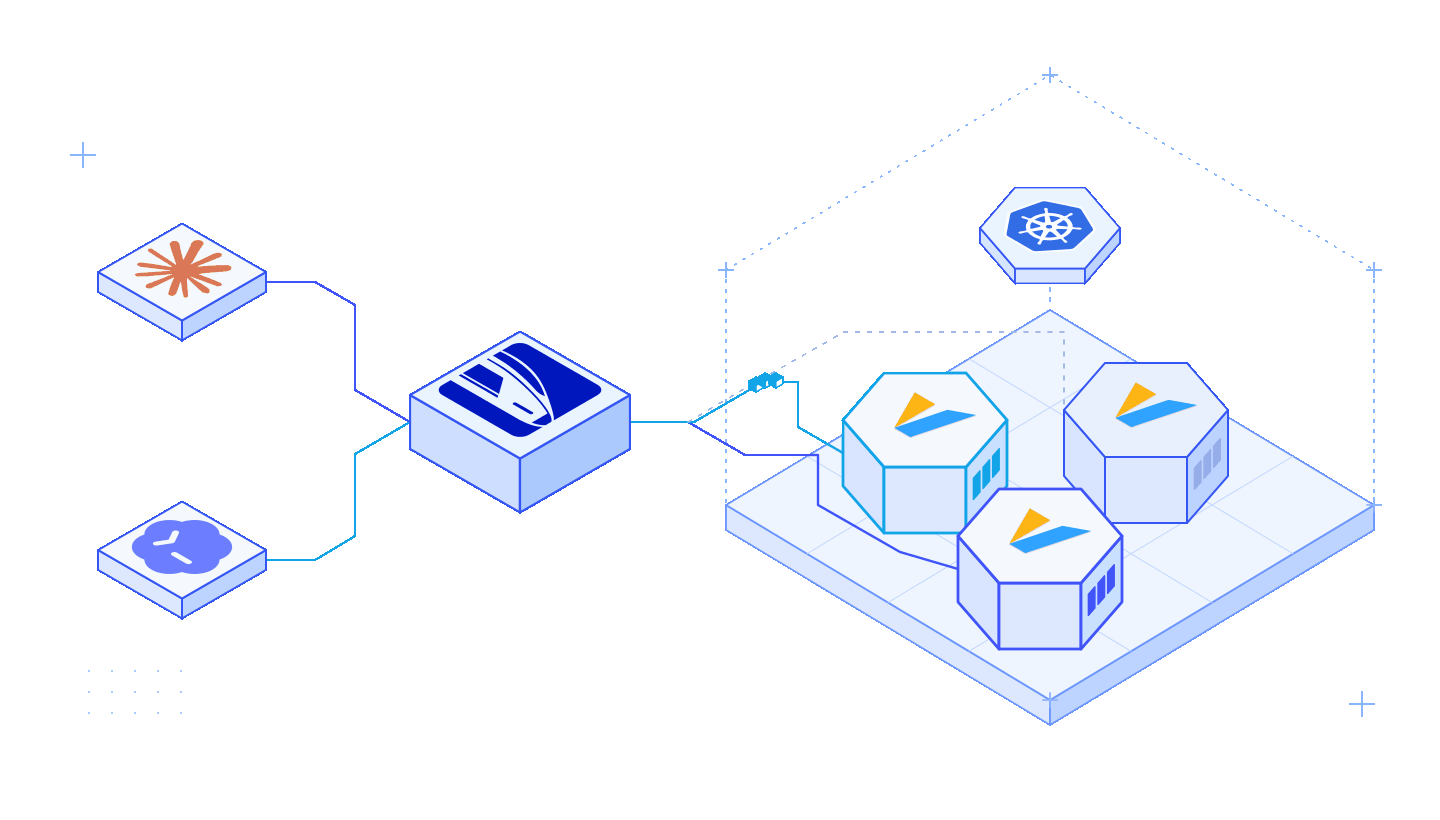
Claude Code and Codex requests pass through the LiteLLM gateway and return to the same vLLM pod for each session, allowing cached prompt prefixes to be reused.

LiteLLM now supports cache-aware routing for self-hosted inference on Kubernetes. Within a deployment, requests from the same session go to the same GPU pod. This lets vLLM reuse cached prompt prefixes across turns.

Agent requests often share system instructions, tool definitions, and conversation history. When requests reach different pods, each pod may process the same prefix again. Session affinity helps reuse that work.

Incident Report: vLLM Embeddings Broken by encoding_format Parameter

Sameer Kankute
SWE @ LiteLLM (LLM Translation)
Krrish Dholakia
CEO, LiteLLM
Ishaan Jaffer
CTO, LiteLLM

Date: Feb 16, 2026 Duration: ~3 hours Severity: High (for vLLM embedding users) Status: Resolved

Summary​

A commit (dbcae4a) intended to fix OpenAI SDK behavior broke vLLM embeddings by explicitly passing encoding_format=None in API requests. vLLM rejects this with error: "unknown variant \`, expected float or base64"`.

  • vLLM embedding calls: Complete failure - all requests rejected
  • Other providers: No impact - OpenAI and other providers functioned normally
  • Other vLLM functionality: No impact - only embeddings were affected