19 posts tagged with "complexity-router"

View All Tags

JEV Classifier: 5.43x as Fast as Haiku, 96% Lower Cost
Moe Khalil
Product Engineer, LiteLLM

Last Updated: September 18, 2026

An Auto Router pays for classification before the selected model can answer. In our benchmark, TypeSafe JEV classified requests 5.43x as fast as Haiku, comparing median classifier latency: 126.81 ms versus 688.40 ms. Registry-priced classifier cost was 96.12% lower, rounded to 96% in the title

JEV matched our benchmark's expected tiers on 95.00% of calls, versus 73.75% for Haiku. That result depends on the prompts, tier definitions, instructions and context used here. The expected tiers were authored with the synthetic prompts, without independent review. This comparison does not establish general classification accuracy or the quality of the final answers
Auto-Router: Switching Tiers Without Encrypted Content Failures

Tin Lo
Founding AI Product Engineer, LiteLLM

Auto-Router can move a conversation between tiers as the request changes from simple work to a harder task. Responses API clients can make that switch difficult because a previous response may include encrypted reasoning content that only the deployment that created it can decrypt

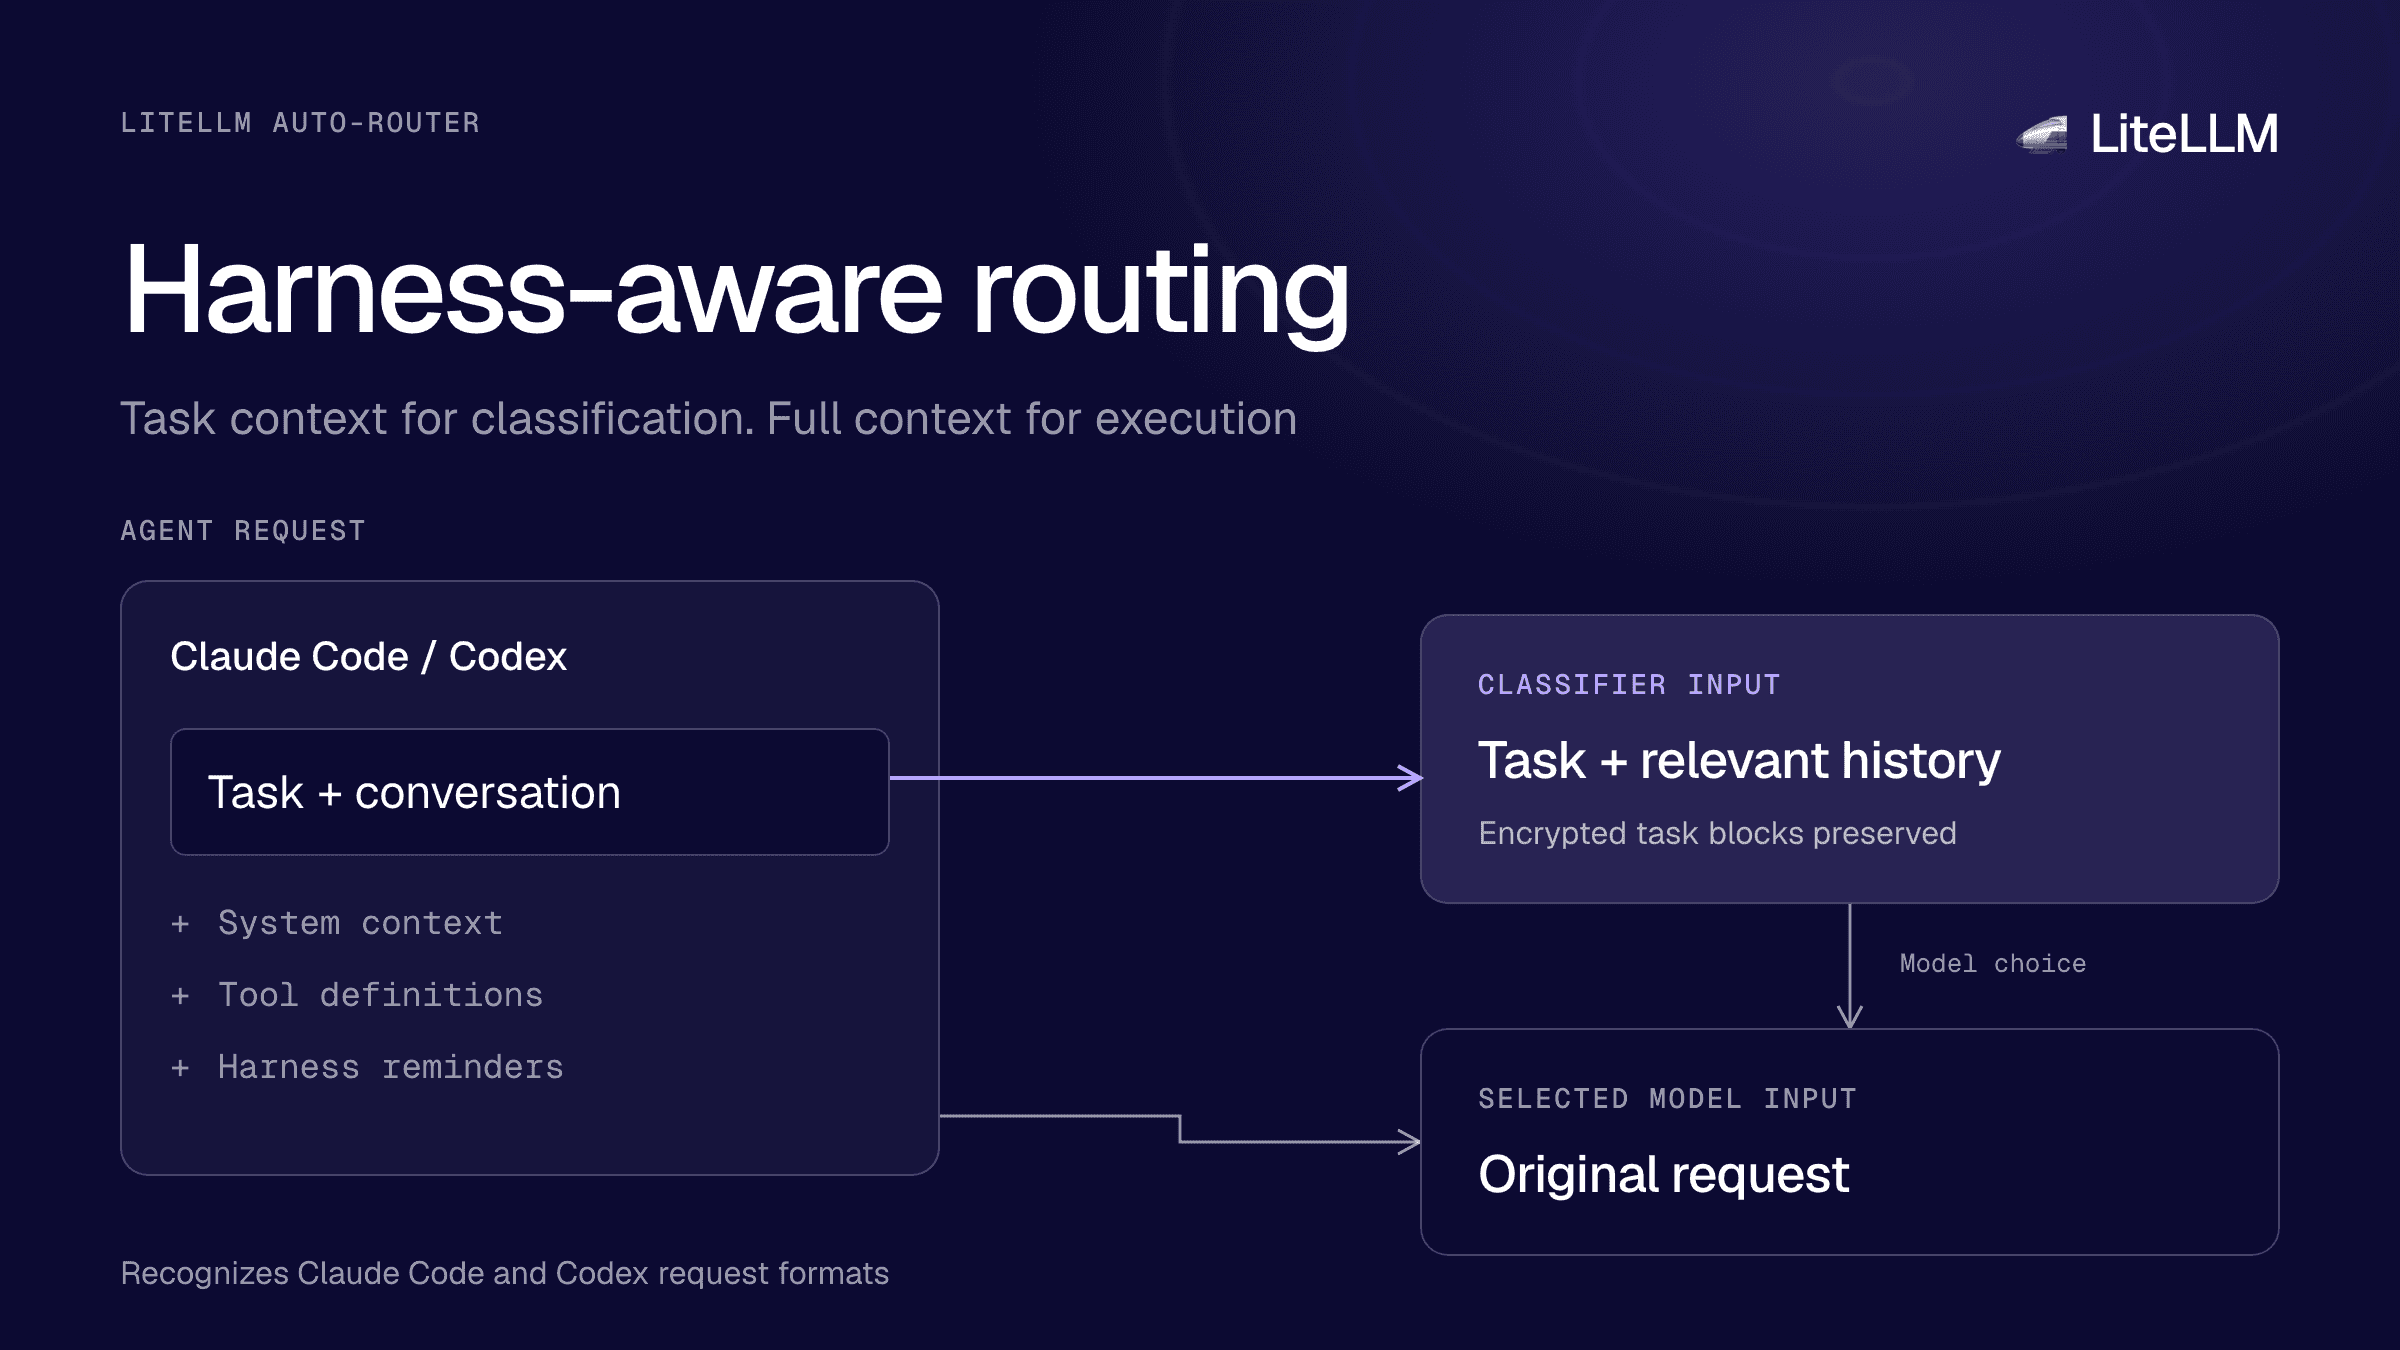
LiteLLM now keeps the readable history and removes encrypted reasoning that the newly selected tier cannot verify. The request can continue to the selected model instead of failing with invalid_encrypted_content

This fix is included in the LiteLLM v1.102.x release line and landed in PR #40280

51% Cost Savings Reported From a Live Production Deployment

Tin Lo
Founding AI Product Engineer, LiteLLM

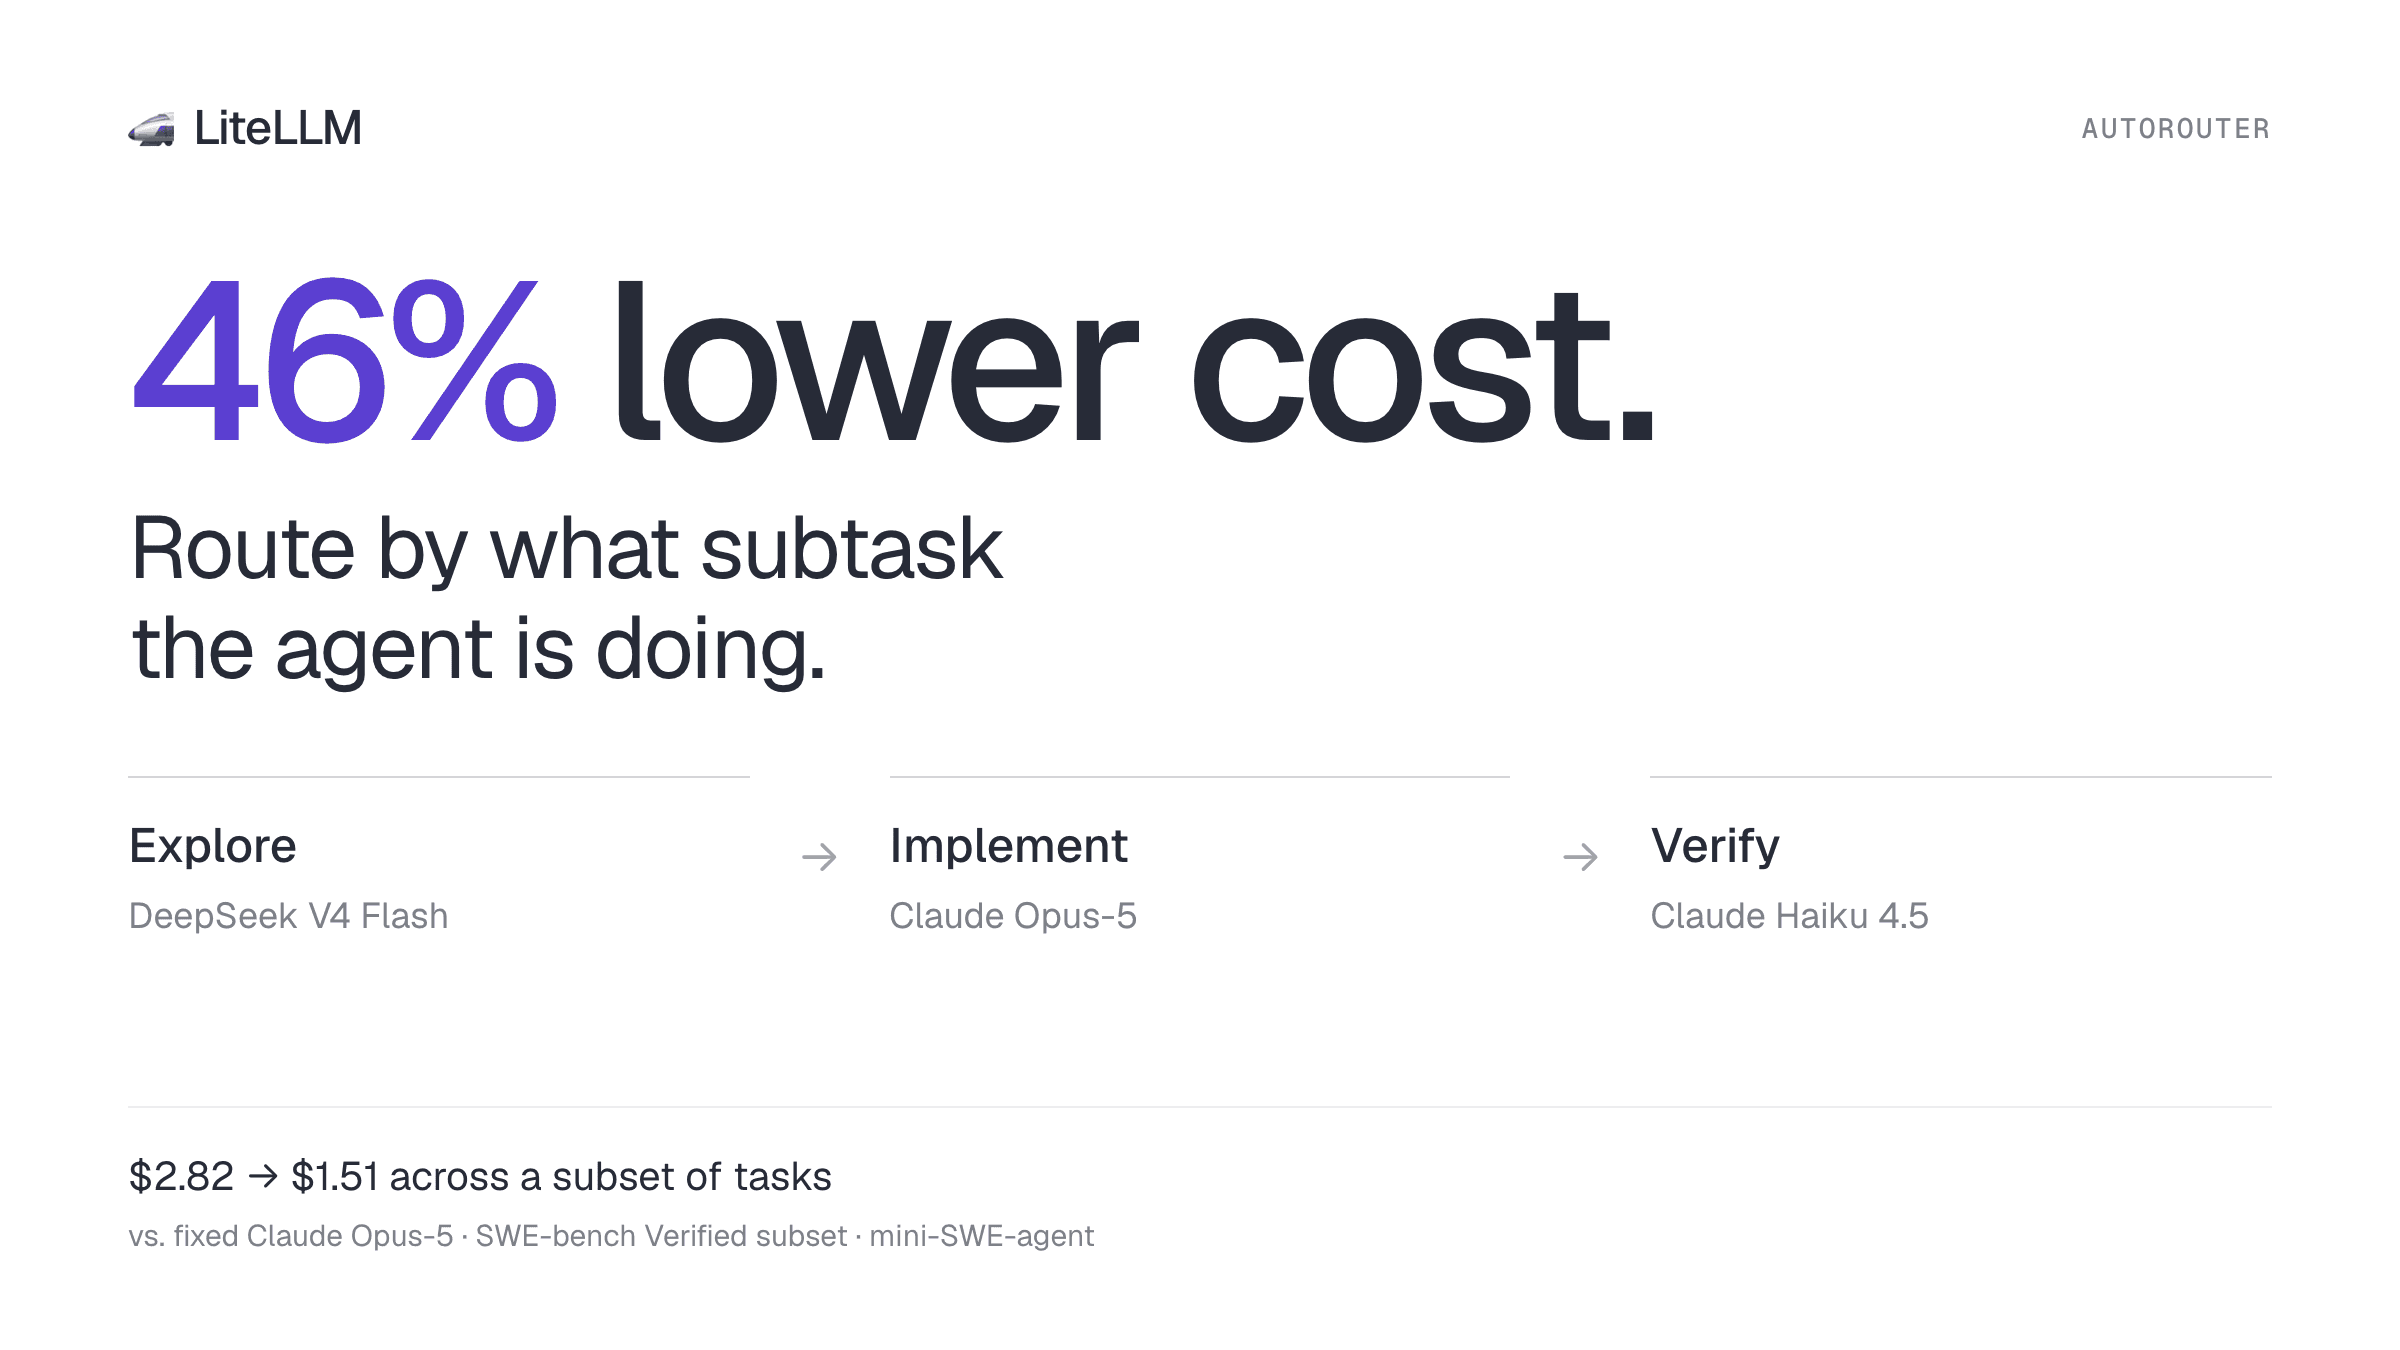
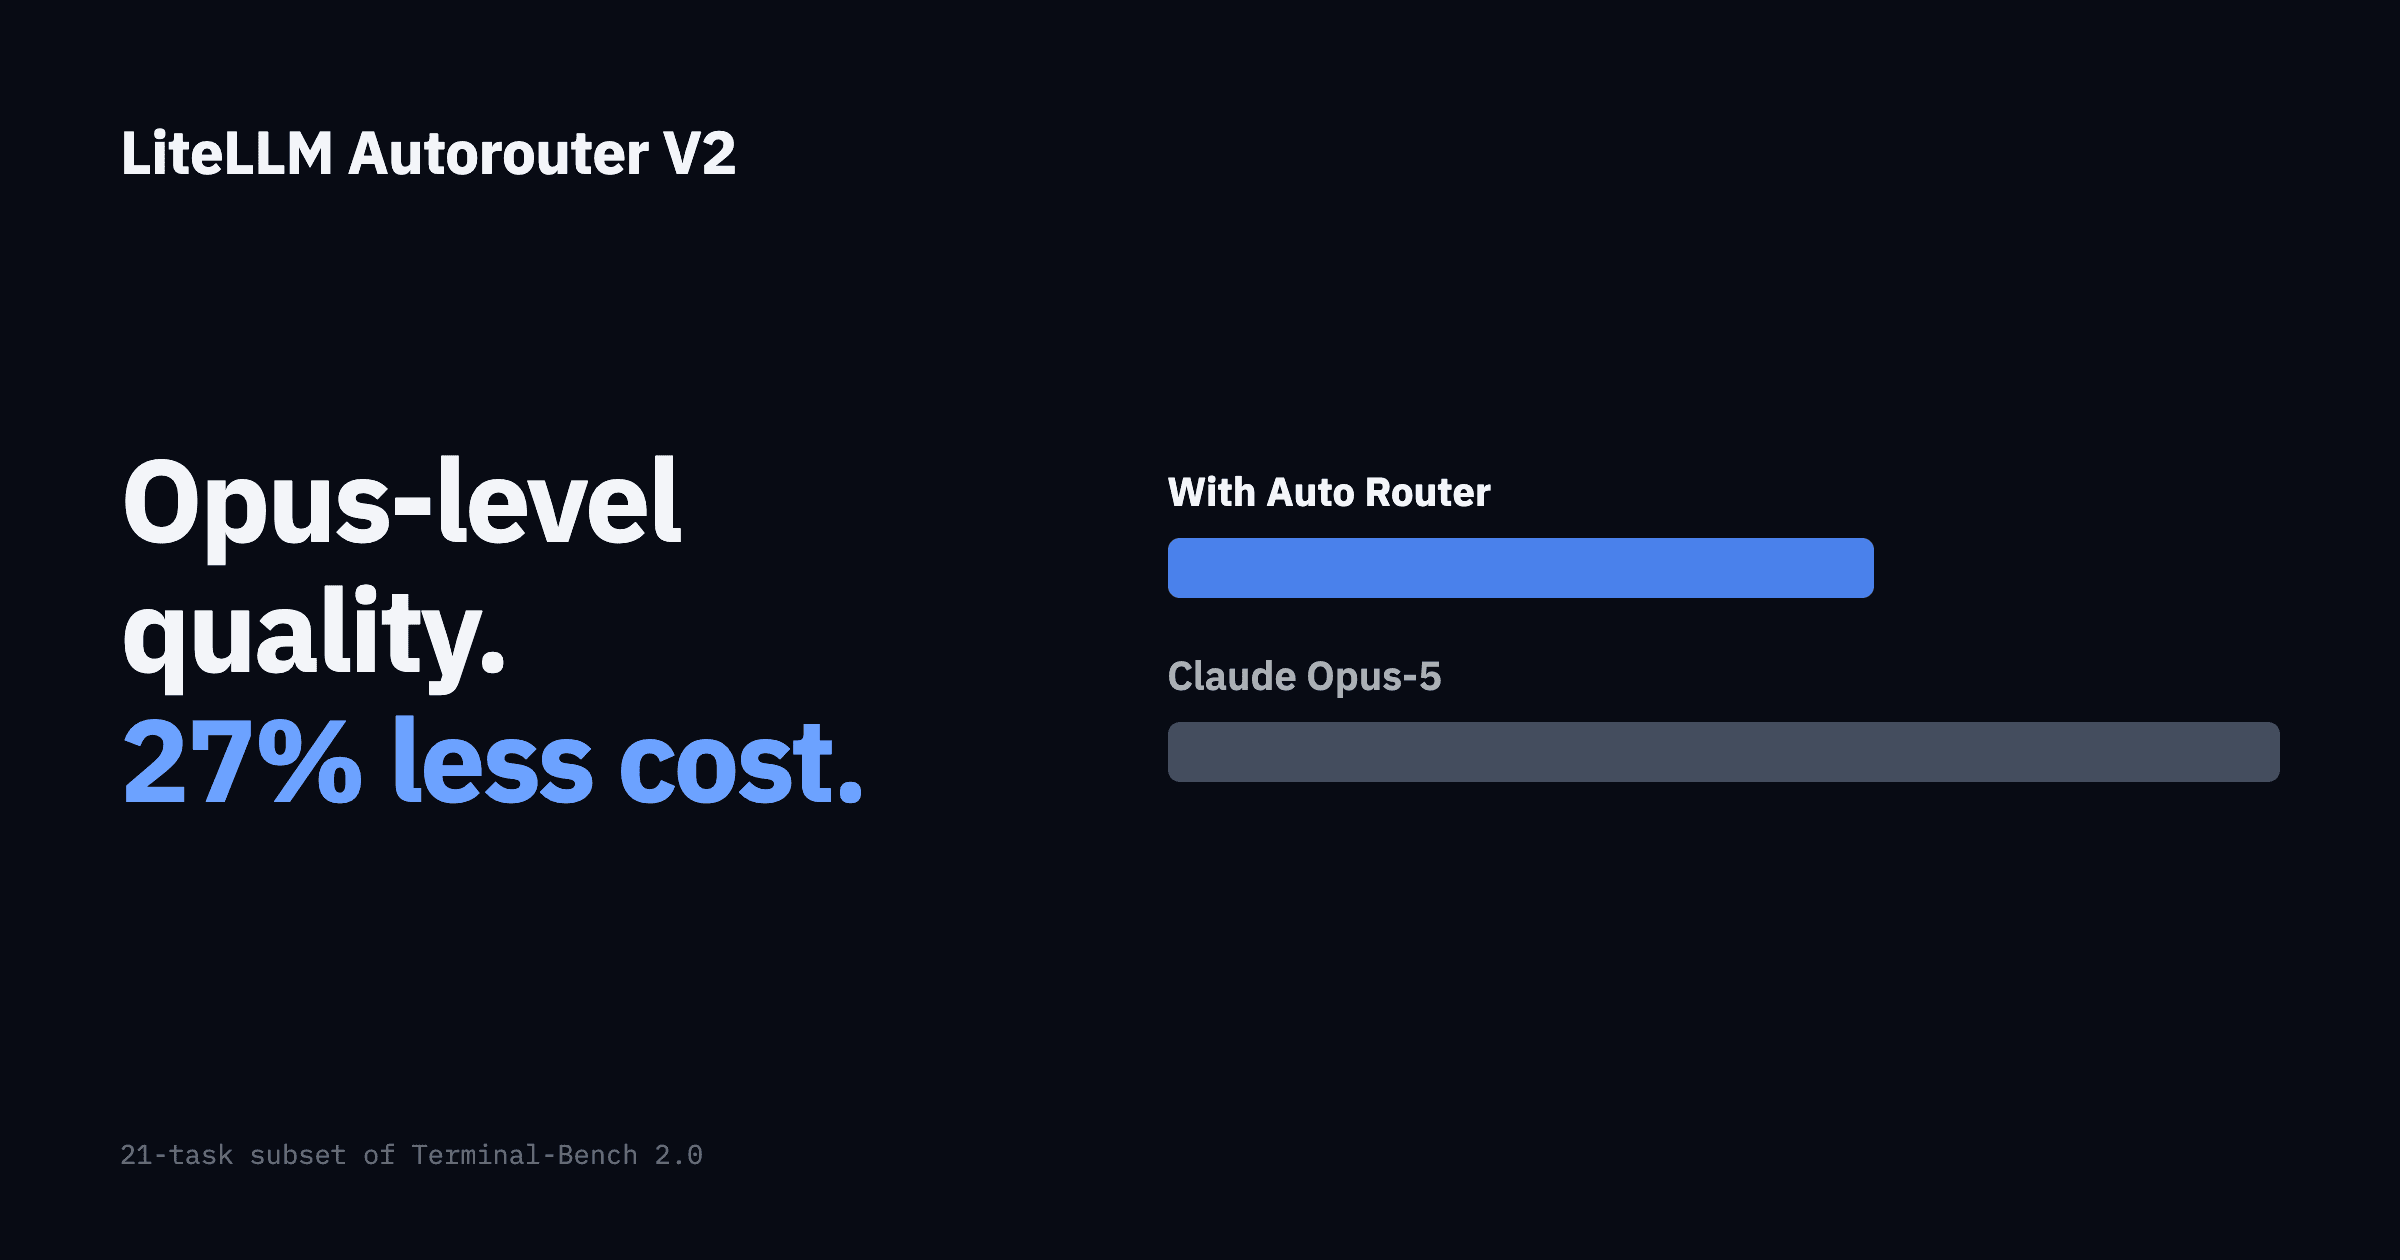
You can expect roughly 40% cost reductions from day one with the Auto Router, and more as the tier maps are tuned. One of our production users shared their statistics to show what that looks like at scale.

They rolled out the Auto-Router to 450+ users across dev, staging, and prod instances and saved $12,249 over 270k+ requests.

Production traffic recorded 51% cost-savings with the Auto-Router

Auto Router v1.97: usage benchmarks and better quality for lower cost

Tin Lo
Founding AI Product Engineer, LiteLLM

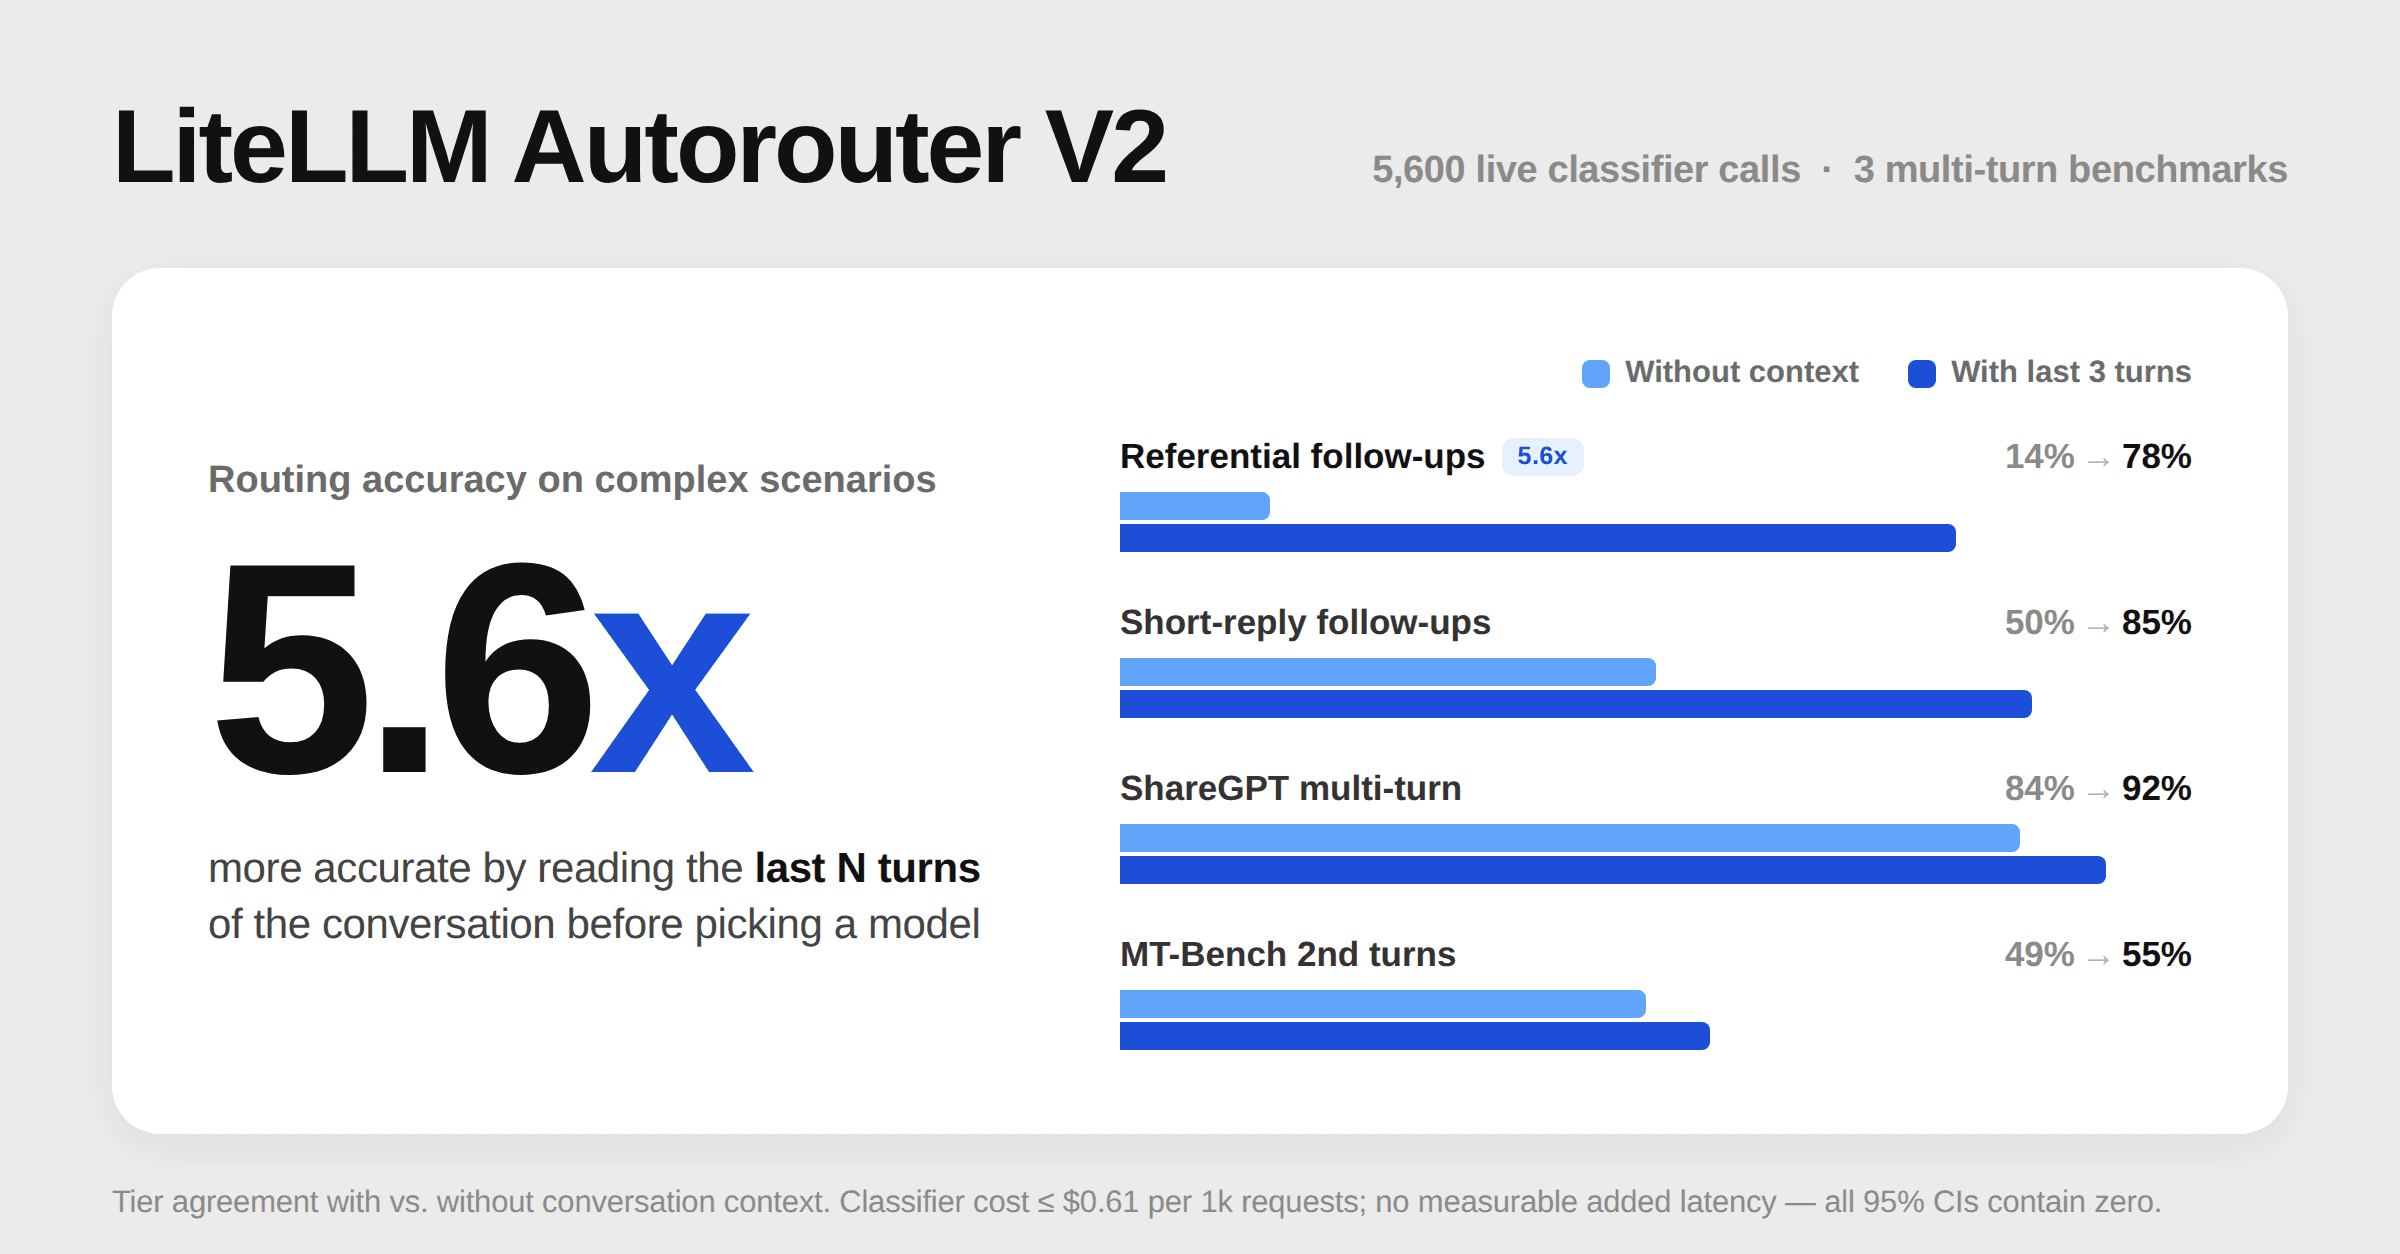
LiteLLM Autorouter V2: routing accuracy on complex scenarios, 5.6x more accurate by reading the last N turns of the conversation before picking a model


🚀 Help shape the Auto-Router

Get early access, work directly with the LiteLLM team, and influence the roadmap with your production traffic.

Apply to Become a Design Partner

Already testing it? Share your results in discussion #32168.

v1.97 makes three changes to the auto router.

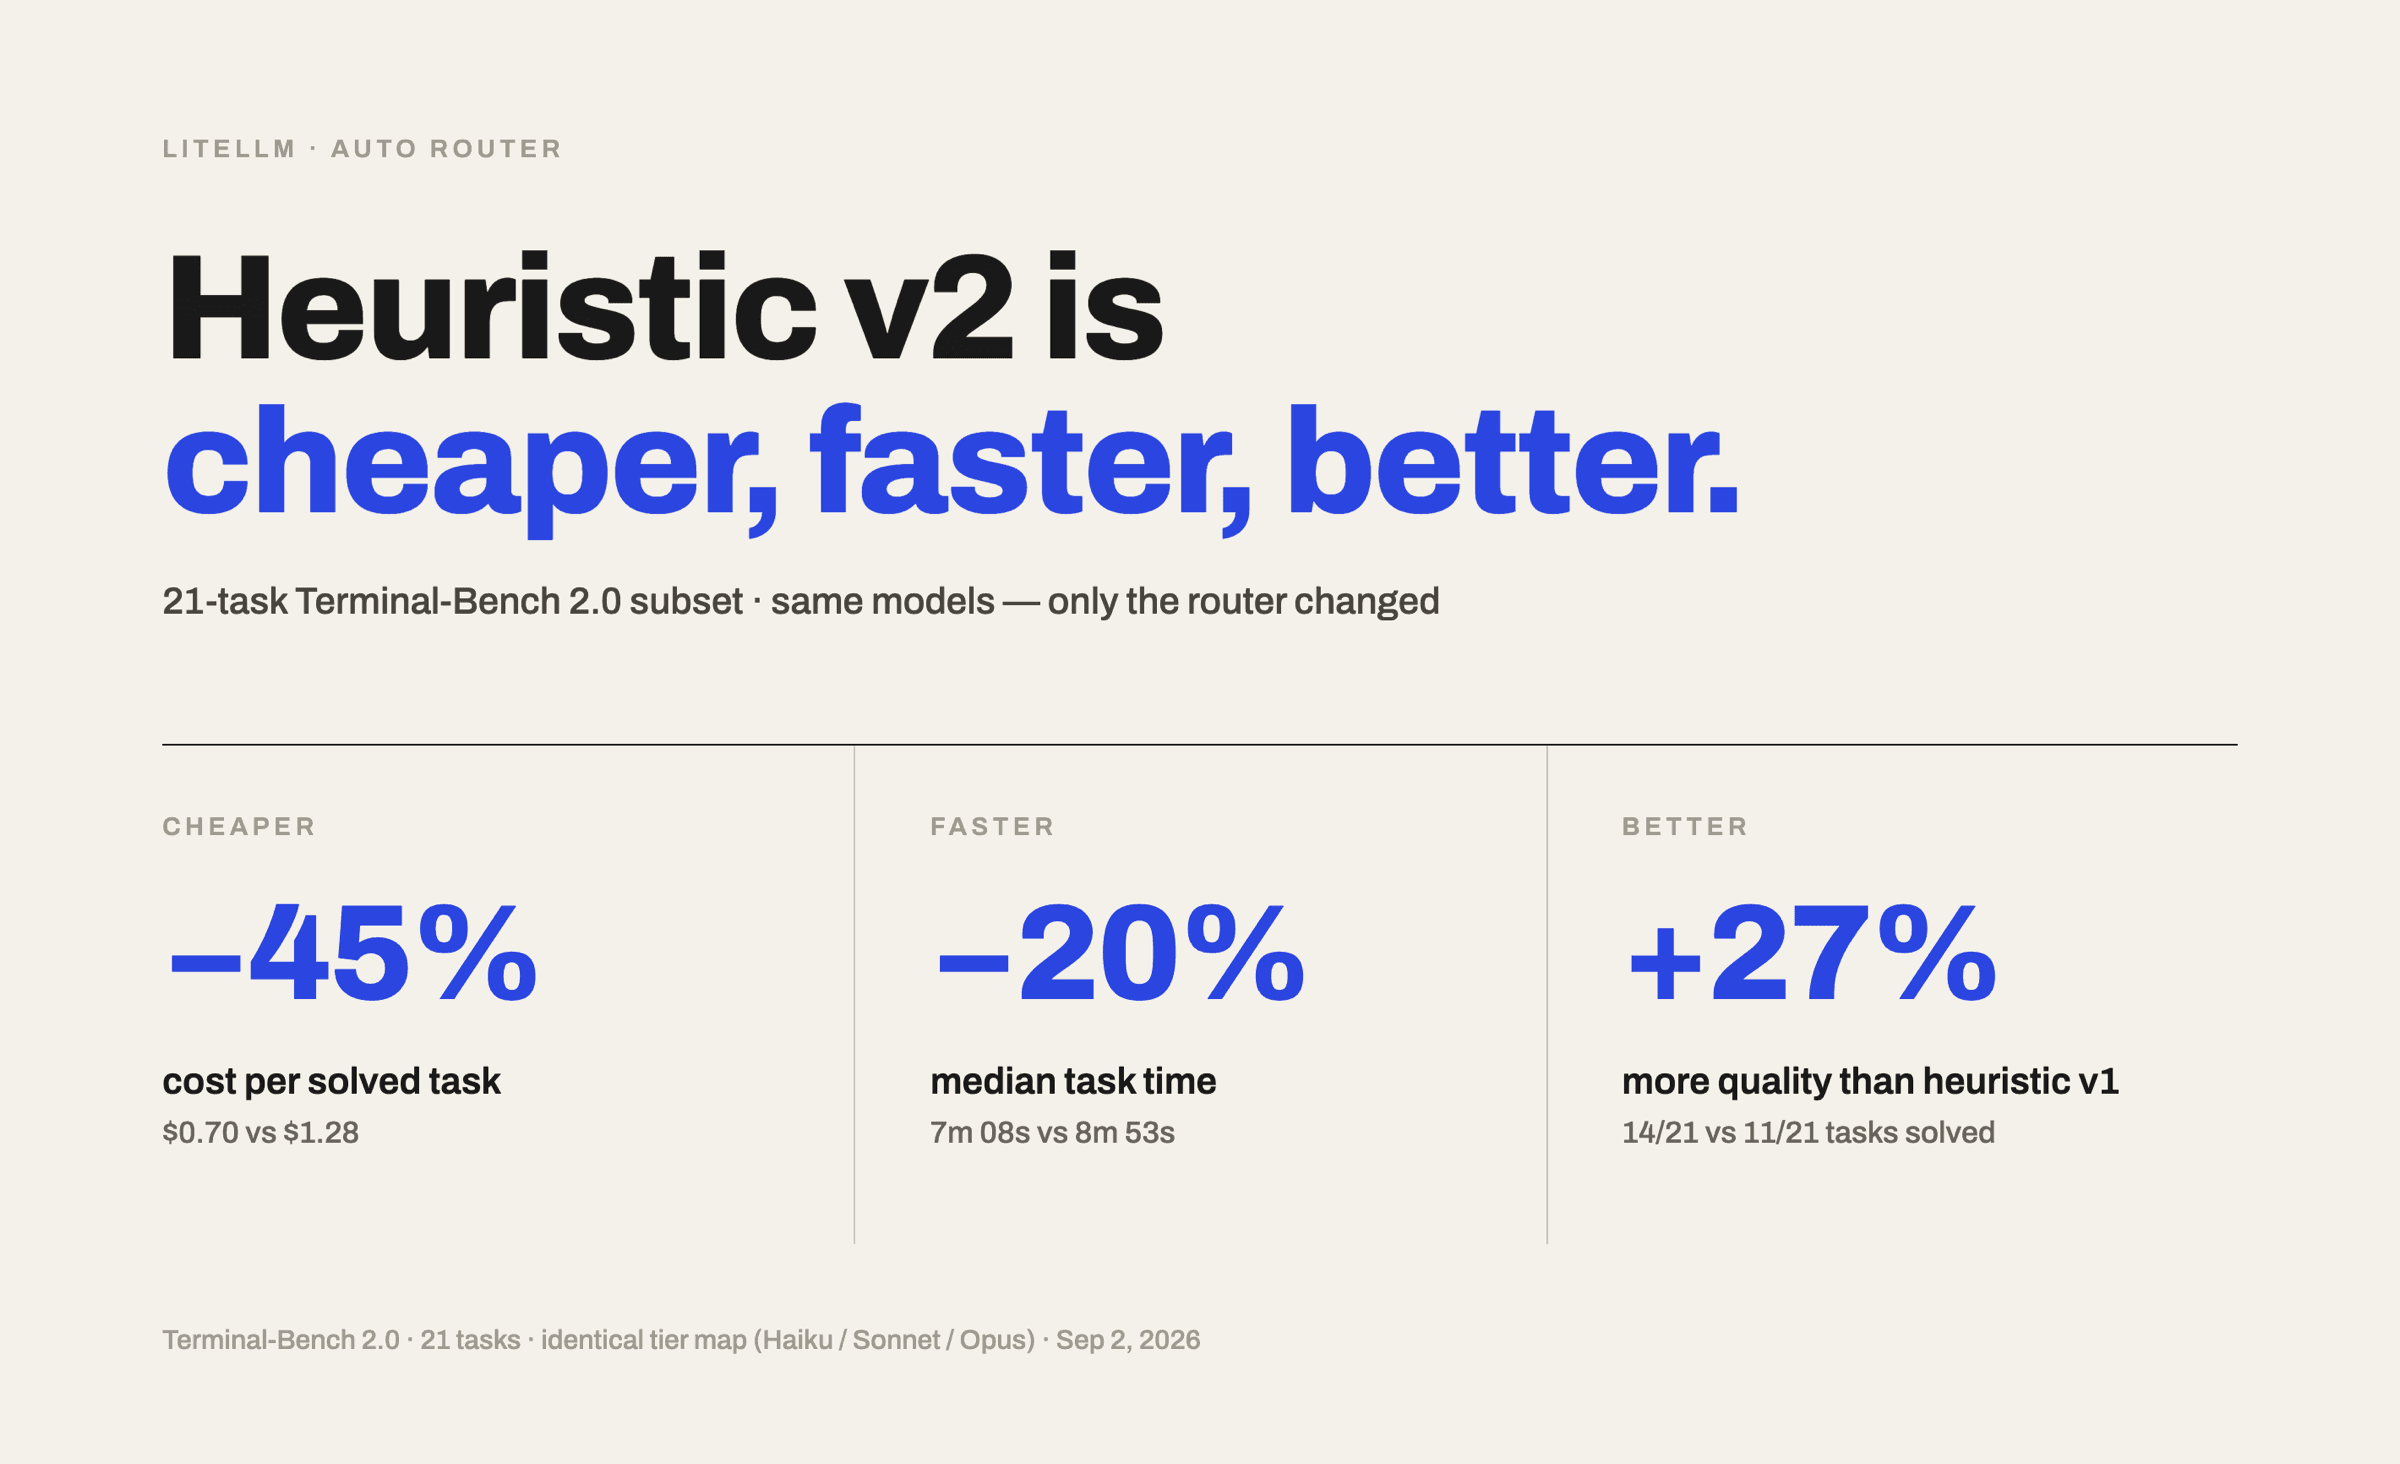
  • The LLM classifier now receives a window of prior conversation turns, defaulting to three. This improves accuracy of follow-up classifications from 14% to 78%, costs at most $0.61 per 1,000 requests, and no additional latency.
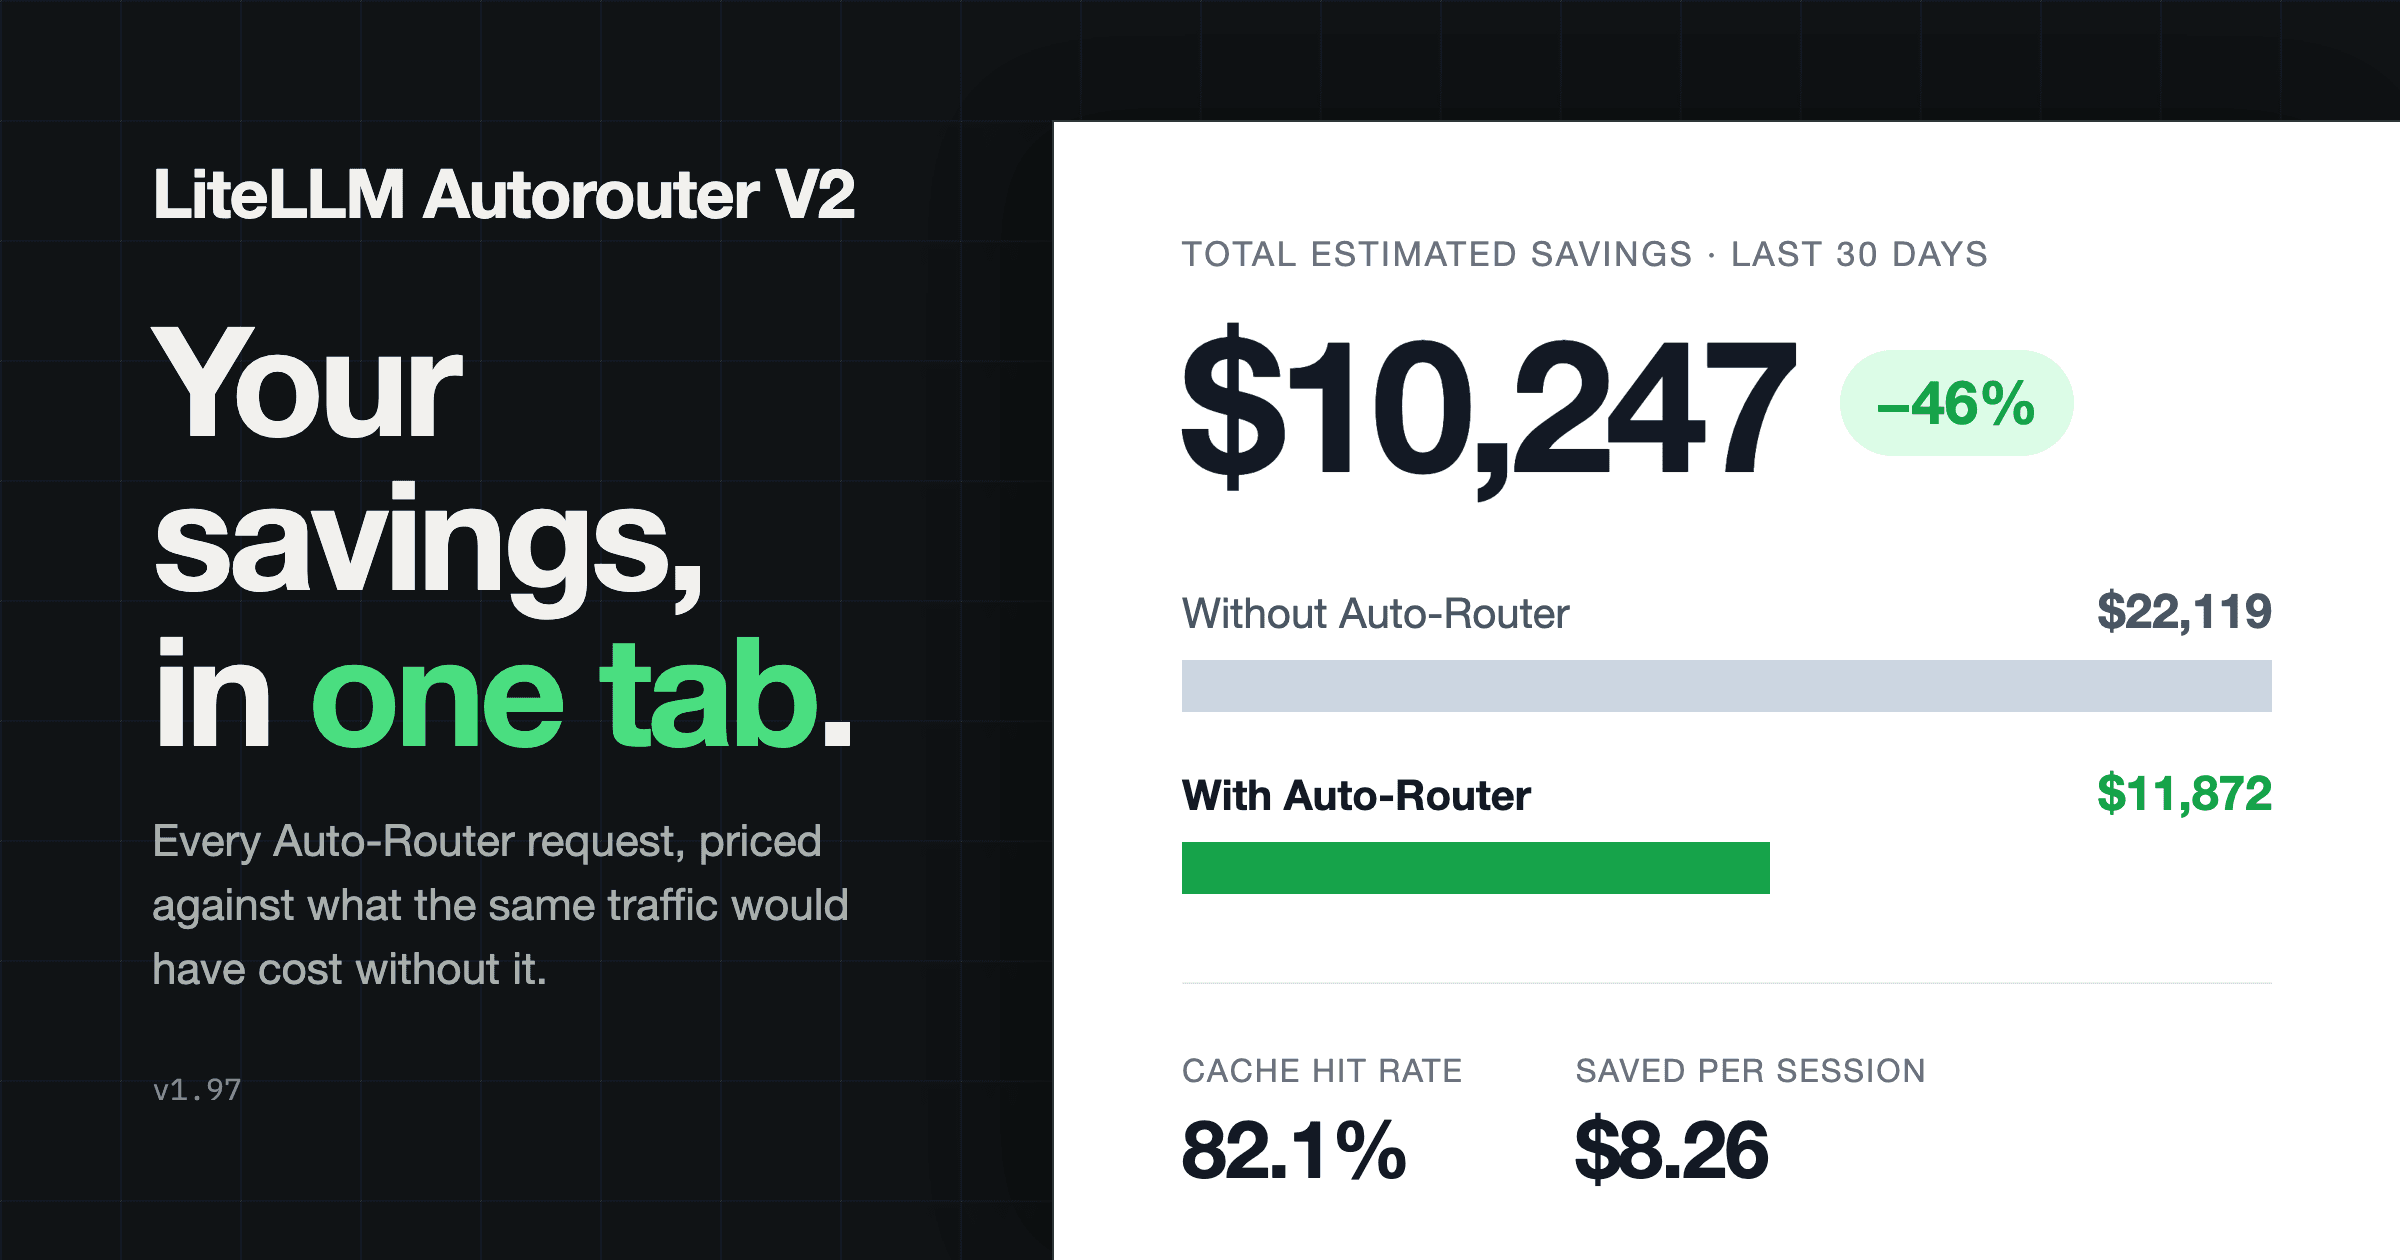
  • A new Benchmarks view prices routed traffic against an all-frontier baseline and reports the difference, and those savings now also appear in the Cost Optimization totals.
  • Session affinity is now off by default, following our previous post showing this was leading to worse quality without cost improvements.
Two defaults changed

classifier_context_window_size now defaults to 3 (LLM classifier only), and session_affinity now defaults to false (all routers). Config files are not modified, but the new defaults apply to any key left unset, so a config that never mentioned session_affinity will reclassify every turn after upgrading. Configs that set either key explicitly are unaffected.

Announcing Router Plugins: Customize Routing Signals

Krrish Dholakia
CEO, LiteLLM
Availability

Router plugins run on the proxy from v1.94.x. The design is still evolving; tell us how you'd use it and what you'd want next in the autorouter discussion on GitHub (#32168).

Router plugins are now available on LiteLLM. Each plugin receives the routing context, enriches it, and hands it to the next before the router makes the final decision.

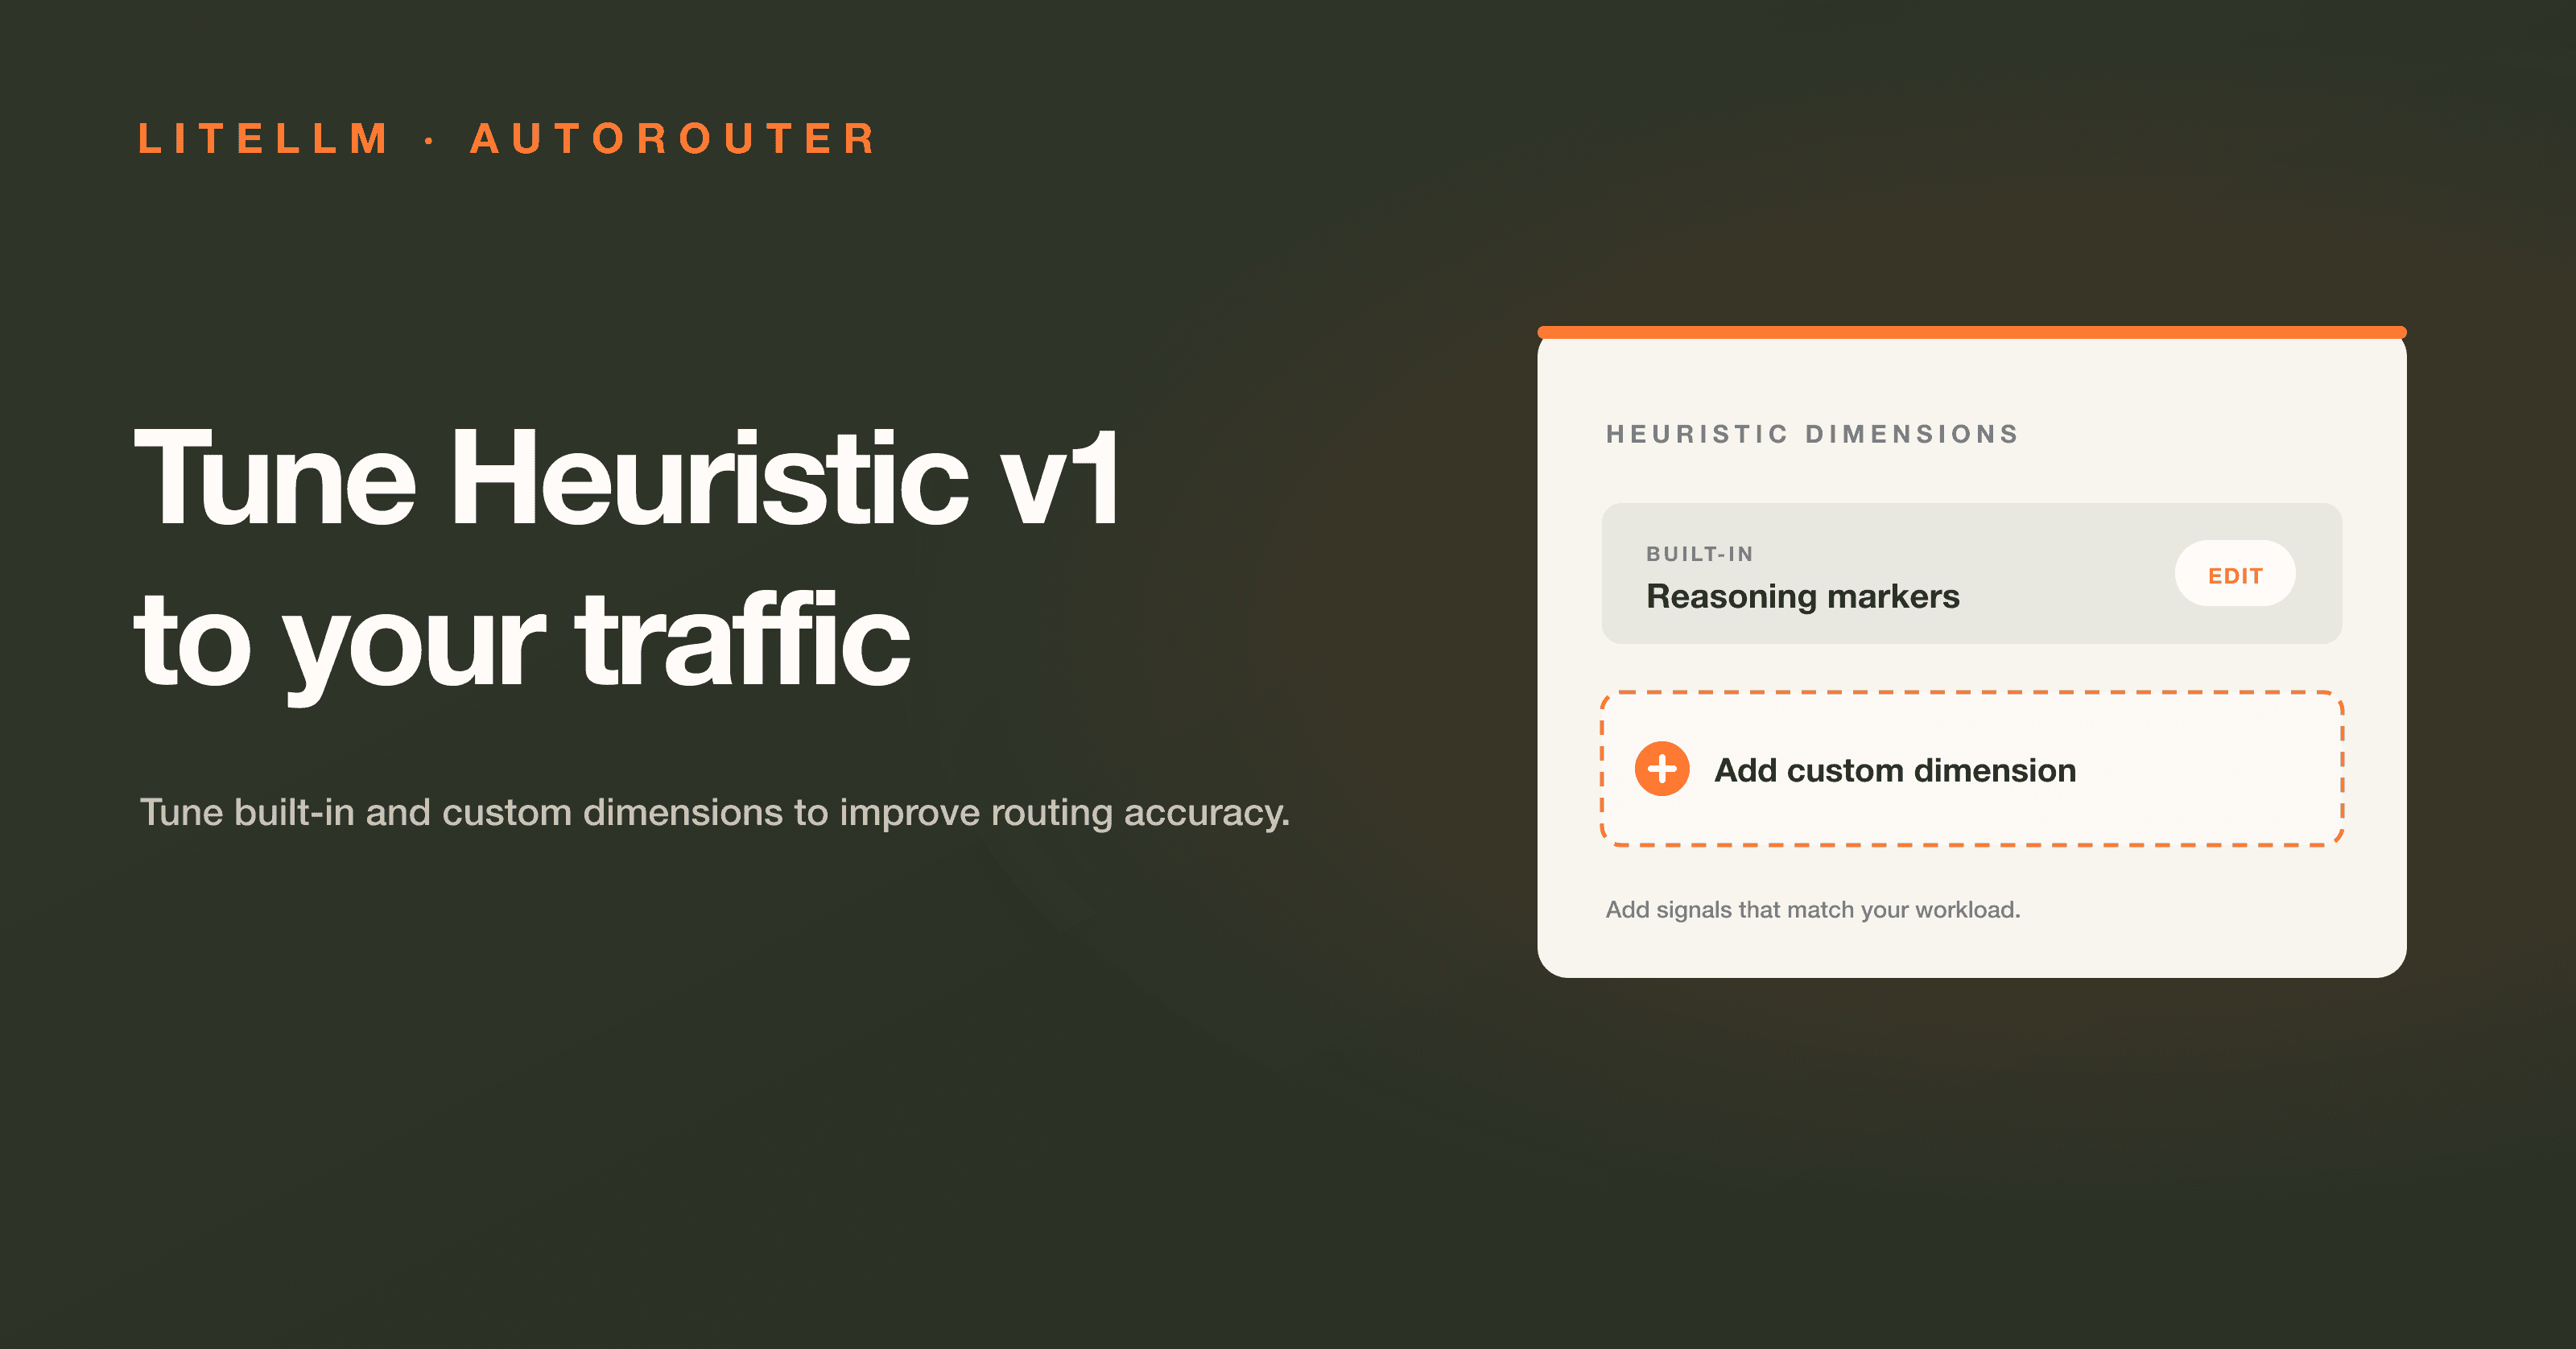
The push came from the autorouter discussion (#32168): teams wanted to layer their own signals (language detection, domain classification, tenant policy, budget caps) onto routing without waiting for each one to land in core. This plugin extension lets teams make these changes while keeping LiteLLM's routing core stable.

Auto Router v2: one router for complexity, semantic, and adaptive routing

Krrish Dholakia
CEO, LiteLLM
Availability

Auto Router v2 ships in v1.94.x. The earliest dev release cuts Tuesday, 2026-07-14. Suggestions and feedback: discussion #32168.

Auto Router v2 collapses complexity, semantic, and adaptive routing into a single auto_router/complexity_router. One config now covers heuristic scoring, LLM classification, lexical or semantic keyword rules, and Thompson-sampled tier pools.

The push came from the community. On discussion #32168, users pointed out that all three routing strategies should converge into a single Auto Router. One router with configurable signals and weights keeps the API simple while letting the routing engine evolve internally, instead of forcing you to pick a mode up front.

The operational half came from discussion #32172: predictable beats clever for debuggability. A fixed, versioned mapping from capability class to model is what makes "why did this response cost 4x today" answerable after the fact.