Modify / Reject Incoming Requests
- Modify data before making llm api calls on proxy
- Reject data before making llm api calls / before returning the response
- Enforce 'user' param for all openai endpoint calls
- Hide models from the model listing per caller
Understanding Callback Hooks? Check out our Callback Guide to understand the differences between proxy-specific hooks like async_pre_call_hook and general logging hooks like async_log_success_event.
Which Hook Should I Use?
| Hook | Use Case | When It Runs |
|---|---|---|
async_pre_call_hook | Modify incoming request before it's sent to model | Before the LLM API call is made |
async_moderation_hook | Run checks on input in parallel to LLM API call | In parallel with the LLM API call |
async_post_call_success_hook | Modify outgoing response (non-streaming) | After successful LLM API call, for non-streaming responses |
async_post_call_failure_hook | Transform error responses sent to clients | After failed LLM API call |
async_post_call_streaming_hook | Modify outgoing response (streaming) | After successful LLM API call, for streaming responses |
async_post_call_response_headers_hook | Inject custom HTTP response headers | After LLM API call (both success and failure) |
async_filter_listed_models | Hide models from the model listing per caller | On the model listing routes, before the response is built |
See a complete example with our parallel request rate limiter
Quick Start
- In your Custom Handler add a new
async_pre_call_hookfunction
This function is called just before a litellm completion call is made, and allows you to modify the data going into the litellm call See Code
from litellm.integrations.custom_logger import CustomLogger
import litellm
from litellm.proxy.proxy_server import UserAPIKeyAuth, DualCache
from litellm.types.utils import ModelResponseStream
from typing import Any, AsyncGenerator, Optional, Literal

# This file includes the custom callbacks for LiteLLM Proxy
# Once defined, these can be passed in proxy_config.yaml
class MyCustomHandler(CustomLogger): # https://docs.litellm.ai/docs/observability/custom_callback#callback-class
    # Class variables or attributes
    def __init__(self):
        pass

    #### CALL HOOKS - proxy only ####

    async def async_pre_call_hook(self, user_api_key_dict: UserAPIKeyAuth, cache: DualCache, data: dict, call_type: Literal[
            "completion",
            "text_completion",
            "embeddings",
            "image_generation",
            "moderation",
            "audio_transcription",
        ]):
        data["model"] = "my-new-model"
        return data

    async def async_post_call_failure_hook(
        self,
        request_data: dict,
        original_exception: Exception,
        user_api_key_dict: UserAPIKeyAuth,
        traceback_str: Optional[str] = None,
    ) -> Optional[HTTPException]:
        """
        Transform error responses sent to clients.

        Return an HTTPException to replace the original error with a user-friendly message.
        Return None to use the original exception.

        Example:
            if isinstance(original_exception, litellm.ContextWindowExceededError):
                return HTTPException(
                    status_code=400,
                    detail="Your prompt is too long. Please reduce the length and try again."
                )
            return None  # Use original exception
        """
        pass

    async def async_post_call_success_hook(
        self,
        data: dict,
        user_api_key_dict: UserAPIKeyAuth,
        response,
    ):
        pass

    async def async_moderation_hook( # call made in parallel to llm api call
        self,
        data: dict,
        user_api_key_dict: UserAPIKeyAuth,
        call_type: Literal["completion", "embeddings", "image_generation", "moderation", "audio_transcription"],
    ):
        pass

    async def async_post_call_streaming_hook(
        self,
        user_api_key_dict: UserAPIKeyAuth,
        response: str,
    ):
        pass

    async def async_post_call_streaming_iterator_hook(
        self,
        user_api_key_dict: UserAPIKeyAuth,
        response: Any,
        request_data: dict,
    ) -> AsyncGenerator[ModelResponseStream, None]:
        """
        Passes the entire stream to the guardrail

        This is useful for plugins that need to see the entire stream.
        """
        async for item in response:
            yield item

    async def async_post_call_response_headers_hook(
        self,
        data: dict,
        user_api_key_dict: UserAPIKeyAuth,
        response: Any,
        request_headers: Optional[Dict[str, str]] = None,
    ) -> Optional[Dict[str, str]]:
        """
        Inject custom headers into HTTP response (runs for both success and failure).
        """
        return {"x-custom-header": "custom-value"}

proxy_handler_instance = MyCustomHandler()
The last line matters: callbacks takes the dotted path of an instance, so the file has to create one
- Add this file to your proxy config
model_list:
  - model_name: gpt-5.6-luna
    litellm_params:
      model: gpt-5.6-luna

litellm_settings:
  callbacks: custom_callbacks.proxy_handler_instance # sets litellm.callbacks = [proxy_handler_instance]
Point callbacks at the class (custom_callbacks.MyCustomHandler) rather than the instance and the proxy fails config load with an error naming the entry and what it resolved to. The proxy only dispatches CustomLogger instances, so on versions before that check it started clean, served traffic and never ran your hooks, with no error and no log line
- Start the server + test the request
$ litellm /path/to/config.yaml
curl --location 'http://0.0.0.0:4000/chat/completions' \
    --data ' {
    "model": "gpt-5.6-luna",
    "messages": [
        {
        "role": "user",
        "content": "good morning good sir"
        }
    ],
    "user": "ishaan-app",
    "temperature": 0.2
    }'
[BETA] NEW async_moderation_hook
Run a moderation check in parallel to the actual LLM API call.
Subclass CustomGuardrail and define an async_moderation_hook function
- Register the guardrail under
guardrails:withmode: during_call. The hook must acceptdata,user_api_key_dictandcall_type; the older two-argument signature fails with aTypeErroron every request. - This function runs in parallel to the actual LLM API call.
- If your
async_moderation_hookraises an Exception, we will return that to the user.
See a complete example with our Llama Guard content moderation hook and the custom guardrail docs
from litellm.integrations.custom_guardrail import CustomGuardrail
from litellm.proxy._types import UserAPIKeyAuth
from litellm.types.utils import CallTypesLiteral
from fastapi import HTTPException

class MyCustomGuardrail(CustomGuardrail):
    def __init__(self, **kwargs):
        super().__init__(**kwargs)

    async def async_moderation_hook( ### 👈 KEY CHANGE ###
        self,
        data: dict,
        user_api_key_dict: UserAPIKeyAuth,
        call_type: CallTypesLiteral,
    ):
        messages = data["messages"]
        print(messages)
        if messages[0]["content"] == "hello world":
            raise HTTPException(
                    status_code=400, detail={"error": "Violated content safety policy"}
                )
- Add this file to your proxy config
model_list:
  - model_name: gpt-5.6-luna
    litellm_params:
      model: gpt-5.6-luna

guardrails:
  - guardrail_name: "my-moderation-guardrail"
    litellm_params:
      guardrail: custom_guardrail.MyCustomGuardrail # {file_name}.{class_name}
      mode: "during_call"
      default_on: true
- Start the server + test the request
$ litellm /path/to/config.yaml
curl --location 'http://0.0.0.0:4000/chat/completions' \
    --data ' {
    "model": "gpt-5.6-luna",
    "messages": [
        {
        "role": "user",
        "content": "Hello world"
        }
    ],
    }'
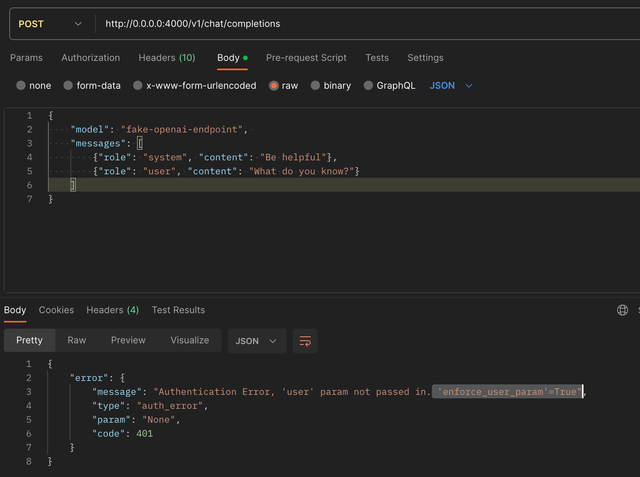
Advanced - Enforce 'user' param
Set enforce_user_param to true, to require all calls to the openai endpoints to have the 'user' param.
general_settings:
  enforce_user_param: True
Result
Advanced - Return rejected message as response
For chat completions and text completion calls, you can return a rejected message as a user response.
Do this by returning a string. LiteLLM takes care of returning the response in the correct format depending on the endpoint and if it's streaming/non-streaming.
For non-chat/text completion endpoints, this response is returned as a 400 status code exception.
1. Create Custom Handler
from litellm.integrations.custom_logger import CustomLogger
import litellm
from litellm.utils import get_formatted_prompt

# This file includes the custom callbacks for LiteLLM Proxy
# Once defined, these can be passed in proxy_config.yaml
class MyCustomHandler(CustomLogger):
    def __init__(self):
        pass

    #### CALL HOOKS - proxy only ####

    async def async_pre_call_hook(self, user_api_key_dict: UserAPIKeyAuth, cache: DualCache, data: dict, call_type: Literal[
            "completion",
            "text_completion",
            "embeddings",
            "image_generation",
            "moderation",
            "audio_transcription",
        ]) -> Optional[dict, str, Exception]:
        formatted_prompt = get_formatted_prompt(data=data, call_type=call_type)

        if "Hello world" in formatted_prompt:
            return "This is an invalid response"

        return data

proxy_handler_instance = MyCustomHandler()
2. Update config.yaml
model_list:
  - model_name: gpt-5.6-luna
    litellm_params:
      model: gpt-5.6-luna

litellm_settings:
  callbacks: custom_callbacks.proxy_handler_instance # sets litellm.callbacks = [proxy_handler_instance]
3. Test it!
$ litellm /path/to/config.yaml
curl --location 'http://0.0.0.0:4000/chat/completions' \
    --data ' {
    "model": "gpt-5.6-luna",
    "messages": [
        {
        "role": "user",
        "content": "Hello world"
        }
    ],
    }'
Expected Response
{
    "id": "chatcmpl-d00bbede-2d90-4618-bf7b-11a1c23cf360",
    "choices": [
        {
            "finish_reason": "stop",
            "index": 0,
            "message": {
                "content": "This is an invalid response.", # 👈 REJECTED RESPONSE
                "role": "assistant"
            }
        }
    ],
    "created": 1716234198,
    "model": null,
    "object": "chat.completion",
    "system_fingerprint": null,
    "usage": {}
}
Advanced - Transform Error Responses
Transform technical API errors into user-friendly messages using async_post_call_failure_hook. Return an HTTPException to replace the original error, or None to use the original exception.
from litellm.integrations.custom_logger import CustomLogger
from fastapi import HTTPException
from typing import Optional
import litellm

class MyErrorTransformer(CustomLogger):
    async def async_post_call_failure_hook(
        self,
        request_data: dict,
        original_exception: Exception,
        user_api_key_dict: UserAPIKeyAuth,
        traceback_str: Optional[str] = None,
    ) -> Optional[HTTPException]:
        if isinstance(original_exception, litellm.ContextWindowExceededError):
            return HTTPException(
                status_code=400,
                detail="Your prompt is too long. Please reduce the length and try again."
            )
        if isinstance(original_exception, litellm.RateLimitError):
            return HTTPException(
                status_code=429,
                detail="Rate limit exceeded. Please try again in a moment."
            )
        return None  # Use original exception

proxy_handler_instance = MyErrorTransformer()
Result: Clients receive "Your prompt is too long..." instead of "ContextWindowExceededError: Prompt exceeds context window".
Advanced - Inject Custom HTTP Response Headers
Use async_post_call_response_headers_hook to inject custom HTTP headers into responses. This hook runs for both successful and failed LLM API calls.
from litellm.integrations.custom_logger import CustomLogger
from litellm.proxy.proxy_server import UserAPIKeyAuth
from typing import Any, Dict, Optional

class CustomHeaderLogger(CustomLogger):
    def __init__(self):
        super().__init__()

    async def async_post_call_response_headers_hook(
        self,
        data: dict,
        user_api_key_dict: UserAPIKeyAuth,
        response: Any,
        request_headers: Optional[Dict[str, str]] = None,
    ) -> Optional[Dict[str, str]]:
        """
        Inject custom headers into all responses (success and failure).
        """
        return {"x-custom-header": "custom-value"}

proxy_handler_instance = CustomHeaderLogger()
Advanced - Hide models from the model listing
async_pre_call_hook can reject a model at request time, but the model still shows up in GET /v1/models, so a client's model picker lists entries that only fail later with a 403. async_filter_listed_models closes that gap. It runs on the model listing routes with the model names the caller would otherwise see and returns the subset to keep. Ships with PR #43027
async def async_filter_listed_models(
    self,
    user_api_key_dict: UserAPIKeyAuth,
    model_names: Sequence[str],
) -> Sequence[str]:
    return model_names
A name left out of the return value disappears from every listing, and the routes that look one model up answer as if it did not exist
| Route | Hidden model |
|---|---|
GET /v1/models, GET /models | Left out |
GET /v1/models/{model_id}, GET /models/{model_id} | 404, as for an unknown model |
GET /model/info, GET /v1/model/info | Left out |
GET /model/info?litellm_model_id=<id> | 400, as for an unknown deployment id |
GET /model_group/info | Left out, a2a/<agent> groups included |
The /v1/models filter applies to the OpenAI and the Anthropic response shape alike, and to ?scope=expand. /v2/model/info and the auto-router routes are untouched, and so is inference. A caller who knows a hidden name can still call it unless async_pre_call_hook rejects it, so pair the two hooks as in the example below
The hook is offered the public model names the caller would see, so a team model arrives under its public name rather than its internal routing name. Key and team aliases are never offered; they are added after the filter and only resolve to a target the filter kept. A router model_group_alias whose target is hidden is hidden too. Names in the return value that were not offered are ignored and the offered order is kept, so a callback can only narrow the listing, never widen it
The hook runs for every caller, proxy admins included. user_api_key_dict tells the callback who is asking (user_role, team_id, user_id and so on), so exempt admins in the callback when they should keep seeing everything. When several registered callbacks override the hook they run in registration order, each one seeing what the previous one kept, so a name has to survive all of them. A callback that does not override the hook is never called, and with no such callback the listing routes behave exactly as before
The return value must be a sequence of strings. A bare string, None or anything else makes the proxy raise a TypeError naming the callback class rather than silently emptying the listing (a bare string would otherwise be walked character by character). An exception raised inside the hook propagates to the caller, so a broken entitlement service fails loud instead of leaking the full list. Each callback is awaited once per listing request, so a slow entitlement lookup slows the listing by that much; cache the answer inside the callback if the lookup is expensive
1. Create Custom Handler
gate.py pairs the request-time rejection with the listing filter, so the hidden model is neither listed nor callable
from collections.abc import Sequence

from fastapi import HTTPException
from litellm.integrations.custom_logger import CustomLogger
from litellm.proxy._types import UserAPIKeyAuth

RESTRICTED = {"restricted-model"}


class Gate(CustomLogger):
    async def async_pre_call_hook(self, user_api_key_dict, cache, data, call_type):
        if data.get("model") in RESTRICTED:
            raise HTTPException(status_code=403, detail="not entitled to this model")
        return data

    async def async_filter_listed_models(
        self, user_api_key_dict: UserAPIKeyAuth, model_names: Sequence[str]
    ) -> Sequence[str]:
        return [name for name in model_names if name not in RESTRICTED]


gate = Gate()
2. Update config.yaml
model_list:
  - model_name: open-model
    litellm_params:
      model: gpt-5.6-luna
      api_key: os.environ/OPENAI_API_KEY
  - model_name: restricted-model
    litellm_params:
      model: gpt-5.6-luna
      api_key: os.environ/OPENAI_API_KEY

litellm_settings:
  callbacks: gate.gate # sets litellm.callbacks = [gate]

general_settings:
  master_key: os.environ/LITELLM_MASTER_KEY
3. Test it!
$ litellm /path/to/config.yaml
The master key is the proxy admin, and the example hides restricted-model from it too, since the hook runs for every caller
curl -s http://0.0.0.0:4000/v1/models \
    -H "Authorization: Bearer $LITELLM_MASTER_KEY" | jq "[.data[].id]"
Expected Response
["open-model"]
Fetching the hidden model by id answers 404, the same as a model that does not exist
curl -s http://0.0.0.0:4000/v1/models/restricted-model \
    -H "Authorization: Bearer $LITELLM_MASTER_KEY"
{"detail":"The model `restricted-model` does not exist or is not accessible"}