Benchmark: flagging problems in agent traces
This benchmark uses decision models to find LiteLLM Lens signals in agent traces. Each model received the same 621 yes/no questions for 207 test traces, three per trace. For each question, the model also picked the part of the trace that shows the problem, or none
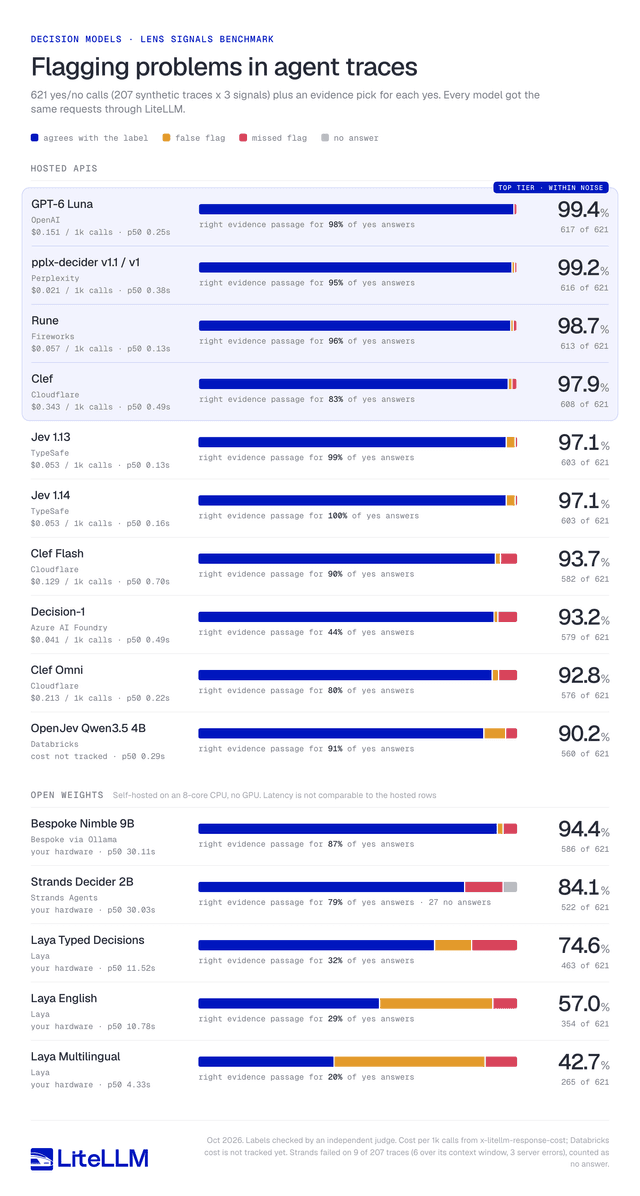
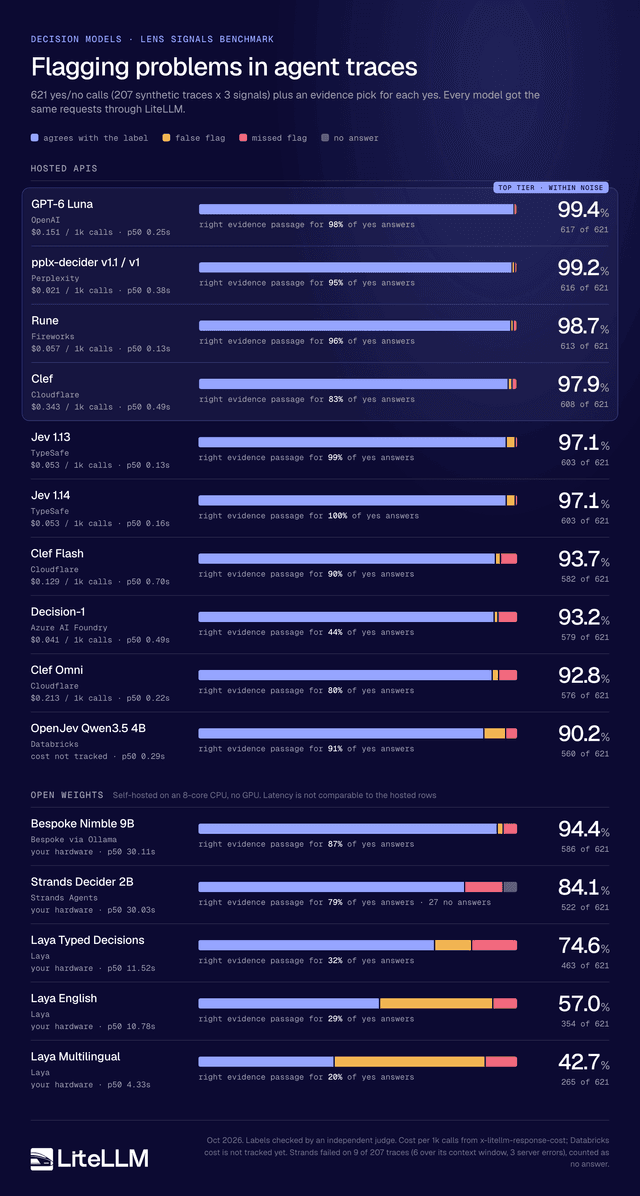
GPT-6 Luna, Perplexity, Fireworks Rune and Cloudflare Clef agree with the labels on 97.9% to 99.4% of the questions. Decision-1 agrees on 93.2%, but it picks the right part of the trace for only 44% of the questions whose label is yes. Bespoke Nimble 9B gives the best self-hosted result, 94.4%
The traces are short and synthetic, about six steps each, so real traffic is harder and the top scores sit close together. An OpenAI model wrote the traces, which can give OpenAI models a small advantage. A Claude model checked every label before the runs, and the 13 traces where it disagreed were left out
On the chart, "right evidence passage for X% of yes answers" is the share of the questions whose label is yes where the model picked a part of the trace that the label marks as evidence. That is 157 questions for every model but Strands Decider 2B, which answered 155 of them. The chart's subtitle counts each of the 621 questions as a call, but its cost and p50 latency are per request, and one request asks all three questions for one trace, so $0.151 / 1k calls means $0.151 for 1k traces. Cost is the x-litellm-response-cost header, and the self-hosted models ran on an 8-core CPU, so their latency does not compare with the hosted models
pplx-decider v1 and v1.1 gave the same scores and picks on every trace, so the chart shows them as one bar. Databricks ai_decide and OpenJev gave the same yes or no answer on every question, and the chart shows the OpenJev run. LiteLLM sends null for an evidence option that has no description, and Strands Decider 2B answers that with a 422, so its run gave each option a short description such as excerpt L000. It still could not fit 6 traces in its context window and returned a 500 on 3 more, so those 27 questions count as no answer
Download the traces, labels, per-request results and scripts to check these numbers or to run the same questions against other models. The archive has a README with the rerun commands and a SHA256SUMS file for the frozen inputs