LiteLLM Proxy Performance
The numbers on this page compare the proxy against calling a provider directly. For gateway capacity numbers (requests, tokens, and latency per pod at scale) see Benchmarks.
Throughput - 30% Increase
LiteLLM proxy + Load Balancer gives 30% increase in throughput compared to Raw OpenAI API

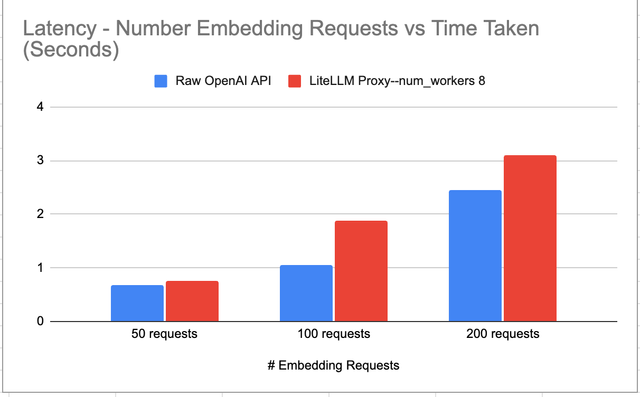
Latency Added - 0.00325 seconds
LiteLLM proxy adds 0.00325 seconds latency as compared to using the Raw OpenAI API